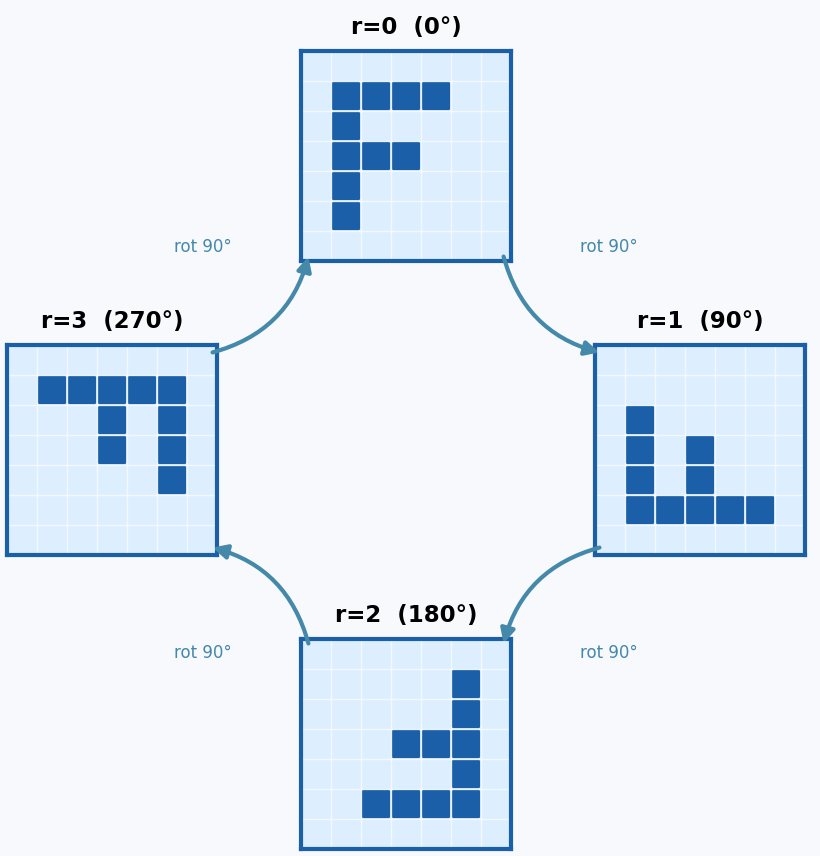
<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://yassermb.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://yassermb.github.io/" rel="alternate" type="text/html" /><updated>2026-09-28T10:19:48+00:00</updated><id>https://yassermb.github.io/feed.xml</id><title type="html">Yasser Mohseni</title><subtitle>Yasser Mohseni, PhD - Associate Professor at Université Paris Cité, working at the intersection of computational biology and deep learning, with a focus on proteins, molecular interactions, and antibody/nanobody design.</subtitle><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><entry><title type="html">How group convolutional networks exploit symmetry</title><link href="https://yassermb.github.io/posts/2026/07/by2/" rel="alternate" type="text/html" title="How group convolutional networks exploit symmetry" /><published>2026-07-15T00:00:00+00:00</published><updated>2026-07-15T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/07/by2</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/07/by2/"><![CDATA[<p>In the previous post <a href="/posts/2026/06/by1/">How to learn representations under p4 and p4m symmetry groups</a> we saw how a G-CNN extends ordinary convolution. It shares one filter across a group of transformations such as the four 90-degree rotations in \(p4\). For a \(p4\) G-CNN, a feature at each pixel has four orientation channels. When the image rotates by 90 degrees, those channels cycle to new positions. Therefore if the input rotates or flips, the internal features change in a known, predictable and useful way.</p>

<h2 id="a-quick-recap-on-symmetry-equivariance-and-invariance">A quick recap on symmetry, equivariance and invariance</h2>

<p>When people first hear about symmetry, they often think about <em>invariance</em>: if the input rotates, the output stays the same. That is useful at the very end of a predictive model, where we only care about the class label. But inside a deep network, we usually don’t want to throw away pose information too early. Later layers still need to know whether an edge is vertical, horizontal, or diagonal. A filter \(\psi\) is equivariant if transforming the input and then applying the network gives the same result as applying the network first and then transforming the features:</p>

\[\psi(\rho(g)f) = \pi(g)\psi(f)\]

<p>It says the feature changes predictably when the input changes. Once we know the transformation \(g\), we know exactly how the feature response should change. We do not need to learn a separate filter from examples. Here, \(f\) is the input signal or feature map, \(g\) is a transformation such as a rotation or reflection, \(\psi \in \Psi\) is the learnable filter, \(\rho(g)\) is a representation on how the input transforms, and \(\pi(g)\) is a representation on how the feature transforms.</p>

<h2 id="g-cnns-stacks-of-transformations">G-CNNs: stacks of transformations</h2>

<p>The basic transformation law is:</p>

\[[\rho(g)\psi](x) = \psi(g^{-1}x)\]

<p>It says the value that ends up at position \(x\) after a transformation \(g\) comes from the old position \(g^{-1}x\).</p>

<p>For translations, standard convolution is already equivariant. If you shift the image, the feature map shifts in the same way. This is one of the big reasons CNNs work so well. But standard CNNs don’t naturally know what to do with rotations and reflections. Data augmentation helps, but the architecture itself still treats each pose as something it may need to learn again. G-CNNs fix this by using a group such as \(p4\) or \(p4m\). They explicitly track position and orientation, so a rotated input produces a rotated feature map with its orientation channels permuted in a predictable way.</p>

<p>Instead of learning only one filter, G-CNN applies all transformed versions of the filter:</p>

\[\psi_g(x)=\psi(g^{-1}x)\]

<p>The resulting filter tensor contain an additional group dimension:</p>

\[\mathbf{\Psi} \in \mathbb{R}^{C_{in} \times C_{out} \times \|G\| \times H \times W}\]

<p>where \(H\) and \(W\) are the spatial size of the kernel, \(C_{in}\) and \(C_{out}\) are the number of input and output channels and \(\|G\|\) is the number of transformations in the group \(G\). For example, a rotation-equivariant CNN with 8 discrete orientations stores \(C \times 8\) feature maps corresponding to the different orientations. Although it’s expressive, it makes every feature pay the cost of carrying a full orientation stack.</p>

<h2 id="what-does-g-cnn-learn">What does G-CNN learn?</h2>

<p>In G-CNN, the network learns only a single base filter \(\psi\). The remaining filters are generated automatically by applying the group 
transformations:</p>

\[\psi_g(x)=\psi(g^{-1}x)\]

<p>\(\psi\), as a convolution filter, is a function defined over spatial positions \(\psi:\mathbb{R}^{2}\rightarrow\mathbb{R}\) and \(x\) represents a spatial coordinate inside the filter kernel. \(g^{-1}\) maps the transformed coordinate back to the original coordinate.</p>

<p>For example, for a discrete rotation group \(p4\) \(G=\{0^\circ,90^\circ,180^\circ,270^\circ\}\) the filter bank becomes \(\{\psi_0,\psi_{90},\psi_{180},\psi_{270}\}\). A \(3\times3\) learned filter can be represented as:</p>

\[\psi =
\begin{bmatrix}
a&amp;b&amp;c\\
d&amp;e&amp;f\\
g&amp;h&amp;i
\end{bmatrix}\]

<p>where \(a,\ldots,i\) are learned parameters. The group transformation learns only one filter and then deterministically generates transformed versions of the original filter by changing the spatial coordinates. A \(90^\circ\) rotation produces:</p>

\[\psi_{90} =
\begin{bmatrix}
c&amp;f&amp;i\\
b&amp;e&amp;h\\
a&amp;d&amp;g
\end{bmatrix}\]

<p>The rotated filter is therefore not an additional learned parameter. It is obtained directly from the original filter through the group operation. Therefore, a G-CNN learns only the base filter \(\psi\). The symmetry group automatically generates the set of transformed filters without requiring additional trainable parameters.</p>

\[\{\psi_g \mid g\in G\}\]

<h2 id="from-input-space-to-group-feature-space-in-g-cnns">From input space to group feature space in G-CNNs</h2>

<p>In a standard CNN, the input image is transformed into a feature map:</p>

\[X(x) \rightarrow F(x)\]

<p>where \(x\) represents the spatial position, \(X(x)\) is the input value, and \(F(x)\) is a feature vector at that position.</p>

<p>The output feature map tenosr has the form:</p>

\[F \in \mathbb{R}^{C \times H \times W}\]

<p>where \(C\) is the number of channels and \(H\) and \(W\) are the spatial dimensions.</p>

<p>In a G-CNN, the first layer is different. Instead of producing only spatial features, the network produces features that are indexed by both spatial position and transformation state:</p>

\[X(x) \rightarrow F(x,g)\]

<p>The resulting feature map tensor becomes:</p>

\[F \in \mathbb{R}^{C \times \|G\| \times H \times W}\]

<p>For example, for the discrete rotation group \(p4\)</p>

<p>each spatial location contains a set of orientation-dependent features:</p>

\[F(x)=
\begin{bmatrix}
F(x,0^\circ)\\
F(x,90^\circ)\\
F(x,180^\circ)\\
F(x,270^\circ)
\end{bmatrix}\]

<p>Thus, a feature is not only associated with a spatial location, but also with a transformation state.</p>

<h2 id="the-first-layer-of-g-cnn-lifting-convolution">The first layer of G-CNN: Lifting convolution</h2>

<p>The first layer of a G-CNN is called a <em>lifting convolution</em>. It maps the input image space to a feature space that includes the group dimension. Instead of the standard convolution:</p>

\[F(x)=\sum_u \psi(u)X(x+u)\]

<p>the lifting convolution computes:</p>

\[F(x,g)=\sum_u \psi_g(u)X(x+u)\]

<p>where the filters are generated from the base filter through the group action:</p>

\[\psi_g(u)=\psi(g^{-1}u)\]

<p>The output therefore belongs to a space that combines spatial and 
transformation dimensions:</p>

\[\mathbb{R}^{2}\rightarrow \mathbb{R}^{2}\times G\]

<p>The network has learned a base filter \(\psi\), while the transformed filters \(\psi_g\) are generated deterministically by the symmetry operations.</p>

<h2 id="subsequent-layers-of-g-cnn">Subsequent layers of G-CNN</h2>

<p>After the first layer, the input is no longer a standard feature map. It is a feature field defined over both spatial positions and transformation states: \(F(x,g)\)</p>

<p>Subsequent layers perform group convolutions that combine information from neighboring spatial positions and different transformation states. The group convolution is defined as:</p>

\[(F * \Psi)(x,g)
=
\sum_{h\in G}
\sum_u
F(x+u,h)
\Psi(g^{-1}h,u)\]

<p>The term \(g^{-1}h\) ensures that the relationship between different orientations is treated consistently under the group transformation.</p>

<h2 id="towards-steerable-cnns">Towards Steerable CNNs</h2>

<p>Although G-CNN is a real improvement over conventional CNNs, it raises an important question: must every feature be stored as a full stack of orientations?</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Beyond CNN" /><category term="Equivariance" /><category term="Invariance" /><category term="Convolutional filters" /><category term="Group-convolutions" /><category term="G-CNN" /><summary type="html"><![CDATA[How group convolutional networks (G-CNNs) build equivariant feature representations that respect rotational and reflective symmetry.]]></summary></entry><entry><title type="html">Steerable CNNs &amp;amp; irreducible representations</title><link href="https://yassermb.github.io/posts/2026/07/by3/" rel="alternate" type="text/html" title="Steerable CNNs &amp;amp; irreducible representations" /><published>2026-07-15T00:00:00+00:00</published><updated>2026-07-15T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/07/by3</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/07/by3/"><![CDATA[<p><a href="/posts/2026/07/by2/">How group convolutional networks exploit symmetry</a> ended with a question: must every feature map be stored as a full stack of orientations? A \(p_4\) G-CNN keeps four rotated copies of every feature, and a \(p_4m\) G-CNN keeps eight. That is wasteful when a feature doesn’t need to remember every orientation separately. Those features look the same no matter how the input is rotated, for example:</p>

\[f=
\begin{pmatrix}
x&amp;0&amp;x\\
0&amp;0&amp;0\\
x&amp;0&amp;x
\end{pmatrix} \qquad or \qquad
f=
\begin{pmatrix}
0&amp;0&amp;0\\
0&amp;x&amp;0\\
0&amp;0&amp;0
\end{pmatrix}\]

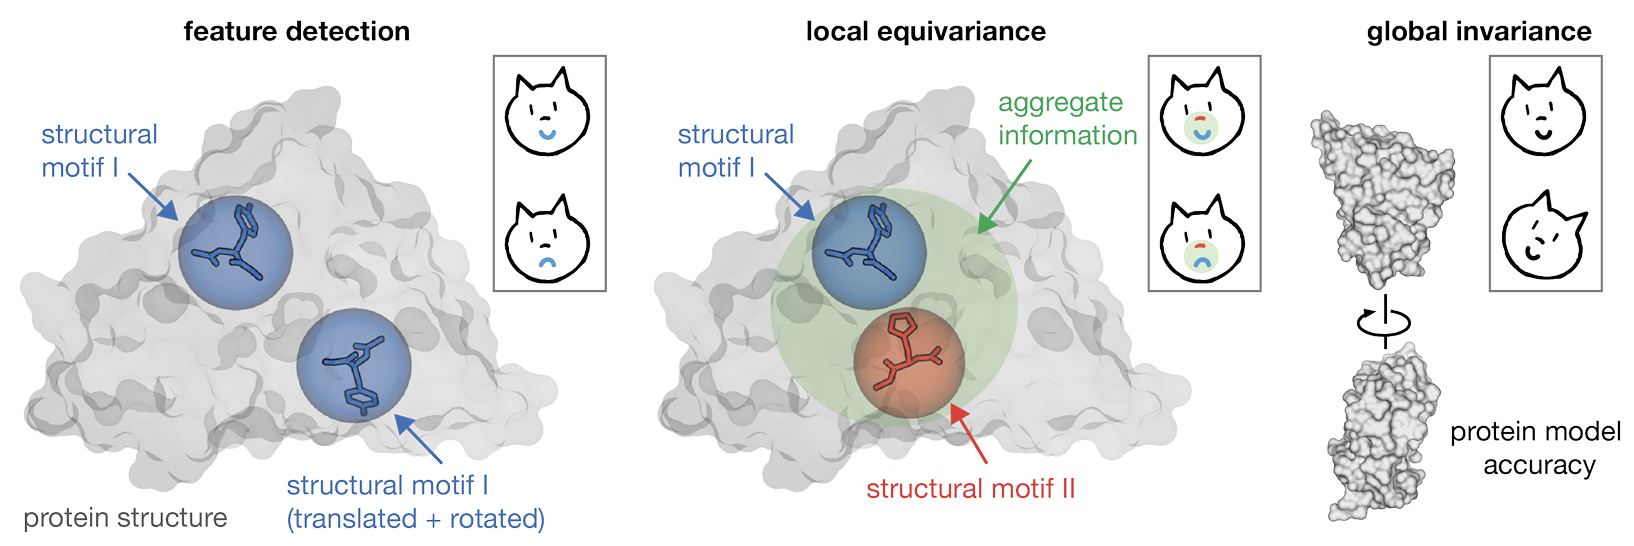
<p><a href="https://arxiv.org/abs/1612.08498">Cohen &amp; Welling (2017)</a> addressed this problem using <em>Steerable CNN</em>. It keeps the promise of G-CNNs: if the input rotates or flips, the internal features change in a known, predictable way. But instead of forcing every feature to carry a full orientation stack, they let each feature transform in whatever way is natural for it. Some stay unchanged, some flip sign, some rotate together as a 2D pair, and some still need the full stack. The word <em>steerable</em> itself is older, coming from signal processing work on steerable filters.</p>

<h2 id="each-spatial-position-contains-a-geometrically-structured-object-fiber">Each spatial position contains a geometrically structured object (fiber)</h2>

<p>At each spatial position \(x\), a feature map stores a structured object called the fiber. In a standard CNN, the channels inside one fiber are just a plain list of numbers. In a steerable CNN, that list is a structured object with a rule for how it transforms when the input rotates or flips. At its general concept, a fiber can hold, for example:</p>

<ul>
  <li>a <strong>scalar</strong> that stays the same under every rotation and reflection,</li>
  <li>a <strong>signed value</strong> that flips sign under specific rotations or reflections,</li>
  <li>a <strong>2D vector</strong> whose two components rotate together,</li>
  <li>an even <strong>orientation stack</strong>, whose channels permute among several poses (this is exactly what a G-CNN fiber looks like).</li>
</ul>

<p>So a fiber does not only say <em>“what is here!”</em> It also says <em>“how this should behave when the input transforms!”</em></p>

<h2 id="the-rule-a-steerable-filter-must-satisfy">The rule a steerable filter must satisfy</h2>

<p>Let’s assume a convolution filter \(\psi \in \Psi\) maps an input feature map \(f \in F\), transforming under \(g \in G\) according to a representation \(\rho(g)\), to an output feature map transforming under g according to a representation \(\pi(g)\). For the output to be steerable, a convolution filter \(\psi\) must satisfy:</p>

\[\psi(\rho(g)f) = \pi(g)\psi(f)\]

<p>Note that \(\pi(g)\) allows us to <em>steer</em> the output fiber.</p>

<p>According to group theory \(\rho(gh) = \rho(g)\rho(h) \quad \forall g,h \in G\):</p>

\[\pi(gh)\psi(f) = \psi(\rho(gh)f) = \psi(\rho(g)\rho(h)f) = \pi(g)\psi(\rho(h)f) = \pi(g)\pi(h)\psi(f) \quad \forall g,h \in G\]

<p>\(\Psi\) is a filter space and \(F\) is a linear feature space. Here \(G\) is the subgroup fixing the origin (<em>i.e.</em> rotations and reflections only). Translations are handled separately, by sliding the same filter bank across every position, as in an ordinary convolution.</p>

<p>As usual this says rotating and/or flipping the input feature map and then filtering must give the same result as filtering first and then rotating and/or flipping the output.</p>

<h2 id="interwiners">Interwiners</h2>

<p>The filter must be compatible with the way \(g\) transforms the input and output feature maps. This results into the <em>intertwiner</em> equation: \(\psi(\rho(g)f) = \pi(g)\psi(f)\). Here \(\psi\) intertwines the two group actions \(\rho\) and \(\pi\). In other words, the filter must be determined in a way to have specific symmetries so transforming the input results into transforming the output in a controlled fashion. Here is an example on how interwiner equation imposes constraints on the filter:</p>

<p>Let the \(3\times3\) feature map window be</p>

\[f=
\begin{pmatrix}
a&amp;b&amp;c\\
d&amp;e&amp;f\\
g&amp;h&amp;i
\end{pmatrix}\]

<p>For a \(g=90^\circ\) clockwise rotation,</p>

\[\rho(g)f=
\begin{pmatrix}
g&amp;d&amp;a\\
h&amp;e&amp;b\\
i&amp;f&amp;c
\end{pmatrix}\]

<p>Now consider a parameterized filter</p>

\[\psi=
\begin{pmatrix}
w_1&amp;w_2&amp;w_3\\
w_4&amp;w_5&amp;w_6\\
w_7&amp;w_8&amp;w_9
\end{pmatrix}\]

<p>Its response to \(f\) is obtained by element-wise multiplication followed by summation:</p>

\[\psi(f)
=
w_1a+w_2b+w_3c+
w_4d+w_5e+w_6f+
w_7g+w_8h+w_9i\]

<p>For simplicity, we assume output is a scalar, then \(\pi(g)\) acts trivially: \(\pi(g)y=y\) and the intertwiner equation therefore becomes: \(\psi(\rho(g)f)=\psi(f)\).</p>

<p>For an arbitrary filter, the \(w_i\)’s are independent, and there is no reason for the intertwiner equation to hold. Requiring the interwiner equality for every possible \(f\) imposes constraints on the filter parameters: \(w_1=w_3=w_7=w_9\) and \(w_2=w_4=w_6=w_8\), while \(w_5\) remains free.</p>

<p>Thus, the filter must have the form</p>

\[\psi=
\begin{pmatrix}
\alpha&amp;\beta&amp;\alpha\\
\beta&amp;\gamma&amp;\beta\\
\alpha&amp;\beta&amp;\alpha
\end{pmatrix}\]

<p>so that \(\rho(g)\psi=\psi\), and consequently \(\psi(\rho(g)f)=\psi(f)\).</p>

<p>More generally, when the output transforms non-trivially according to \(\pi(g)\), the constraint becomes \(\psi(\rho(g)f)=\pi(g)\psi(f)\). In this case, the parameters of \(\psi\) are constrained by both \(\rho(g)\) and \(\pi(g)\).</p>

<p>The filter bank \(\Psi\) that satisfies the interwiner equation form a vector space, written \(\mathrm{Hom}_G(\rho,\pi)\) and called the space of <em>intertwiners</em>. Training only searches inside this space, instead of the space of all possible filters.</p>

<p>A G-CNN turns out to be a special case of this rule. If both \(\rho\) and \(\pi\) are the <em>regular representation</em>, where we have one channel for every element of the group and those channels are simply permuted among the group elements (the orientation stack from the previous post), the constraint above reduces exactly to the group convolution used in G-CNNs. Steerable CNNs generalize this framework by allowing feature fields to transform according to more general representations, rather than restricting them to the regular representation.</p>

<h2 id="how-do-filters-have-symmetry">How do filters have symmetry?</h2>

<p>The filter \(\psi\) is \(3\times3\) matrix, containing 9 parameters.</p>

\[\psi=
\begin{pmatrix}
w_1&amp;w_2&amp;w_3\\
w_4&amp;w_5&amp;w_6\\
w_7&amp;w_8&amp;w_9
\end{pmatrix}\]

<p>When we rotate the filter clock-wise by \(90^\circ\) (\(r\)), we obtain</p>

\[r\psi=
\begin{pmatrix}
w_7&amp;w_4&amp;w_1\\
w_8&amp;w_5&amp;w_2\\
w_9&amp;w_6&amp;w_3
\end{pmatrix}\]

<p>In the interwiner equation, rotating the input is equivalent to rotating the filter in the opposite direction. So the left side of the equation can be written: \(\psi(\rho(g)f) = (\rho(g^{-1})\psi)(f)\).</p>

<p>Now let’s define some very basic filters and see how they react to transformations of \(D_4\) group:</p>

<ul>
  <li>\(e\) : \(0^\circ\) rotation (identity)</li>
  <li>\(r\) : \(90^\circ\) rotation</li>
  <li>\(r^2\) : \(180^\circ\) rotation</li>
  <li>\(r^3\) : \(270^\circ\) rotation</li>
  <li>\(m\) : horizontal reflection</li>
  <li>\(mr\) : diagonal reflection across \(y=x\)</li>
  <li>\(mr^2\) : vertical reflection</li>
  <li>\(mr^3\) : diagonal reflection across \(y=-x\)</li>
</ul>

<h3 id="example-1-the-center-pixel">Example 1: the center pixel</h3>

<p>Consider a filter containing only the center pixel:</p>

\[\psi_{\mathrm{center}}=
\begin{pmatrix}
0&amp;0&amp;0\\
0&amp;x&amp;0\\
0&amp;0&amp;0
\end{pmatrix}\]

<p>After a \(90^\circ\) rotation,</p>

\[\rho(r)\psi_{\mathrm{center}}
=
\begin{pmatrix}
0&amp;0&amp;0\\
0&amp;x&amp;0\\
0&amp;0&amp;0
\end{pmatrix}\]

<p>Nothing changes. \(\rho(r)\psi=\psi\) and therefore \(x\rightarrow x\). We call this a 1-dimensional \(A_1\) representation: \(\pi_{A_1}(r)=[1]\) that will be applied to the right side of the interwiner equation. For this specific filter all elements of group \(D_4\) can be represented by \([1]\) because the filter remains unchanged under all elements of this group, therefore:</p>

<p>\(\pi_{A_1}(g)=[1], \qquad \forall g \in D_4\).</p>

<hr />

<h3 id="example-2-symmetric-corners">Example 2: symmetric corners</h3>

<p>Consider the following filter:</p>

\[\psi=
\begin{pmatrix}
x&amp;0&amp;x\\
0&amp;0&amp;0\\
x&amp;0&amp;x
\end{pmatrix}\]

<p>A \(90^\circ\) rotation leaves the filter unchanged: \(\rho(r)\psi=\psi\). This is another \(A_1\) representation type. As before, for this specific filter all elements of group \(D_4\) can be represented by \([1]\) because the filter remains unchanged under all elements of this group:</p>

<p>\(\pi_{A_1}(g)=[1], \qquad \forall g \in D_4\).</p>

<hr />

<h3 id="example-3-symmetric-edges">Example 3: symmetric edges</h3>

<p>Consider the following filter:</p>

\[\psi=
\begin{pmatrix}
0&amp;x&amp;0\\
x&amp;0&amp;x\\
0&amp;x&amp;0
\end{pmatrix}\]

<p>Again, a \(90^\circ\) rotation leaves the filter unchanged: \(\rho(r)\psi=\psi\). This gives a third \(A_1\) representation type.</p>

<p>The \(3\times3\) filter space contains 3 \(A_1\). These three representation types (or components) can be understood intuitively as: <em>centers</em>, <em>cornders</em>, <em>edges</em>.</p>

<hr />

<h3 id="example-4-transformation-dependent-representation">Example 4: Transformation-dependent representation</h3>

<p>Consider the following filter</p>

\[\psi=
\begin{pmatrix}
x&amp;0&amp;-x\\
0&amp;0&amp;0\\
-x&amp;0&amp;x
\end{pmatrix}\]

<p>After a \(90^\circ\) rotation,</p>

\[\rho(r)\psi=
\begin{pmatrix}
-x&amp;0&amp;x\\
0&amp;0&amp;0\\
x&amp;0&amp;-x
\end{pmatrix}\]

<p>Thus, \(\rho(r)\psi=-\psi\) and \(x\rightarrow -x\). Consequently the convolutional output also changes sign therefore on the right side of the equation we have \(\pi(r)=[-1]\).</p>

<p>Meanwhile after a \(180^\circ\) rotation (\(r^2\)) the filter remains unchanged: \(\rho(r^2)\psi=\psi\) and therefore \(\pi(r^2)=[1]\).</p>

<p>This is another type of 1-dimensional representation, which we call \(B_1\). Depending on the transformation, it results in either the same filter or its negative, so at the right side of the equation we have \(\pi_{B_1}(r)=[-1]\) and \(\pi_{B_1}(r^2)=[1]\).</p>

<hr />

<h3 id="example-5-detection-of-edge-and-its-orientation">Example 5: Detection of edge and its orientation</h3>

<p>Consider two oriented filters for detecting local gradients in the horizontal and vertical directions.</p>

\[\psi_x=
\begin{pmatrix}
0&amp;0&amp;0\\
-1&amp;0&amp;1\\
0&amp;0&amp;0
\end{pmatrix}\]

<p>This filter detects a change from left to right.</p>

<p>Similarly,</p>

\[\psi_y=
\begin{pmatrix}
0&amp;-1&amp;0\\
0&amp;0&amp;0\\
0&amp;1&amp;0
\end{pmatrix}\]

<p>This filter detects a change from top to bottom.</p>

<p>Applying these filters to an input feature map produces two feature maps,</p>

\[f'_x=\psi_x * f,
\qquad
f'_y=\psi_y * f\]

<p>Together, they form a 2-dimensional feature,</p>

\[\mathbf{f'}
=
\begin{pmatrix}
f'_x\\
f'_y
\end{pmatrix}\]

<p>which can be interpreted as a local gradient vector. Its direction describes the orientation of the local gradient, while the corresponding edge is oriented perpendicular to this gradient.</p>

<p>Under a \(90^\circ\) rotation, the horizontal and vertical directions are exchanged as follows:</p>

\[\psi_x\rightarrow \psi_y,
\qquad
\psi_y\rightarrow -\psi_x\]

<p>Consequently,</p>

\[\begin{pmatrix}
f'_x\\
f'_y
\end{pmatrix}
\rightarrow
\begin{pmatrix}
-f'_y\\
f'_x
\end{pmatrix}\]

<p>This is a 2-dimensional representation type we call \(E\). For these specific filters we need a \(2 \times 2\) matrix to represent this type of transformation at the right side of the interwiner equation:</p>

\[\pi_{E}(r)=
\begin{pmatrix}
0&amp;-1\\
1&amp;0\\
\end{pmatrix}\]

<p>Apply this representation on the feature map and see the result: \({\mathbf{f}_r}'=\pi_E(r)\mathbf{f'}\).</p>

<h2 id="irreducible-representations">Irreducible representations</h2>

<p>The representations associated with the examples above are <em>irreducible representations (irreps)</em> that cannot be decomposed further. We can construct the input representation \(\rho\) and output representation \(\pi\) as direct sums of irreducible representations. For example, if \(A_1\), \(B_1\), and \(E\) are irreducible types, then:</p>

\[\rho = \rho_{A_1} \oplus \rho_{B_1} \oplus \rho_{E}\]

<p>acting on the input feature space (\(f\)), and the representation</p>

\[\pi = \pi_{A_1} \oplus \pi_{B_1} \oplus \pi_{E}\]

<p>acting on the output feature space (\(\psi(f)\)).</p>

<p>In matrix form, the symbol \(\oplus\) denotes formation of block-diagonal matrix:</p>

\[\rho(g)
=
\rho_{A_1}(g)\oplus \rho_{B_1}(g)\oplus \rho_{E}(g)
=
\begin{pmatrix}
\rho_{A_1}(g) &amp; 0 &amp; 0\\
0 &amp; \rho_{B_1}(g) &amp; 0\\
0 &amp; 0 &amp; \rho_{E}(g)
\end{pmatrix}\]

<p>For example, consider the output representation \(\pi\) and suppose that the irreducible types \(A_1\) and \(B_1\) are 1-dimensional, while \(E\) is 2-dimensional:</p>

\[\pi_{A_1}(g),\pi_{B_1}(g)\in\mathbb{R}^{1\times1},
\qquad
\pi_E(g)\in\mathbb{R}^{2\times2}\]

\[\pi(g) =
\pi_{A_1}(g)\oplus\pi_{B_1}(g)\oplus\pi_E(g) = 
\begin{pmatrix}
\pi_{A_1}(g) &amp; 0 &amp; 0 \\
0 &amp; \pi_{B_1}(g) &amp; 0 \\
0 &amp; 0 &amp; \pi_E(g)
\end{pmatrix}
\in\mathbb{R}^{4\times4}.\]

<p>Then the output feature vector \(\mathbf{f'} = \psi(f)\) (the fiber) can be written as</p>

\[\mathbf{f'} = 
\begin{pmatrix}
f'_{A_1}\\
f'_{B_1}\\
f'_{E(1)}\\
f'_{E(2)}
\end{pmatrix}\]

<p>and under a transformation \(g\), it transforms according to \({\mathbf{f}_g}'=\pi(g)\mathbf{f'}\). Each block of the feature vector therefore transforms according to its own irreducible representation.</p>

<p>We can also have several copies of the same irreducible representation. For example,</p>

\[\pi = 3\pi_{A_1}\oplus 2\pi_{B_1}\oplus 4\pi_E\]

<p>means that the feature space contains: 3 copies of \(A_1\), 2 copies of \(B_1\), and 4 copies of \(E\). If \(A_1\) and \(B_1\) are one-dimensional while \(E\) is two-dimensional, then the total dimension of the representation is \(\dim(\pi)=3(1)+2(1)+4(2)=13\). More explicitly, the representation matrix has the block-diagonal form</p>

\[\pi(g)
=
\begin{pmatrix}
\pi_{A_1}(g) &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0\\
0 &amp; \pi_{A_1}(g) &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0\\
0 &amp; 0 &amp; \pi_{A_1}(g) &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0\\
0 &amp; 0 &amp; 0 &amp; \pi_{B_1}(g) &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0\\
0 &amp; 0 &amp; 0 &amp; 0 &amp; \pi_{B_1}(g) &amp; 0 &amp; 0 &amp; 0 &amp; 0\\
0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; \pi_{E}(g) &amp; 0 &amp; 0 &amp; 0\\
0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; \pi_{E}(g) &amp; 0 &amp; 0\\
0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; \pi_{E}(g) &amp; 0\\
0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; 0 &amp; \pi_{E}(g)
\end{pmatrix}
\in\mathbb{R}^{13 \times 13}\]

<p>In other words, the notation \(\rho = \bigoplus_i n_i\rho_i\) and \(\pi = \bigoplus_j m_j\pi_j\) means that the feature space is constructed by taking several copies of different irreducible representations and placing their representation matrices along the diagonal. This decomposition of the group representations into irreducible representations allows a steerable CNN to contain different feature types that transform differently under rotations and reflections, while still having a well-defined overall transformation rule.</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Beyond CNN" /><category term="Equivariance" /><category term="Invariance" /><category term="Steerable" /><category term="Convolutional filters" /><category term="Group-convolutions" /><summary type="html"><![CDATA[An introduction to steerable CNNs and irreducible representations, generalizing group convolutions to more efficient, symmetry-aware feature fields.]]></summary></entry><entry><title type="html">How to learn representations under p4 and p4m symmetry groups</title><link href="https://yassermb.github.io/posts/2026/04/by1/" rel="alternate" type="text/html" title="How to learn representations under p4 and p4m symmetry groups" /><published>2026-04-15T00:00:00+00:00</published><updated>2026-04-15T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/04/by1</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/04/by1/"><![CDATA[<p>Building on the theoretical foundation presented in <em>Beyond CNN: Chapter 0</em>, Cohen and Welling brought the group-theoretic concepts directly into neural network architectures with their 2016 paper, <a href="https://proceedings.mlr.press/v48/cohenc16.html">“Group Equivariant Convolutional Networks”</a>. While traditional CNNs natively handle translations, they fail to equivary with isometries like rotations and reflections. To solve this, they introduced group-equivariant convolutions (G-CNN), a natural generalization of convolutions that extends weight sharing beyond translations to include rotations, reflections, and other symmetries. G-CNN is a new type of layer that shares weights across a larger group of symmetries (specifically the <em>p4</em> and <em>p4m</em> groups, representing 90-degree rotations and reflections). These layers effectively increased the expressive capacity of the network without adding any parameters.</p>

<h1 id="object-and-feature-map">Object and feature map</h1>

<p>Domain \(\Omega\) (e.g. 2D \(\mathbb{Z}^2\) or 3D \(\mathbb{Z}^3\) Euclidean spaces) is an underlying space where we can define an object. An object can be an input image or a feature map generated within the intermediate layers of representation learning. We apply function space \(\mathbb{F}\) on domain \(\Omega\) to define object \(f\) (e.g. a 2D image or a protein 3D structure).</p>

\[\mathbb{F}(\Omega, \mathbb{C})=\{f:\Omega \rightarrow \mathbb{C}\}\]

<p>where \(\mathbb{C} \in \mathbb{R}^K\) is the range of values taken by objects defined on \(\Omega\).</p>

<h1 id="equivariance-and-symmetry-group">Equivariance and symmetry group</h1>

<p>A function \(\Phi\) is equivariant to a transformation \(g\) if transforming the input and then applying \(\Phi\) gives the same result as applying \(\Phi\) first and then transforming the output:</p>

\[\Phi(T_g x) = T'_g \Phi(x)\]

<p>Here \(T_g\) and \(T'_g\) are (possibly different) operators that represent the transformation \(g\) acting on the input and output spaces respectively.</p>

<p>You’ve already seen this with regular convolutions: shifting an image and then convolving gives the same result as convolving and then shifting. That’s just translation equivariance. The goal of G-CNNs is to make networks equivariant to a broader group of transformations \(G\).</p>

<p>Why equivariance and not invariance? Invariance means \(T'_g = I\) (the output doesn’t change at all). While that sounds useful, it’s actually too strong for intermediate layers. If your intermediate features are invariant to rotation, you’ve thrown away spatial information about <em>where</em> things are oriented, which makes it impossible to detect relative poses between features. Equivariance preserves structure; invariance destroys it.</p>

<p>A symmetry group is a set of transformations under which the properties of the object remain unchanged. A Group satisfies following properties:</p>
<ul>
  <li>Has closure and can be composed (applying two transformations gives another transformation from the set)</li>
  <li>Has an identity (the “do nothing” transformation)</li>
  <li>Has inverses (every transformation can be undone)</li>
</ul>

<p>The simplest example is the set of 2D integer translations, \(\mathbb{Z}^2\). A translation by \((n, m)\) composed with a translation by \((p, q)\) gives \((n+p, m+q)\). The inverse of \((n, m)\) is \((-n, -m)\). This is the group that regular CNNs exploit.</p>

<p>For more information see my previous post on this topic:<br /> 
<a href="/posts/2024/07/equ/">Equivariance and Invariance: The building blocks of geometric deep learning</a></p>

<p>Here we focus on two richer groups:</p>

<ul>
  <li>
    <p>The group <strong>p4</strong>
p4 consists of all combinations of translations and 90-degree rotations in a grid. Every element can be written as a \(3 \times 3\) matrix:</p>

\[g(r, u, v) = \begin{bmatrix} \cos(r\pi/2) &amp; -\sin(r\pi/2) &amp; u \\ \sin(r\pi/2) &amp; \cos(r\pi/2) &amp; v \\ 0 &amp; 0 &amp; 1 \end{bmatrix}\]

    <p>where \(0 \leq r &lt; 4\) (four rotations: 0°, 90°, 180°, 270°) and \((u, v) \in \mathbb{Z}^2\) are the translation components. Group composition is just matrix multiplication.</p>
  </li>
  <li>
    <p>The group <strong>p4m</strong>
p4m extends p4 with mirror reflections. Its elements are parameterized as:</p>

\[g(m, r, u, v) = \begin{bmatrix} (-1)^m \cos\!\left(\tfrac{r\pi}{2}\right) &amp; -(-1)^m \sin\!\left(\tfrac{r\pi}{2}\right) &amp; u \\ \sin\!\left(\tfrac{r\pi}{2}\right) &amp; \cos\!\left(\tfrac{r\pi}{2}\right) &amp; v \\ 0 &amp; 0 &amp; 1 \end{bmatrix}\]

    <p>where \(m \in \{0, 1\}\) controls the flip. This gives 8 distinct orientations (4 rotations × 2 flip states), making p4m a richer symmetry group.</p>
  </li>
</ul>

<h1 id="functions-on-domains-vs-functions-on-groups">Functions on domains vs functions on groups</h1>

<p>In a regular CNN, a feature map (which is an object) is a function \(f : \mathbb{Z}^2 \to \mathbb{R}^K\) . It operates on a 2D grid of pixels (domain \(\mathbb{Z}^2\)) and at each pixel \((p, q)\) it assigns a \(K\)-dimensional vector of channels. A simple example is a grayscale image itself, which can be interpreted as a signal defined over the discrete grid (domain) \(\mathbb{Z}^2\), where each pixel contains a single intensity value (i.e., one channel). In CNN, each channel is generated by a filter. One channel might detect edges, another might detect textures, and another might detect corners. The only thing indexing the feature is the spatial position, so at each pixel we store features: \((p, q) \rightarrow\) feature vector.</p>

<p>In a G-CNN, feature maps become functions on the group \(G\) itself: \(f : G \to \mathbb{R}^K\). Instead of indexing by position alone, each feature is indexed by a full group element: a (position},rotation) pair for p4, or a (position, rotation, flip) triple for p4m. Therefore, for each transformation (like a rotation) AND position, we store features: (position, rotation) \(\rightarrow\) feature vector. Instead of just saying “there is an edge at (10, 5),” a G-CNN represents it as “there is an edge at (10, 5) with specific orientations (e.g., 30°, 90°, etc.),” explicitly encoding both position and transformation.</p>

<h1 id="group-actions">Group actions</h1>

<p>When a transformation \(g \in G\) acts on a feature map \(f\), it does so by “pulling back” the coordinates of domain \(\mathbb{Z}^2\). Instead of moving each feature <em>forward</em> to a new location, we ask: “to know what the transformed feature map looks like at position \(x \in \mathbb{Z}^2\), which position in the <em>original</em> map should I look up?” That answer is \(g^{-1}x\):</p>

\[[L_g f](x) = f(g^{-1} x)\]

<p>\(L_g\) is called the left action or left regular representation. It’s the operator that applies a group transformation \(g\) to a feature map by reindexing its domain coordinates.</p>

<p>The reason \(g^{-1}\) appears rather than \(g\) is a consistency requirement: applying transformation \(g\) and then \(h\) must equal applying \(gh\) in one shot. Using \(g^{-1}\) guarantees this — it makes \(L_g\) a proper <strong>group homomorphism</strong> (a structure-preserving map):</p>

\[\begin{aligned}
&amp;[L_g f](x) = f(g^{-1} x) \\
&amp;[L_g L_h f](x) = L_g(L_h f)(x) = (L_h f)(g^{-1} x) = f\!\left(h^{-1}(g^{-1} x)\right) \\
&amp;(gh)^{-1} = h^{-1} g^{-1} \\
&amp;f\!\left(h^{-1} g^{-1} x\right) = f\!\left((gh)^{-1} x\right) = [L_{gh} f](x)\\
&amp;gh \mapsto L_{gh} = L_g L_h \\
\end{aligned}\]

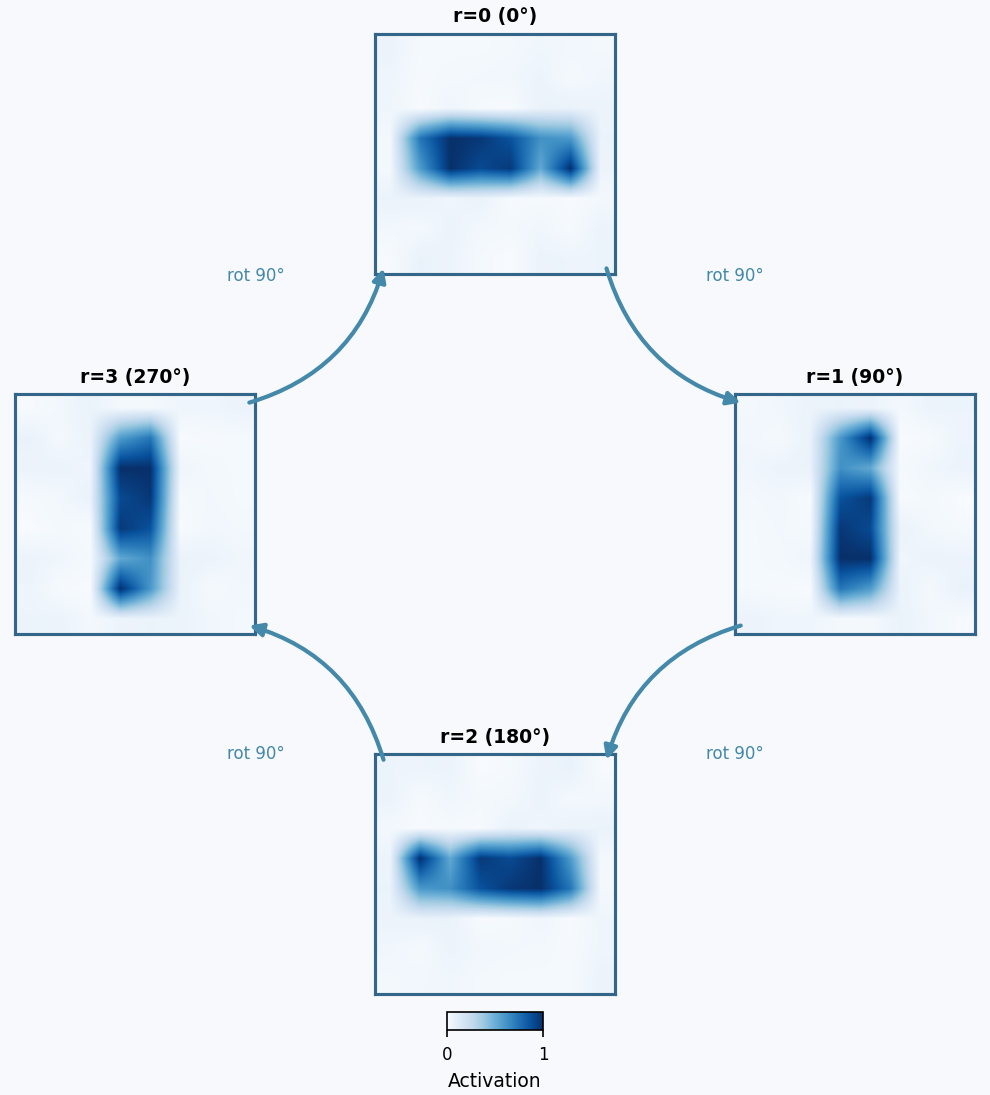
<p>To visualize a p4 feature map, imagine four copies of a 2D spatial grid arranged in a circle, one per rotation. When you rotate such a feature map, each copy shifts to the next position <em>and</em> its contents rotate by 90°. This interplay between the “rotation index” and the spatial content is exactly what the group structure captures.</p>

<p align="center">
  <img src="/images/posts/p4_group.png" width="600" /><br />
</p>

<p align="center">
  <img src="/images/posts/p4_feature_map.png" width="600" /><br />
</p>

<h1 id="standard-cnns-fail-at-rotation-equivariance">Standard CNNs fail at rotation equivariance</h1>

<p>In a regular CNN, the correlation of a feature map \(f\) with the convolutional filter \(\psi\) is:</p>

\[[f \star \psi](x) = \sum_{y \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y)\, \psi_k(y - x)\]

<p>where \(y\) ranges over all pixel positions, \(k\) ranges over the \(K\) input channels, \(f_k(y)\) is the feature map value at pixel \(y\) in channel \(k\), and \(\psi_k(y - x)\) is the weight of filter \(\psi\) at the relative offset \((y - x)\) in channel \(k\). The output at location \(x\) is a weighted sum of the neighborhood around \(x\). As you know this is the standard convolution.</p>

<p>For translations, this operation is equivariant: shift the input by \(t\) pixels, and the output shifts by exactly \(t\) pixels:</p>

\[\begin{aligned}
&amp;[L_t f](y) = f(y - t) \\
&amp;[[L_t f] \star \psi](x) = \sum_{y \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y - t)\, \psi_k(y - x) \\
&amp;y' = y - t \Rightarrow y = y' + t \\
&amp;[[L_t f] \star \psi](x) = \sum_{y' \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y')\, \psi_k((y' + t) - x) \\
&amp;[[L_t f] \star \psi](x) = \sum_{y' \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y')\, \psi_k(y' - (x - t)) \\
&amp;[[L_t f] \star \psi](x) = [f \star \psi](x - t) \\
&amp;[[L_t f] \star \psi](x) = [L_t (f \star \psi)](x) \\
\end{aligned}\]

<p>But for a rotation \(r\), things break down. Working through the same algebra with a rotation gives:</p>

\[\begin{aligned} 
&amp;[L_r f](y) = f(r^{-1} y) \\
&amp;[[L_r f] \star \psi](x) = \sum_{y \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(r^{-1} y)\, \psi_k(y - x) \\
&amp;y' = r^{-1} y \Rightarrow y = r y' \\
&amp;[[L_r f] \star \psi](x) = \sum_{y' \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y')\, \psi_k(r y' - x) \\
&amp;x = r(r^{-1} x) \\
&amp;r y' - x = r y' - r(r^{-1} x) = r(y' - r^{-1} x) \\
&amp;\psi_k(r(y' - r^{-1} x)) \\
&amp;[L_{r^{-1}} \psi](z) = \psi(r z) \\
&amp;\psi_k(r(y' - r^{-1} x)) = [L_{r^{-1}} \psi]_k(y' - r^{-1} x) \\
&amp;[[L_r f] \star \psi](x) = \sum_{y' \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y')\, [L_{r^{-1}} \psi]_k(y' - r^{-1} x) \\
&amp;[[L_r f] \star \psi](x) = [f \star (L_{r^{-1}} \psi)](r^{-1} x) \\
&amp;[[L_r f] \star \psi](x) = [L_r (f \star (L_{r^{-1}} \psi))](x) \\
\end{aligned}\]

<p>Notice the extra \(L_{r^{-1}} \psi\) on the right. This says: rotating the input and then convolving with \(\psi\) is equivalent to convolving with the <em>already-rotated filter</em> \(L_{r^{-1}}\psi\) and then rotating the output. The filter on the right-hand side has changed. It’s now the \(r\) degree-rotated version of the original $\psi$. So convolving with the <em>same</em> unmodified \(\psi\) on both sides gives different results. The operation is <strong>not</strong> equivariant to rotation.</p>

<p>This is why a standard CNN that wants to detect a feature in all four orientations (in case of p4 group) needs to learn four separate filters. G-CNNs solve this by sharing weights across all orientations.</p>

<hr />

<h1 id="g-convolutions">G-Convolutions</h1>

<p>The G-CNN replaces the standard convolution with a <em>G-correlation</em>, which explicitly correlates over all transformations in \(G\).</p>

<h2 id="first-layer">First layer</h2>

<p>In the first layer, both the input \(f\) and the filter \(\psi\) are ordinary functions on \(\mathbb{Z}^2\). The G-correlation produces a feature map that is a function on \(G\):</p>

\[[f \star \psi](g) = \sum_{y \in \mathbb{Z}^2} \sum_{k=1}^{K} f_k(y)\, \psi_k(g^{-1} y)\]

<p>The output is indexed by elements \(g \in G\). For each \(g\), the value \([f \star \psi](g)\) is obtained by applying the transformation \(g^{-1}\) to the filter and computing its inner product with the input. As a result, the feature map is a function defined on the group \(G\), rather than on \(\mathbb{Z}^2\).</p>

<h2 id="subsequent-layers">Subsequent layers</h2>

<p>After the first layer, each feature map is no longer just a grid over \(\mathbb{Z}^2\), but a function on the group \(G\).</p>

\[f : G \to \mathbb{R^K}\]

<p>Instead of assigning a value to each spatial location, it assigns a value to each transformation \(g \in G\) (for example, a combination of a translation and a rotation). In typical settings, \(G\) may be a product such as \(G = \mathbb{Z}^2 \rtimes C_n\). In this case, an element \(g\) can be written as \(g = (x, r)\), where \(x \in \mathbb{Z}^2\) encodes a translation and \(r \in C_n\) encodes a discrete rotation. A feature map \(f\) therefore assigns a vector \(f(g)\) to each transformation \(g\), rather than to each position alone.</p>

<p>Because of this change in representation, filters must be defined in the same space. A filter \(\psi\) is therefore also a function on \(G\), so that it can be compared meaningfully with the input feature map at every group element.</p>

\[\psi : G \to \mathbb{R^K}\]

<p>Intuitively, both the input and the filter now describe patterns indexed by transformations rather than just positions.</p>

<p>For example, if \(G = \mathbb{Z}^2\), a feature map is a standard image-like grid. If \(G = \mathbb{Z}^2 \times C_4\), where \(C_4\) represents four rotations, then a feature map assigns a value to each location \((x,y)\) and each orientation \(r \in \{0^\circ, 90^\circ, 180^\circ, 270^\circ\}\). In this case, the filter must also specify a response for each position and orientation, so that it can detect not only <em>where</em> a pattern appears, but also <em>in which orientation</em> it appears.</p>

<p>The generalized correlation operator is then defined by comparing the input with transformed versions of the filter over all elements \(g \in G\):</p>

\[[f \star \psi](g) = \sum_{h \in G} \sum_{k=1}^{K} f_k(h)\, \psi_k(g^{-1} h)\]

<p>This is similar to a standard convolution, except the “spatial domain” is now the group \(G\) itself.</p>

<h2 id="proving-equivariance">Proving equivariance</h2>

<p>The equivariance proof follows the same substitution trick as we saw before, now using \(h' = u^{-1}h\) (left multiplication by \(u\) is a bijection on G):</p>

\[\begin{aligned}
{}[[L_u f] \star \psi](g) &amp;= \sum_{h \in G} \sum_{k=1}^{K} f_k(u^{-1}h)\, \psi_k(g^{-1}h) \\
&amp;= \sum_{h' \in G} \sum_{k=1}^{K} f_k(h')\, \psi_k(g^{-1}uh') \\
&amp;= \sum_{h' \in G} \sum_{k=1}^{K} f_k(h')\, \psi_k((u^{-1}g)^{-1}h') \\
&amp;= [L_u[f \star \psi]](g)
\end{aligned}\]

<p>So the G-correlation commutes with \(L_u\) for any \(u \in G\). The network is fully equivariant.</p>

<h2 id="everything-else-is-equivariant-too">Everything else is equivariant too</h2>

<p>Equivariance isn’t just a property of the G-convolution layer. It propagates cleanly through all the other components of a modern network.</p>

<h3 id="pointwise-nonlinearities">Pointwise nonlinearities</h3>

<p>Let \(\nu : \mathbb{R} \to \mathbb{R}\) be a nonlinearity (e.g. ReLU). The operator $C_\nu$ applies $\nu$ pointwise:</p>

\[(C_\nu f)(g) = \nu(f(g))\]

<p>It changes values independently at each \(g \in G\) without mixing locations.</p>

<p>Group transformations act by shifting the input function: \((L_h f)(g) = f(h^{-1}g)\). A key property is that these two operations commute: \(C_\nu L_h f(g) = \nu(f(h^{-1}g)) = L_h C_\nu f(g)\). This means applying a group transformation and then a nonlinearity gives the same result as applying the nonlinearity first and then transforming. Therefore, pointwise nonlinearities preserve equivariance. Here is the proof:</p>

\[\begin{aligned}
(C_\nu L_h f)(g)
&amp;= C_\nu(L_h f)(g) \\
&amp;= \nu((L_h f)(g)) \\
&amp;= \nu(f(h^{-1}g)).
\end{aligned}\]

\[\begin{aligned}
(L_h C_\nu f)(g)
&amp;= (C_\nu f)(h^{-1}g) \\
&amp;= \nu(f(h^{-1}g)).
\end{aligned}\]

<p>Since both expressions are equal for all \(g \in G\), we conclude: \(C_\nu L_h f = L_h C_\nu f\). ReLU, sigmoid, tanh: they’re all equivariant for free.</p>

<h3 id="pooling">Pooling</h3>

<p>We define max-pooling over a neighborhood \(U \subset G\) as:</p>

\[(Pf)(g) = \max_{u \in U} f(u),\]

<p>We show that pooling commutes with the group action.</p>

\[\begin{aligned}
(P L_h f)(g)
&amp;= \max_{u \in U} (L_h f)(u) \\
&amp;= \max_{u \in U} f(h^{-1}u).
\end{aligned}\]

<p>Now substitute \(u = hu'\), which preserves the set structure:</p>

\[\begin{aligned}
(P L_h f)(g)
&amp;= \max_{u' \in h^{-1}U} f(u') \\
&amp;= (P f)(h^{-1}g) \\
&amp;= (L_h P f)(g).
\end{aligned}\]

<p>Therefore,
\(P L_h f = L_h P f\)</p>

<p>So pooling is equivariant.</p>

<p>If pooling is taken over the entire group (e.g. all four rotations of <em>p4</em>) at each spatial location then the output will be a rotation-<em>invariant</em> feature map which is useful at the final layer if you want a fully invariant prediction. However, doing this too early (at intermediate layers) hurts performance, because it discards pose information before the network has had a chance to use it.</p>

<h3 id="batch-normalization-and-residual-connections">Batch normalization and residual connections</h3>

<p>Batch normalization and residual connections are commonly used in CNNs. \textbf{Question:} Do you think they are also equivariant? Why?</p>

<h1 id="putting-it-all-together">Putting it all together</h1>
<p>G-CNN isn’t that different from a standard network in structure: you simply replace each convolution with a G-convolution, adjust the number of channels to keep parameters in check, and let the network carry orientation-aware feature maps through its layers, optionally pooling over them at the end for invariance. But this small change leads to a much bigger shift in perspective: instead of treating features as unstructured vectors, the network now respects the symmetries of the problem by design. As a result, it doesn’t have to relearn the same pattern in multiple orientations, making it more sample-efficient, more expressive with the same number of parameters, and more reliable in how it generalizes.</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Beyond CNN" /><category term="Equivariance" /><category term="Invariance" /><category term="Convolutional filters" /><category term="Group-convolutions" /><category term="G-CNN" /><summary type="html"><![CDATA[An explanation of Group Equivariant Convolutional Networks (G-CNNs) and how p4 and p4m symmetry groups extend convolution beyond translations to rotations and reflections.]]></summary></entry><entry><title type="html">Beyond CNN</title><link href="https://yassermb.github.io/posts/2026/03/bey/" rel="alternate" type="text/html" title="Beyond CNN" /><published>2026-03-14T00:00:00+00:00</published><updated>2026-03-14T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/03/bey</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/03/bey/"><![CDATA[<h1 id="a-cat-is-a-cat-but-only-if-it-doesnt-rotate-">A cat is a cat, but only if it doesn’t rotate 🙀</h1>

<p>Representation learning powers deep learning. Instead of relying on hand-crafted features, deep learning models learn useful ones directly from data. A good representation learning should be meaningful, invariant to irrelevant changes, and disentangled into fundamental factors.</p>

<p>Convolutional Neural Networks (CNN) are a great example of representation learning. Instead of learning each part of an image separately, CNN reuse the same learned filters across all spatial locations, sharing weights throughout the image. This works because a cat is still a cat wherever it appears. A cat in the top-left of an image is the same cat in the bottom-right. This is <em>translation equivariance</em> by design, and it’s one of the core reasons CNNs work so well. Shifting the input image by a few pixels shifts the convolution output by the same amount! The network doesn’t have to <em>re-learn</em> anything.</p>

<p>However, conventional CNNs struggle with other geometric transformations, like rotations and reflections, often relying on brute-force data augmentation to learn them. When you rotate a handwritten “6” by 180°, it looks like a “9” to both humans and machines. A classical CNN has no built-in mechanism to link these two images. It must learn <em>each orientation independently</em>, which means:</p>

<ul>
  <li>Wasting model capacity on redundant rotated copies of every filter</li>
  <li>Requiring heavy data augmentation (rotating training images) just to generalise</li>
  <li>Still degrading significantly on unseen rotation angles</li>
</ul>

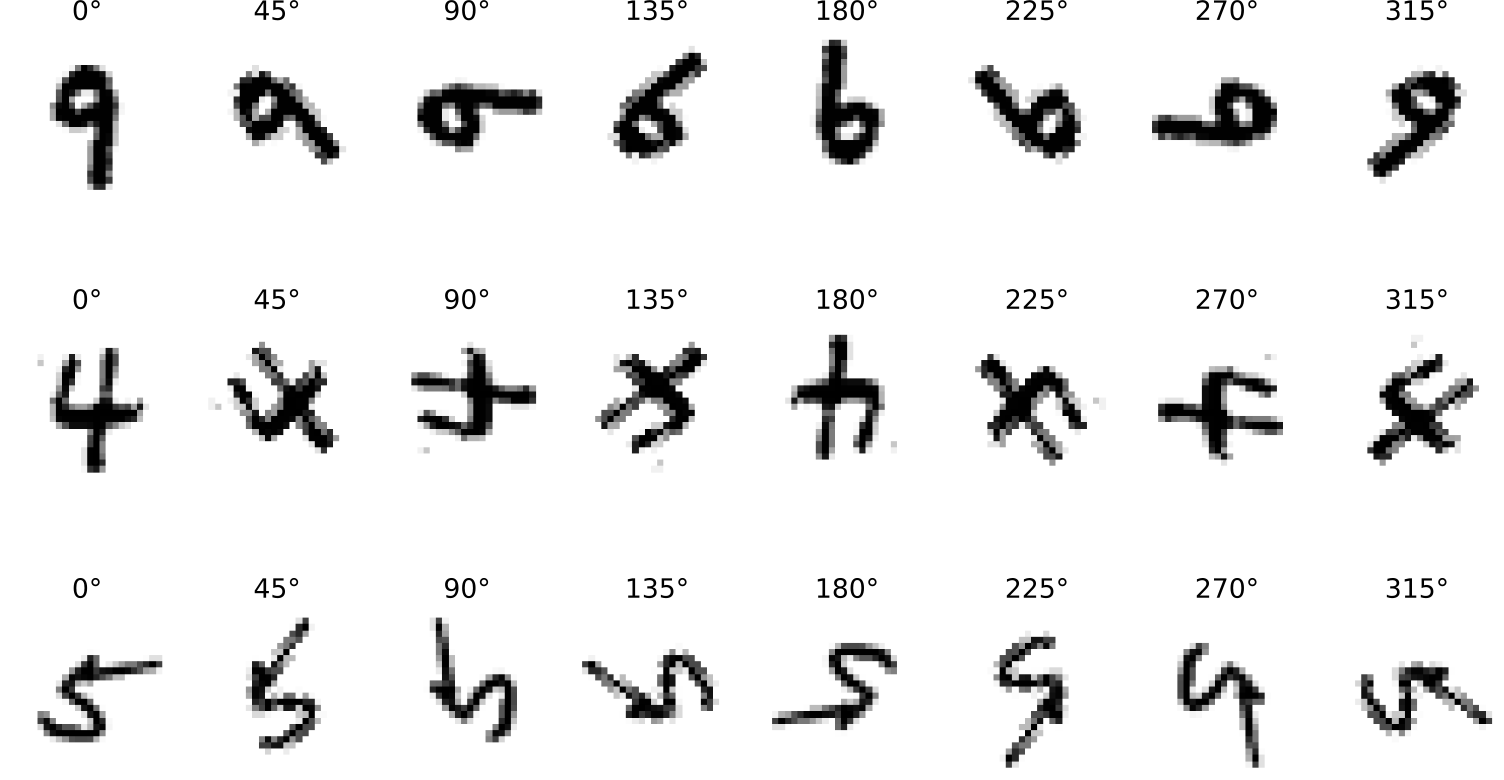
<p>The figure below shows the same digit at 8 different orientations (rotation angles 0°, 45°, 90°, 135°, 180°, 225°, 270°, 315°). The pixel pattern changes completely at each angle, yet the semantic content (the identity of the digit) is identical. A classical CNN trained on upright digits must re-learn each orientation from scratch. Given this limitation, any model that bakes rotation invariance into its architecture rather than learning it from data has a fundamental advantage.</p>

<p><img src="/images/posts/digit_rotate.svg" alt="Digit at different orientations" /></p>

<h1 id="beyond-the-conventional-cnn">Beyond the conventional CNN</h1>

<p>Over the past decade, researchers have been trying to find a way to make neural networks naturally understand things like rotations and symmetry, instead of forcing them to learn these patterns from large amounts of extra data. In other words, they aim to mathematically “hard-bake” geometric symmetries directly into neural network architectures. I will explore methods in representation learning that embed built-in structural mechanisms to help models learn relationships between rotated versions of images. The works that I present here are only a small sample of a much larger body of research and are by no means exhaustive.</p>

<ul>
  <li>
    <p>Chapter 0: <a href="/posts/2026/03/by0/">When machine learns not to panic every time something rotates</a></p>
  </li>
  <li>
    <p>Chapter 1: <a href="/posts/2026/04/by1/">How to learn representations under p4 and p4m symmetry groups</a></p>
  </li>
</ul>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Beyond CNN" /><category term="Equivariance" /><category term="Invariance" /><category term="Convolutional" /><category term="Group theory" /><summary type="html"><![CDATA[Why convolutional neural networks struggle with rotations and reflections, and an introduction to equivariant architectures that go beyond classical CNNs.]]></summary></entry><entry><title type="html">When machine learns not to panic every time something rotates</title><link href="https://yassermb.github.io/posts/2026/03/by0/" rel="alternate" type="text/html" title="When machine learns not to panic every time something rotates" /><published>2026-03-14T00:00:00+00:00</published><updated>2026-03-14T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/03/by0</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/03/by0/"><![CDATA[<p>We begin the journey beyond conventional CNNs with a basic question: how can we teach a machine to separate the true <em>core identity</em> of an object (e.g. a cat) from superficial variations (like its rotation or position)? In 2014, in their paper <a href="https://proceedings.mlr.press/v32/cohen14.html">“Learning the Irreducible Representations of Commutative Lie Groups”</a>, researchers Taco Cohen and Max Welling tackled this question by looking outside of traditional computer science and borrowing ideas from theoretical physics and group theory. Their proposal is built around three complementary axes:</p>

<h2 id="disentanglement-and-invariance">Disentanglement and invariance</h2>
<p>Think of disentangling as taking a complex, blended fruit smoothie and teaching a machine to mathematically separate it back out into pure, individual piles of strawberries, bananas, and yogurt. In computer science, disentanglement means breaking down complex data (e.g. an image) into its individual ingredients (factors of variation), like separating an image into distinct elements such as object’s identity, shape, location, orientation, scale or even lighting condition. Once these factors are neatly separated, achieving invariance, which is the ability to ignore irrelevant changes (e.g. <em>rotation</em> of an object), becomes simple. If you want to identify an object regardless of where it is, you just focus on the <em>identity</em> factor and ignore the <em>position</em> factor, allowing the system to stay consistent even when unimportant details change.</p>

<h2 id="weyls-principle">Weyl’s principle</h2>
<p>Physicists use this principle to figure out what the true, fundamental elementary particles of a system are, separating the real particles from the raw, messy numbers a measuring device might produce which has no physical meaning. This principle is based on the idea of symmetry. Even we change how we measure something (altering its surface appearance or measured values), the core reality of what we are observing stays exactly the same. Cohen and Welling realized that the pixels in a digital image are just like those raw physical measurements, and we need a way to find the “elementary particles” of the image. Although this principle is primarily used in physics, the concept is fully abstract and independent of the data type (such as images, optical flow, or audio), which makes it highly valuable for representation learning. More broadly, it can be applied to any context where a clear notion of symmetry exists.</p>

<h2 id="irreducibility-and-lie-group-theory">Irreducibility and Lie group theory</h2>
<p>Lie group is a mathematical framework used to describe continuous, smooth transformations. Think of the difference between a digital clock that jumps rigidly from 1:00 to 1:01, versus an old analog clock where the second hand sweeps in a perfectly smooth, continuous circle. Conventional neural networks only understood the rigid, jumping steps of a pixel grid. Lie group theory, however, provided the mathematical language to describe a smooth, unbroken sweeping motion—like rotating an image by any microscopic fraction of a degree, rather than just flipping it 90 degrees. In this context, <em>irreducibility</em> means breaking down these complex, continuous transformations into their absolute most fundamental, independent building blocks. Once a transformation is irreducible, it cannot be divided any further into smaller invariant parts, making it the purest elementary component of the system’s symmetry.</p>

<hr />

<p>Applying these three ideas to computer vision, they built a smart probabilistic model called Toroidal Subgroup Analysis (TSA). Instead of relying on the brute-force method of showing a neural network thousands of manually rotated images, TSA learns the underlying mathematical rules of the transformation itself. The model was trained simply by looking at pairs of images: an original image and a transformed version of it. By observing how the image changes from the first to the second frame, the model learns to mathematically disentangle the complex, jumbled web of pixels into simple, independent pieces called <em>irreducible representations</em>.</p>

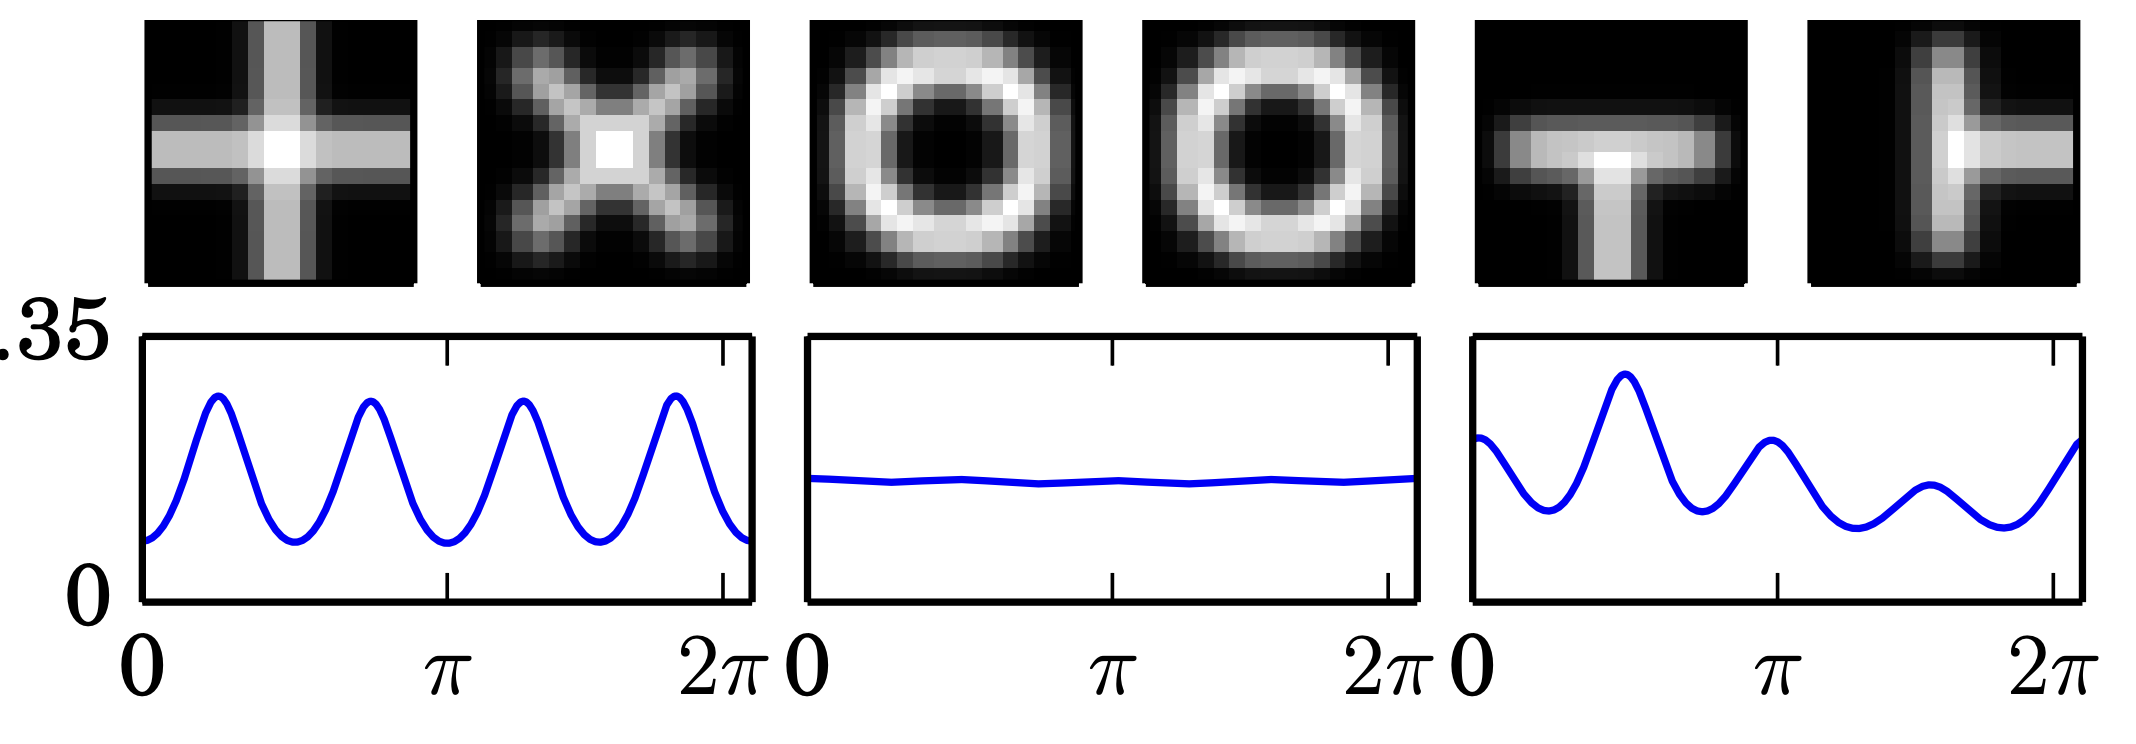
<p>Figure below shows model’s posterior distribution over a rotation angle (denoted as \(s\)) for three distinct pairs of images. The top row shows the initial and rotated images, while the corresponding blue graphs below plot the model’s calculated probability across all possible rotation angles from \(0\) to \(2\pi\). For the first pair (a plus sign rotated into an ‘X’), the distribution displays four distinct peaks due to the shape’s four-fold rotational symmetry, indicating four equally probable rotation angles. The second pair features a circular ‘O’ shape, which results in a completely flat, uniform distribution because its continuous symmetry makes every rotation angle equally valid. The third pair involves a ‘T’ shape lacking rotational symmetry, yielding a graph with a single prominent peak that represents high model certainty for a specific angle.</p>

<p align="center">
  <img src="/images/posts/cohen_welling_2014.png" width="600" /><br />
  <small style="display: block; text-align: justify;">Souce: Cohen, T., &amp; Welling, M. (2014). Learning the irreducible representations of commutative lie groups. In International Conference on Machine Learning</small>
</p>

<p>This work laid the foundation for building neural networks that can naturally handle continuous changes, such as cyclic rotation.</p>

<p>Continue to Chapter 1: <a href="/posts/2026/04/by1/">How to learn representations under p4 and p4m symmetry groups</a></p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Beyond CNN" /><category term="Equivariance" /><category term="Invariance" /><category term="Symmetry" /><category term="Lie group" /><category term="Disentanglement" /><summary type="html"><![CDATA[Equivariant and symmetry-aware representation learning.]]></summary></entry><entry><title type="html">Protein Representation Learning</title><link href="https://yassermb.github.io/posts/2026/01/prl/" rel="alternate" type="text/html" title="Protein Representation Learning" /><published>2026-01-16T00:00:00+00:00</published><updated>2026-01-16T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2026/01/prl</id><content type="html" xml:base="https://yassermb.github.io/posts/2026/01/prl/"><![CDATA[<h1 id="protein-representation-learning-how-we-teach-machines-to-understand-proteins">Protein representation learning: How we teach machines to understand proteins</h1>

<h2 id="proteins">Proteins</h2>

<p>Proteins are fundamental to virtually all biological processes. They fold into intricate 3D shapes, interact with other proteins or molecules, and are behind nearly every cellular machinery. The ability to understand protein sequence, structure, dynamics, interactions, and functions at the molecular level has tremendous implications for therapeutic development, drug discovery, precision medicine, and the rational design of biomolecular interventions.</p>

<p align="center">
  <img src="/images/posts/1JTG.png" width="300" /><br />
</p>

<p>Proteins exhibit complex sequence context and intricate structural organization which govern their thermodynamic stability and functional specificity. Individual proteins may adopt multiple conformational states and carry out diverse functions depending on their structural state and cellular environment.</p>

<p>By analyzing protein sequences and structures we can answer multiple open questions in the protein science, including:</p>

<ul>
  <li>The stability of the protein</li>
  <li>The functional capacity of the protein</li>
  <li>The impact of mutations on protein stability and activity</li>
  <li>The quality of the modeled protein structure, whether obtained experimentally or predicted using computational tools
and enable:</li>
  <li>The rational design of proteins that are geometrically and physico-chemically compatible with a desired function or target</li>
</ul>

<p>These analyses have a wide range of applications in explaining how proteins regulate cellular mechanisms and in enabling the rational design of selective and effective therapeutic agents. Therefore, a comprehensive understanding of the molecular mechanisms behind proteins is essential.</p>

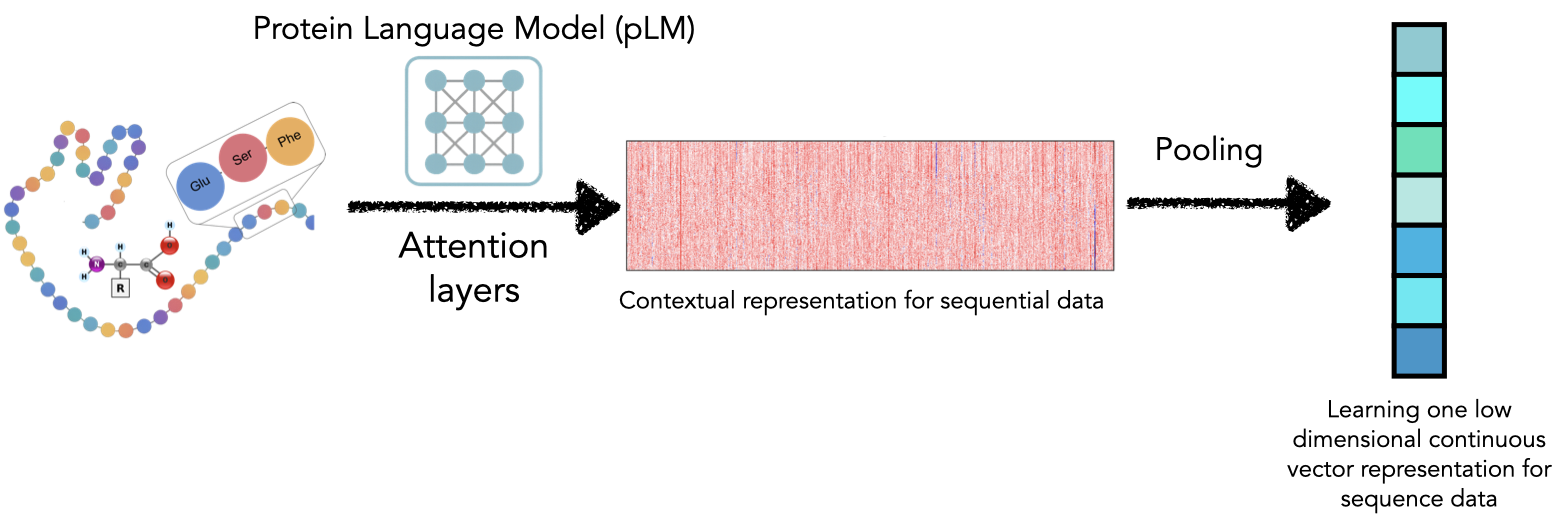
<p>For a machine to reason about proteins, whether predicting their structure, function, or interactions, the first step is deciding <strong>how to represent them</strong>. <em>Protein representation learning</em> focuses on creating dense, rich and low-dimensional representations in a way that they reflect real biological meaning while still being practical and machine-learning-friendly for computational models. Here I give a short, practical overview of main ways proteins are represented and how data-driven and deep learning-based methods represent proteins as a compact vectors (<em>i.e.</em> embeddings).</p>

<h2 id="why-representation-matters">Why representation matters</h2>

<p>At the same time, a protein is:</p>
<ul>
  <li>A <strong>sequence</strong> of amino acids</li>
  <li>A <strong>folded 3D object</strong> with physical constraints</li>
  <li>A <strong>dynamic system</strong> shaped by evolution</li>
  <li>An interconnected <strong>network</strong> of atoms linked by physical interactions</li>
</ul>

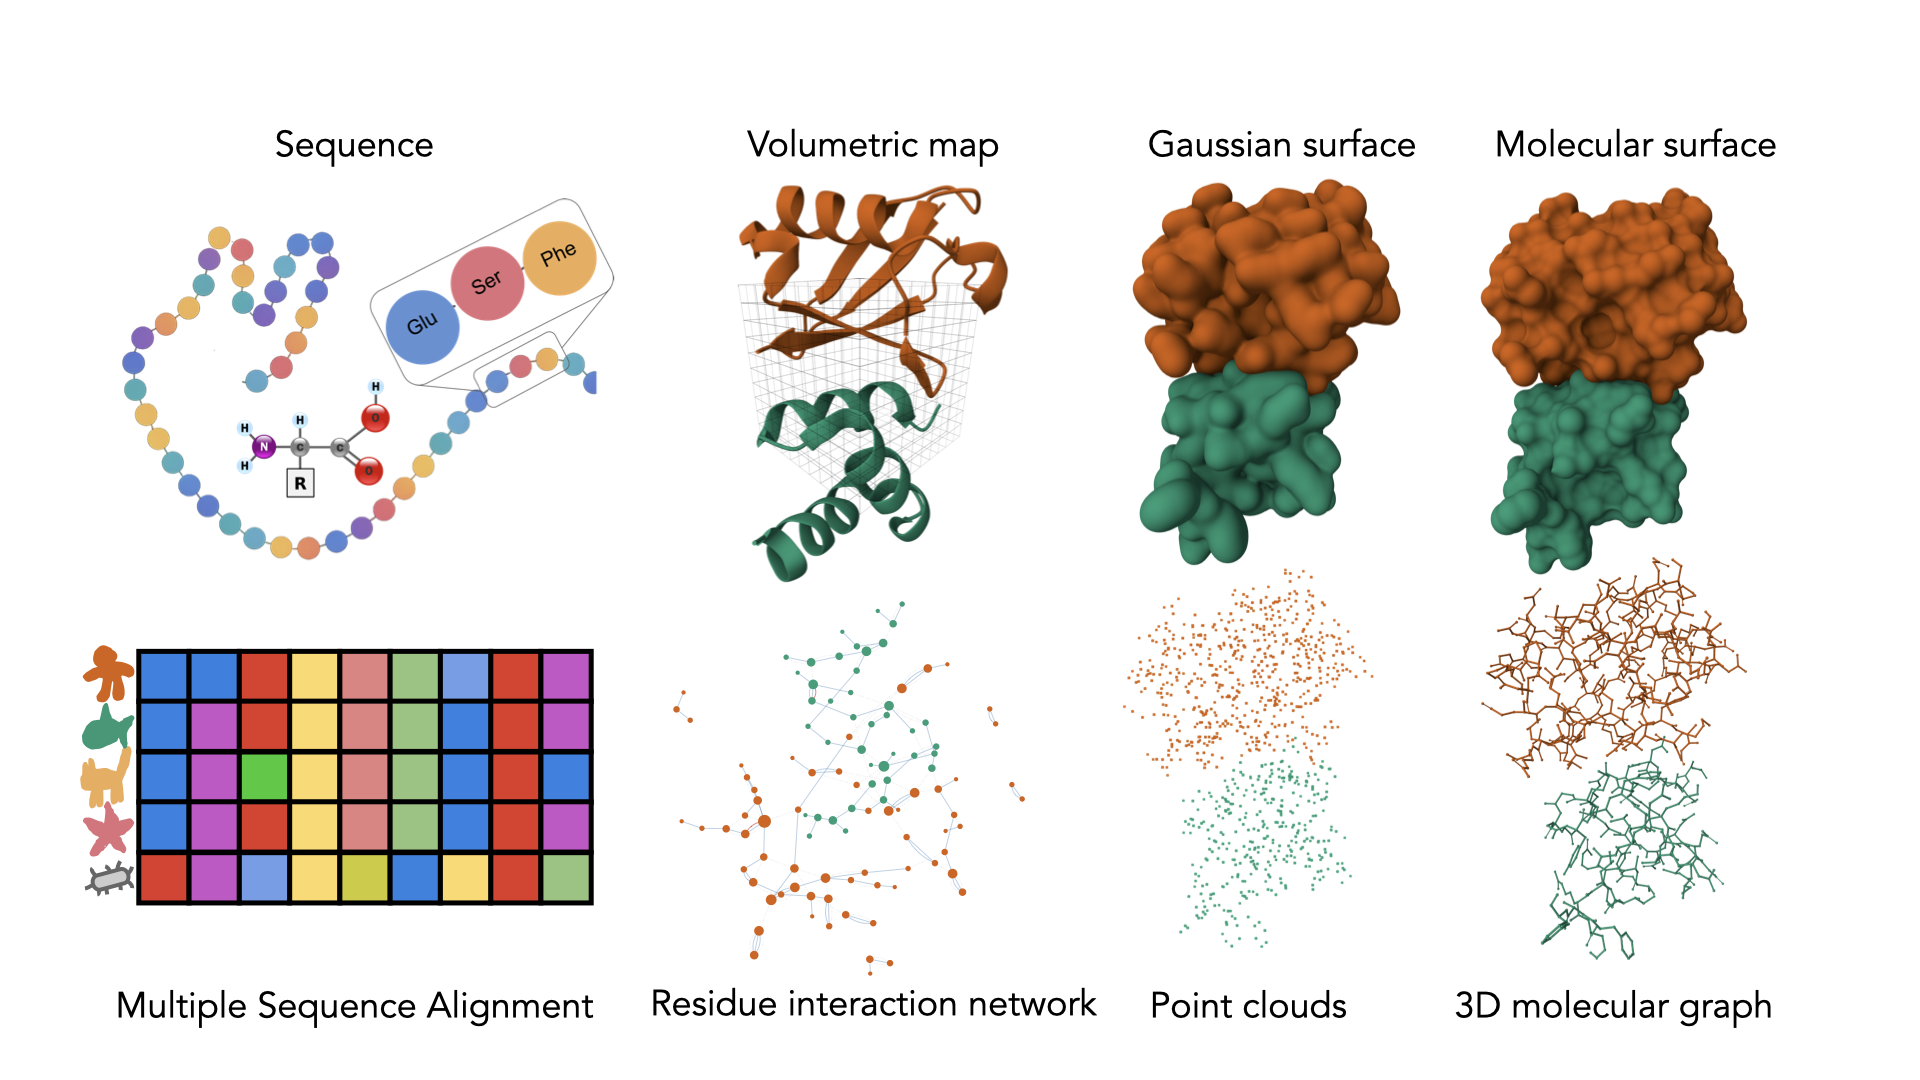
<p>Any representation highlights some of these aspects and ignores others. The choice of representation often determines what a model can (and cannot) learn. A protein (or a protein complex) can be represented in different ways:</p>

<ul>
  <li>Sequence</li>
  <li>Multiple sequence alignment</li>
  <li>Volumetric map</li>
  <li>Gaussian surface</li>
  <li>Molecular surface</li>
  <li>3D molecular graph</li>
  <li>Point clouds</li>
  <li>Residue interaction network</li>
</ul>

<p align="center">
  <img src="/images/posts/protein_representations.png" width="1000" /><br />
</p>

<h2 id="sequence-based-representations">Sequence-based representations</h2>

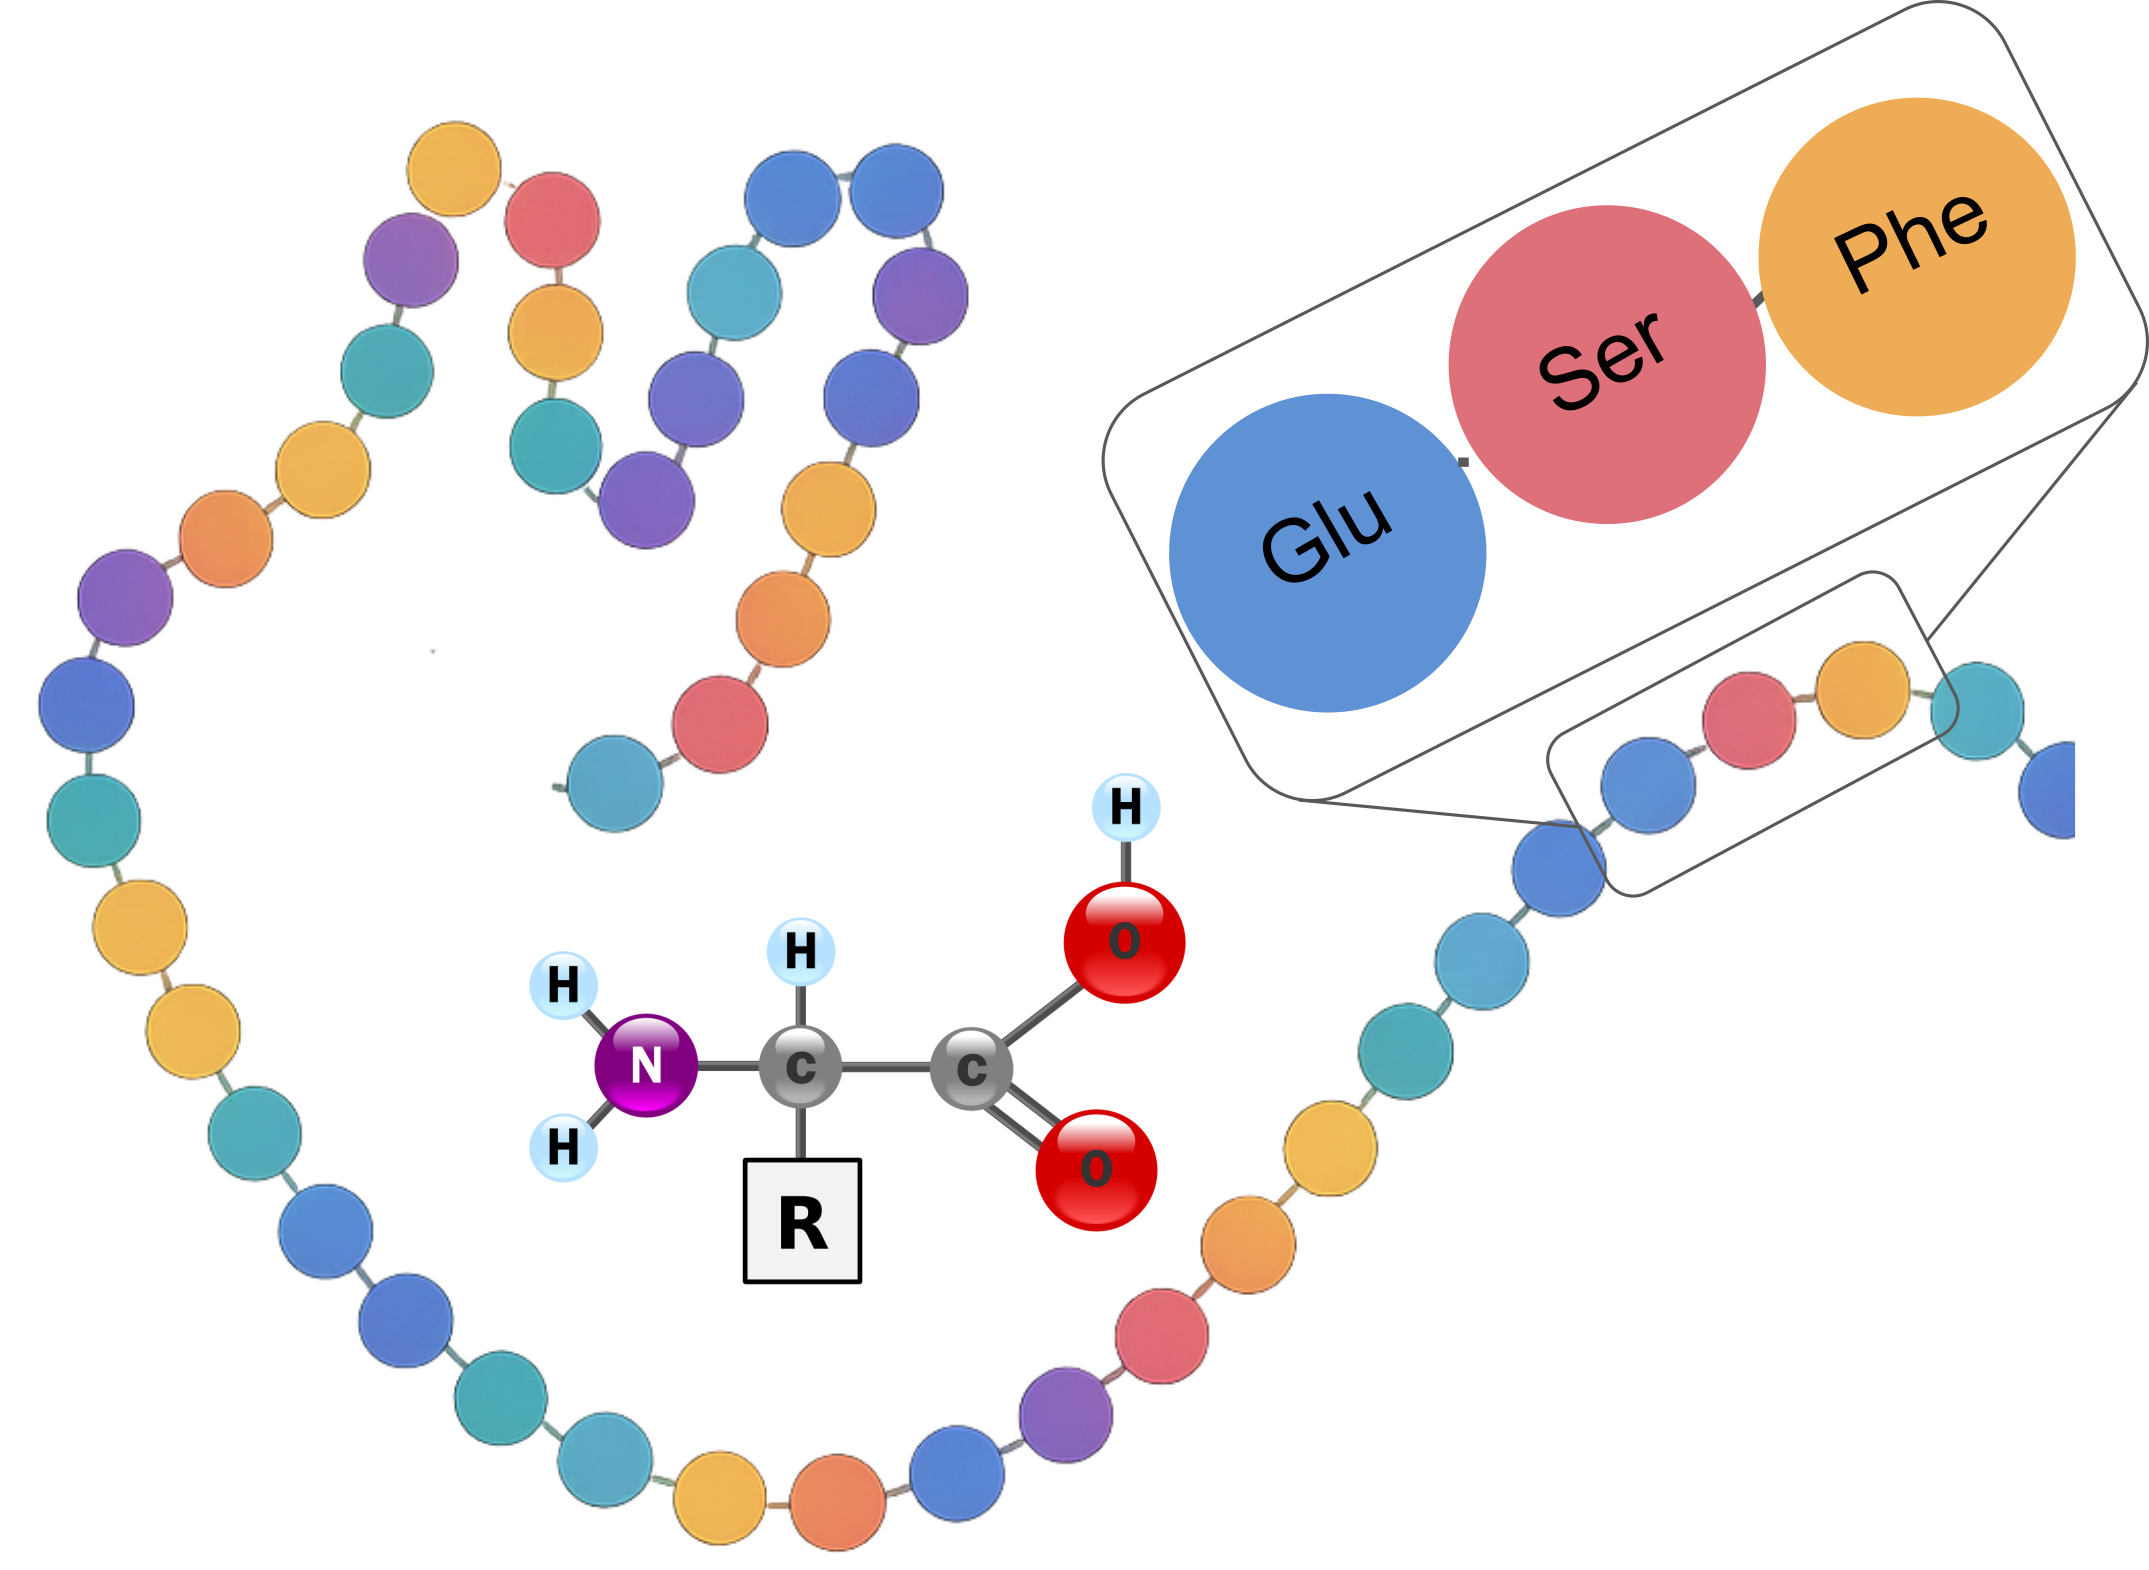
<p>The most basic representation is the amino acid sequence itself.</p>

<p align="center">
  <img src="/images/posts/seq_rep.png" width="350" /><br />
</p>

<p>Early protein sequence representations relied on simple, interpretable methods such as one-hot encoding of individual amino acids, but these approaches scale poorly and fail to model long-range dependencies.</p>

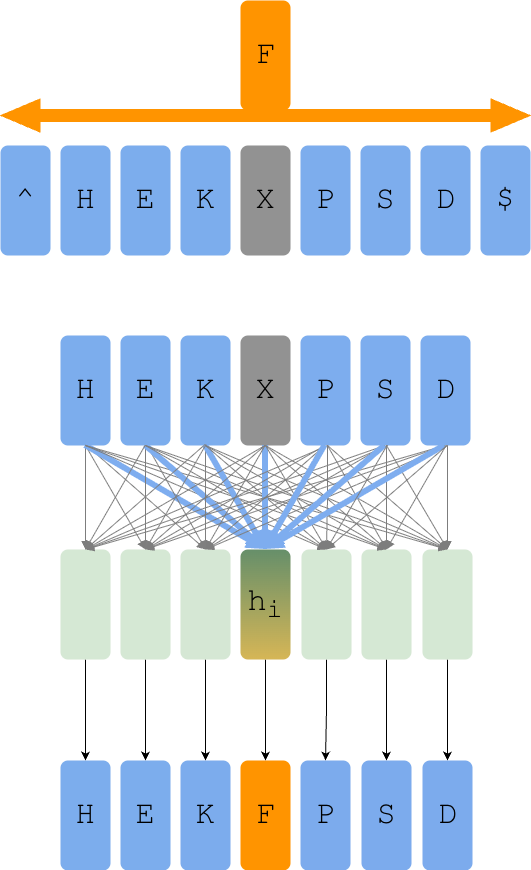
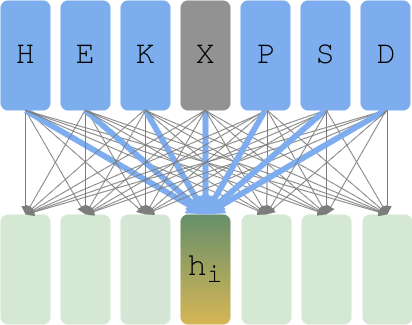
<p>Inspired by advances in natural language processing, modern methods instead learn dense sequence embeddings by treating proteins like language (language of life) using models trained on massive corpora of millions of sequences with self-supervised objectives like masked token prediction.</p>

<p align="center">
  <img src="/images/posts/plm_mlm.png" width="300" /><br />
</p>

<p>These learned embeddings capture rich evolutionary, structural, and functional signals directly from sequence data.</p>

<p align="center">
  <img src="/images/posts/seq_learning.png" width="1000" /><br />
</p>

<p>See my previous post on this topic:<br /> 
<a href="/posts/2024/07/plm/">Protein Language Models</a></p>

<p>Here is a hands-on session on <a href="https://colab.research.google.com/drive/16ddwOia4tr-yvzPKjiCwr6nTC9R8JQ_k">protein sequence representation learning <img src="/images/languagemasking.png" width="100" /></a></p>

<h2 id="evolutionary-representations">Evolutionary representations</h2>

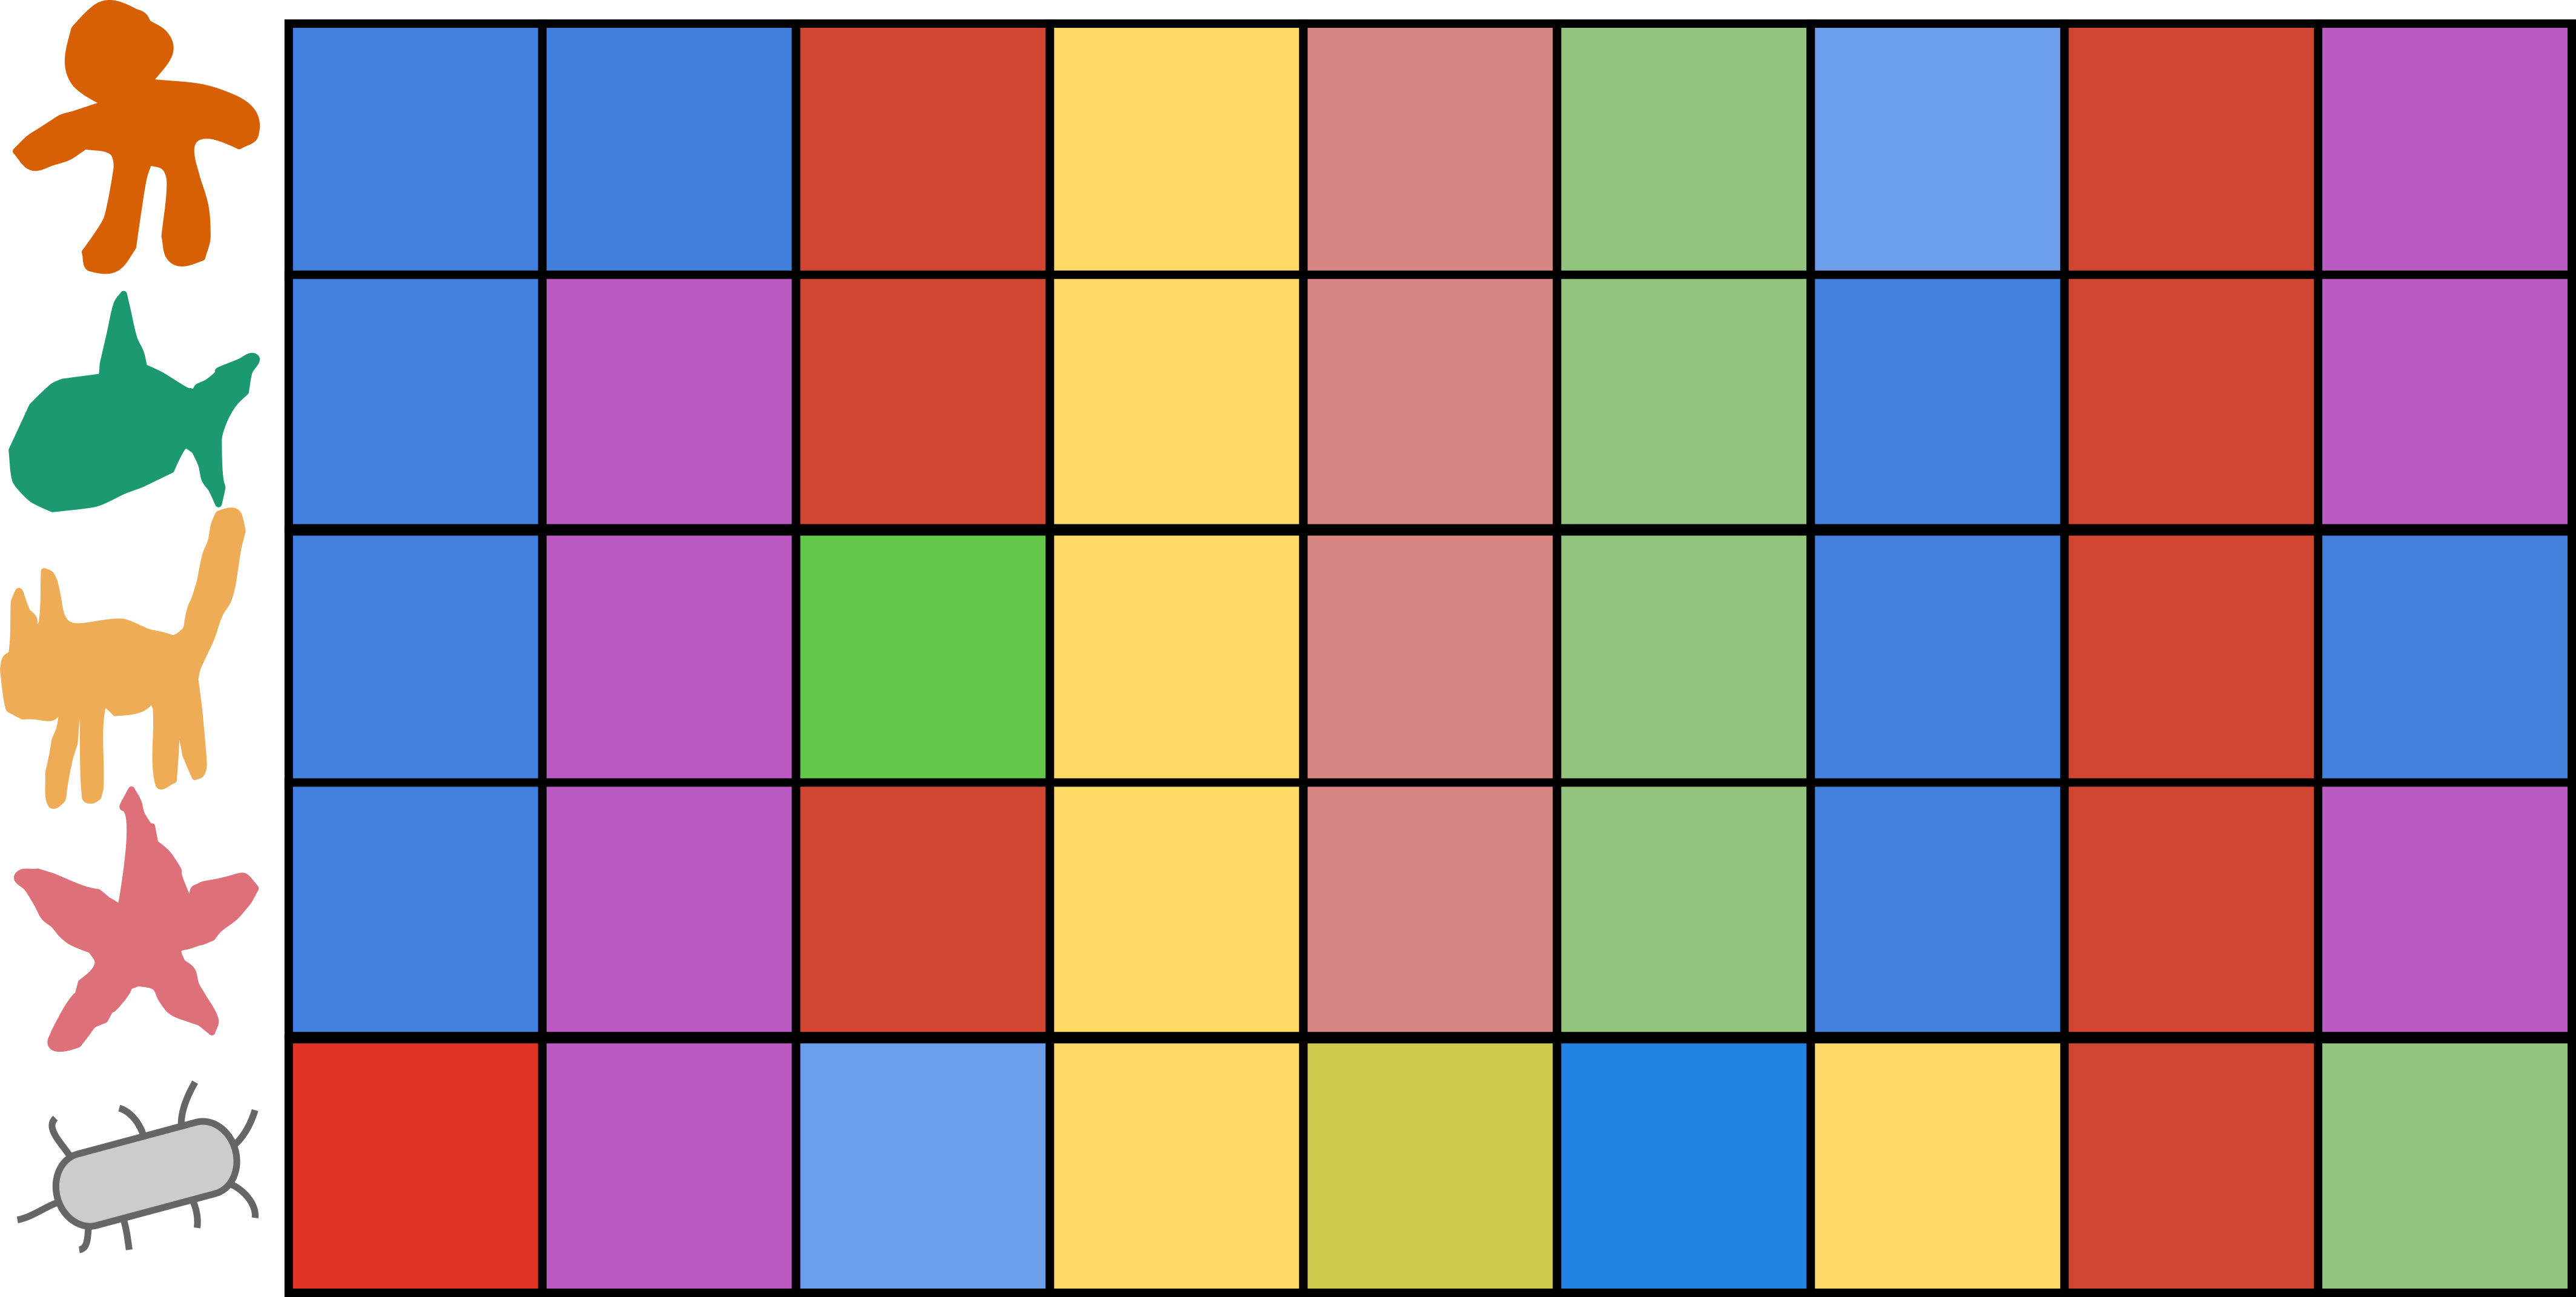
<p>Evolution leaves strong signals in protein families, and multiple sequence alignments (MSAs) make these signals explicit by revealing which residues are conserved or co-evolved across related sequences. Conserved positions often indicate functional or structural importance, while correlated mutations can suggest interacting residues that are spatially close in the folded protein or at the interface of protein-protein interaction. As a result, many structure prediction methods, including early versions of AlphaFold, have relied heavily on MSAs to extract rich evolutionary information, although this comes at the cost of expensive computation and limited applicability to orphan proteins or adaptive immune receptors such as antibodies, nanobodies, and T cell receptors (TCRs) that lack sufficient homologs.</p>

<p align="center">
  <img src="/images/posts/msa_rep.png" width="350" /><br />
</p>

<h2 id="structure-based-representations">Structure-based representations</h2>

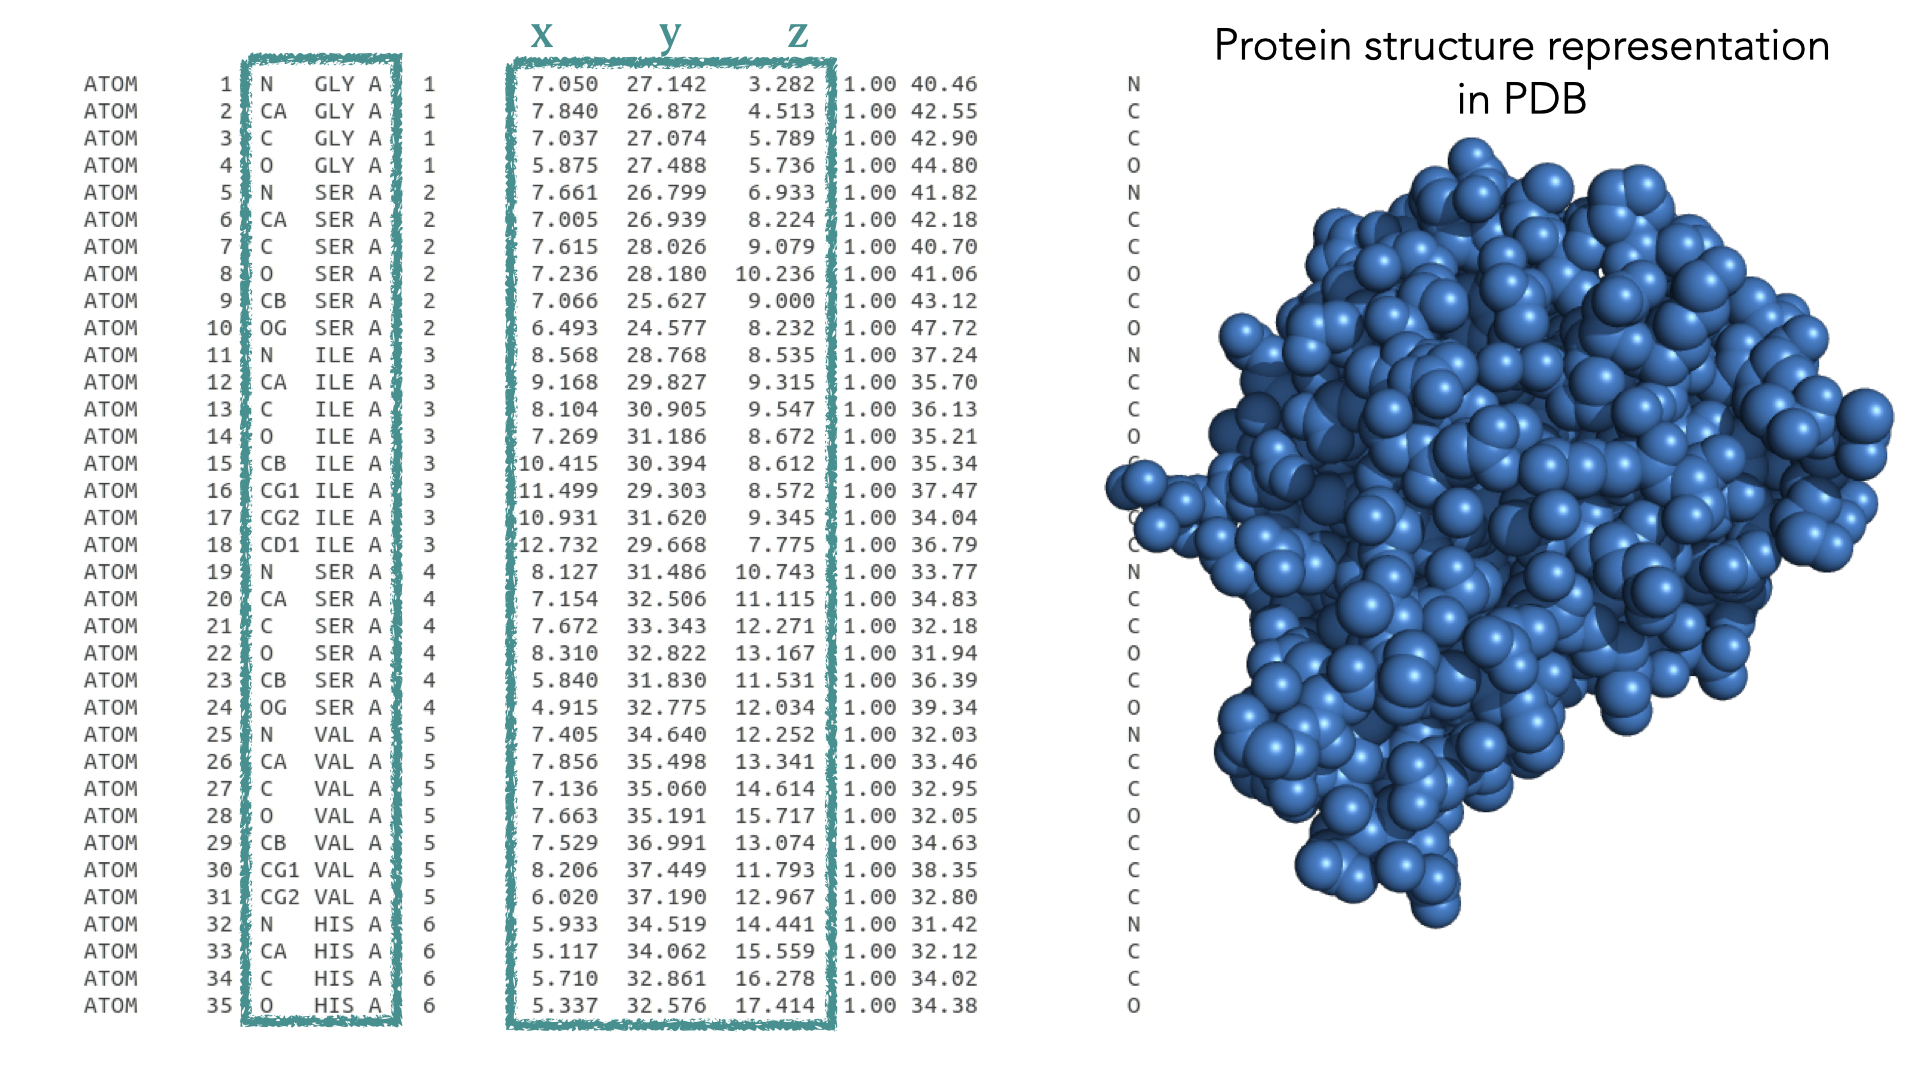
<p>When experimentally determined or computationally predicted 3D structures are available, proteins can be represented with a richer and more intuitive way, a geometric way. Instead of just looking at sequences, we can represent proteins using atomic- or residue-level coordinates, which capture how the protein is actually arranged in the 3D space.</p>

<p align="center">
  <img src="/images/posts/pdb_rep.png" width="700" /><br />
</p>

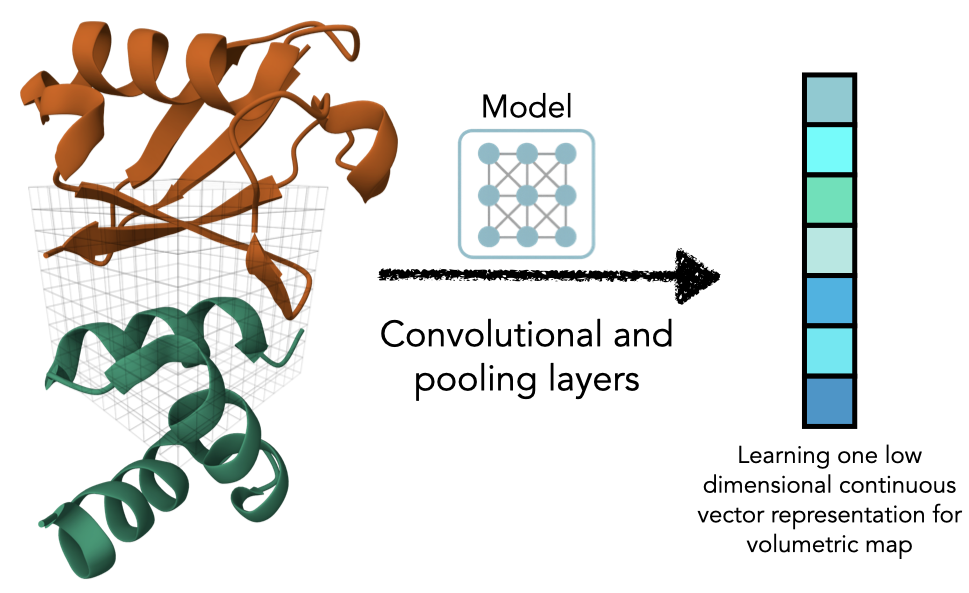
<p>3 dimensional convolutional neural networks (3D-CNN) can represent an intricate arangement of atoms in a space as a compact vector useful for classification or regression tasks.</p>

<p align="center">
  <img src="/images/posts/volume_learning.png" width="600" /><br />
</p>

<h3 id="3d-volumetric-maps">3D volumetric maps</h3>

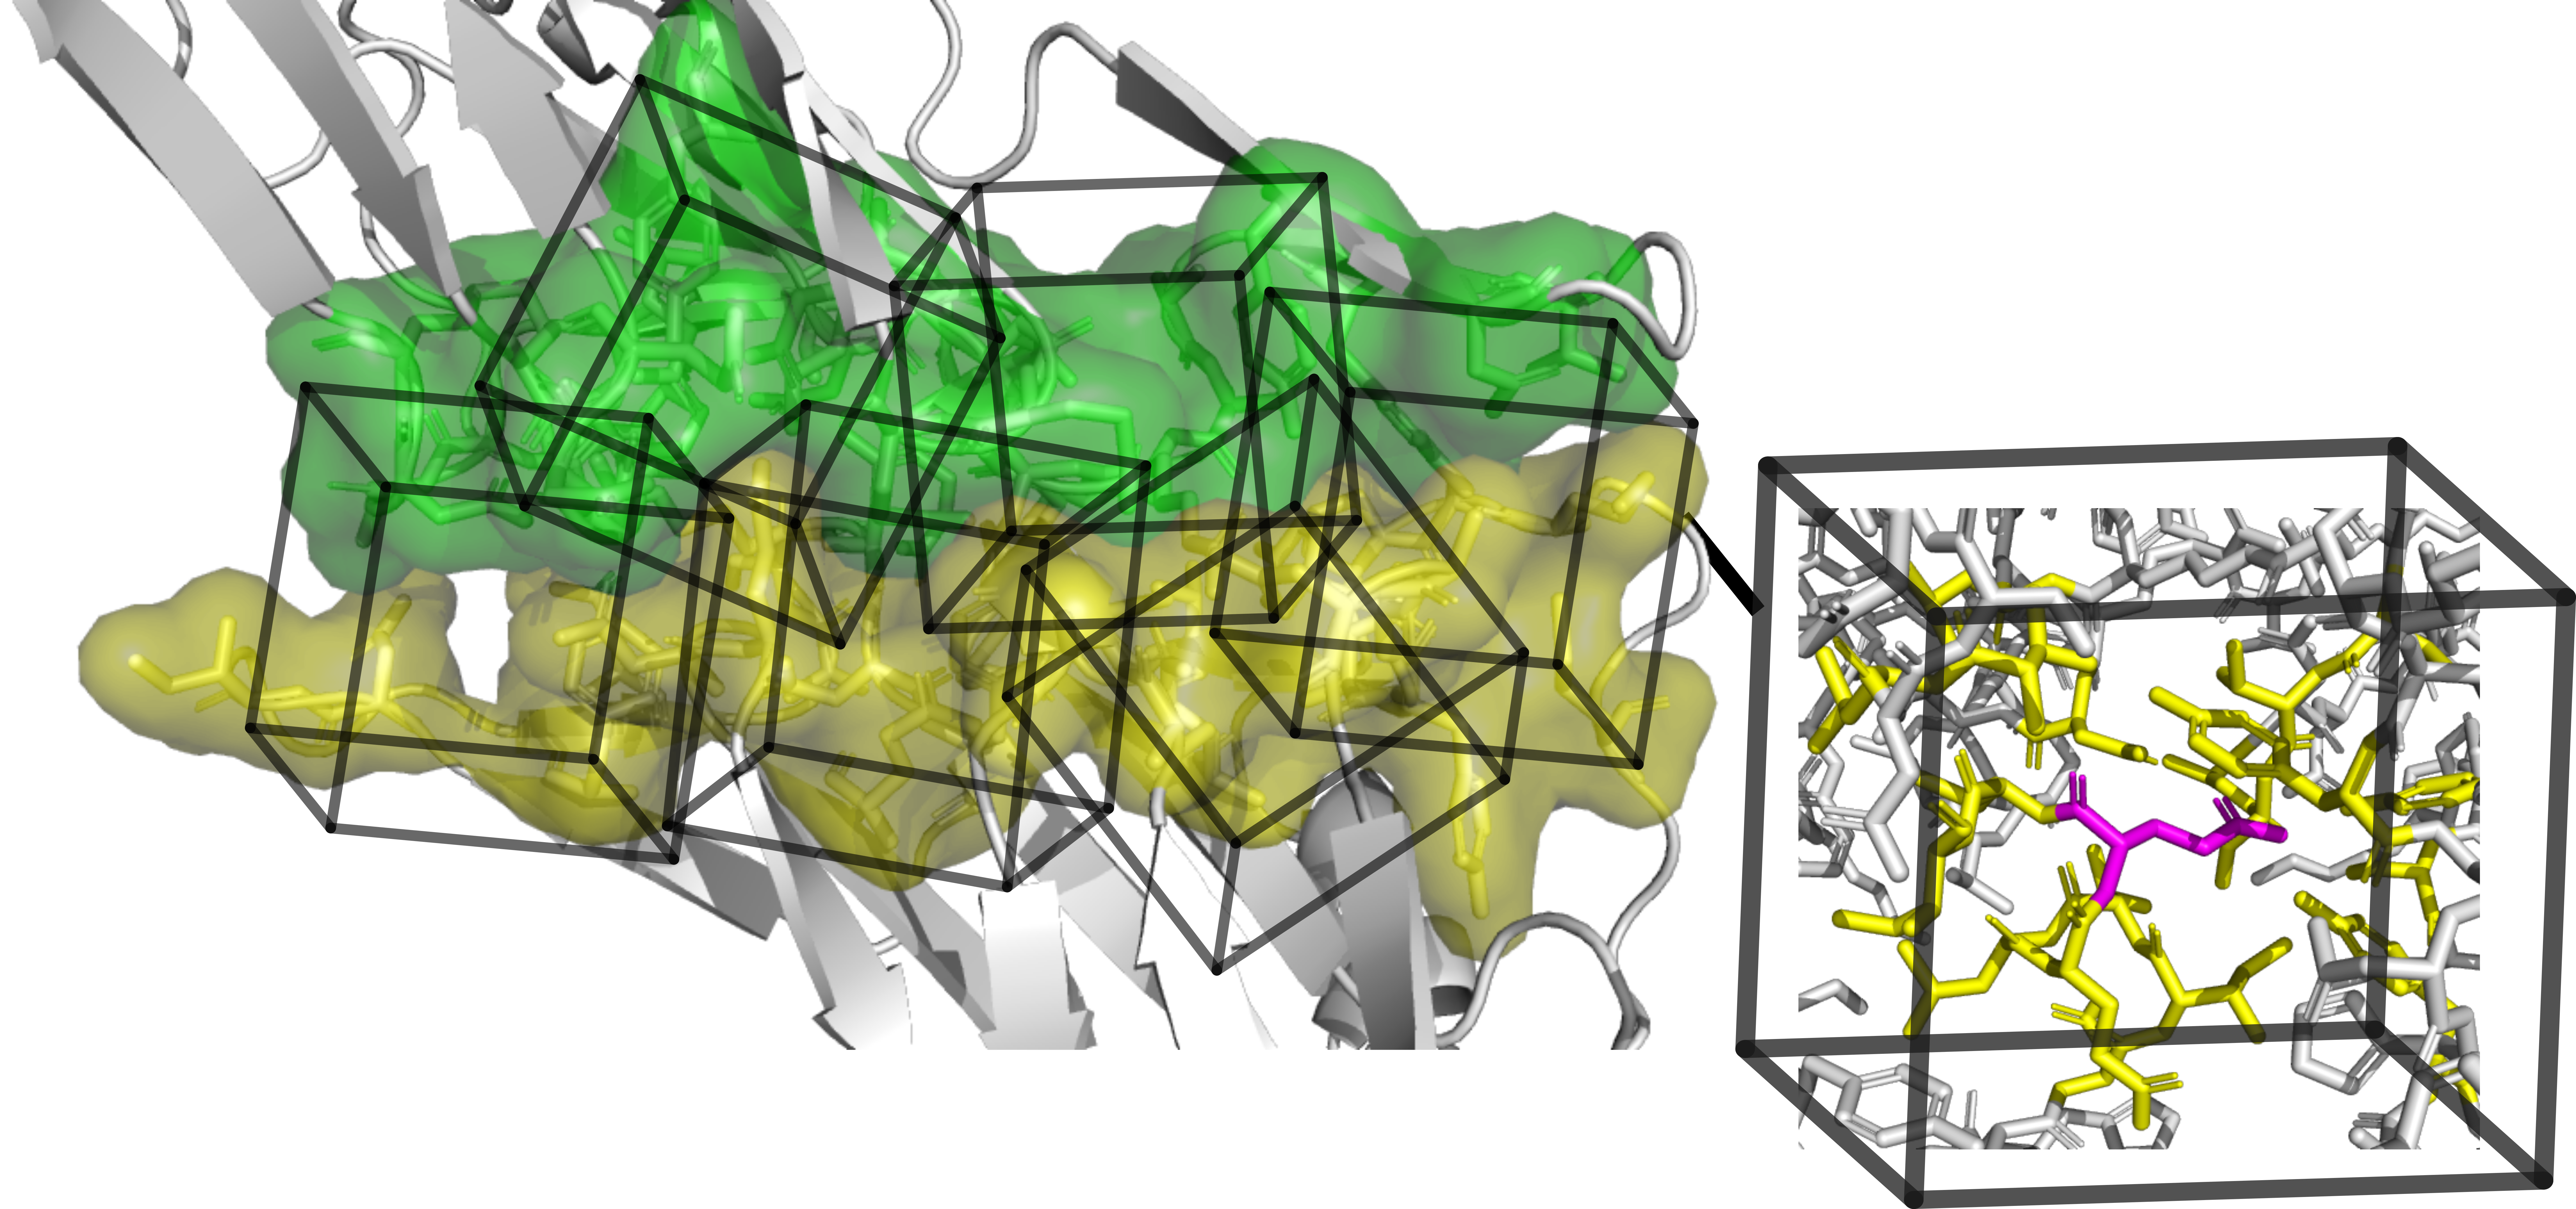
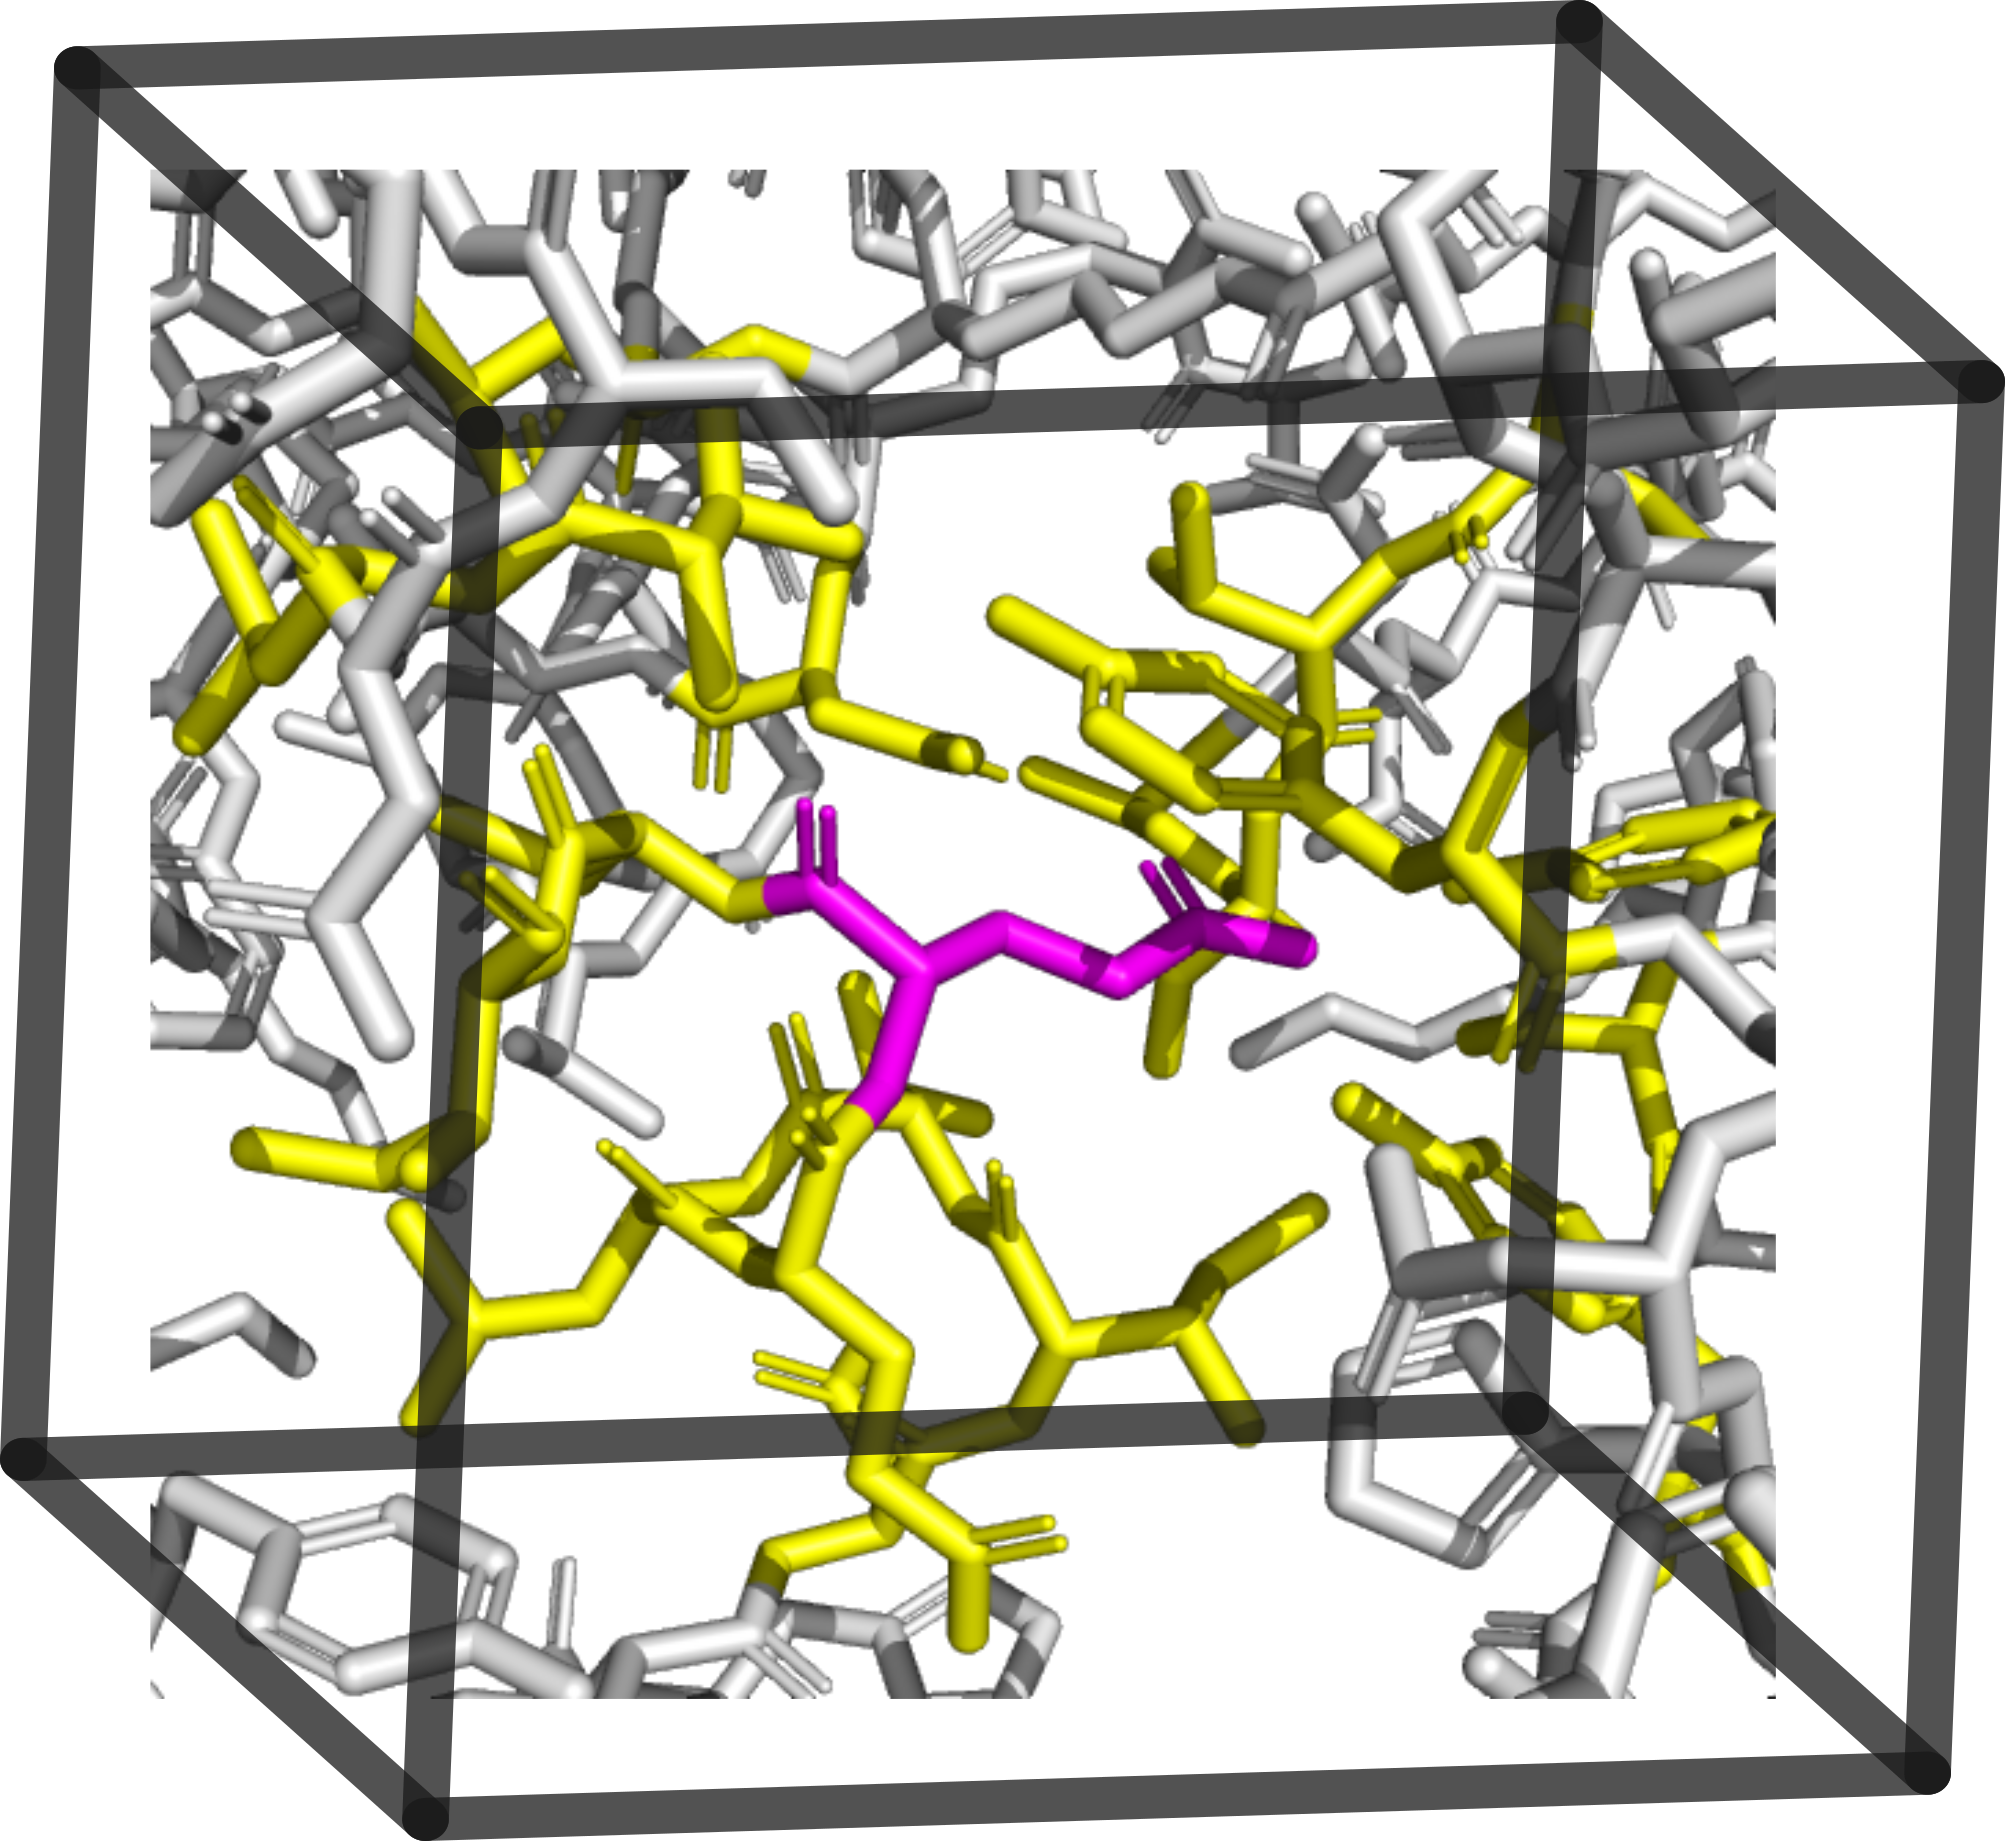
<p>These coordinate-based representations are often either inherently invariant representations or processed with equivariant neural networks. An example of inherently invariant representation is 3D volumetric maps that are centered and oriented based on the common scaffold of the backbone of amino acids.</p>

<p align="center">
  <img src="/images/posts/set_local_cubes.png" width="700" /><br />
</p>

<p>Here is a hands-on session on how to learn <a href="https://colab.research.google.com/drive/1cQ3POBsdfUM1gg2VN4hX6Ps8ZIC1B7n_?usp=sharing">3D volumetric maps of protein structures <img src="/images/local_env_cube.png" width="100" /></a></p>

<p>On the other hand equvariant neural networks naturally respect rotational and translational symmetry. It means the protein’s properties don’t change just because we rotate or shift it in space.</p>

<p>See my previous posts on this topic:<br /> 
<a href="/posts/2024/07/gdl/">Geometric Deep Learning</a> and <a href="/posts/2024/07/equ/">Equivariance and Invariance</a></p>

<h3 id="graph-representation-learning">Graph representation learning</h3>

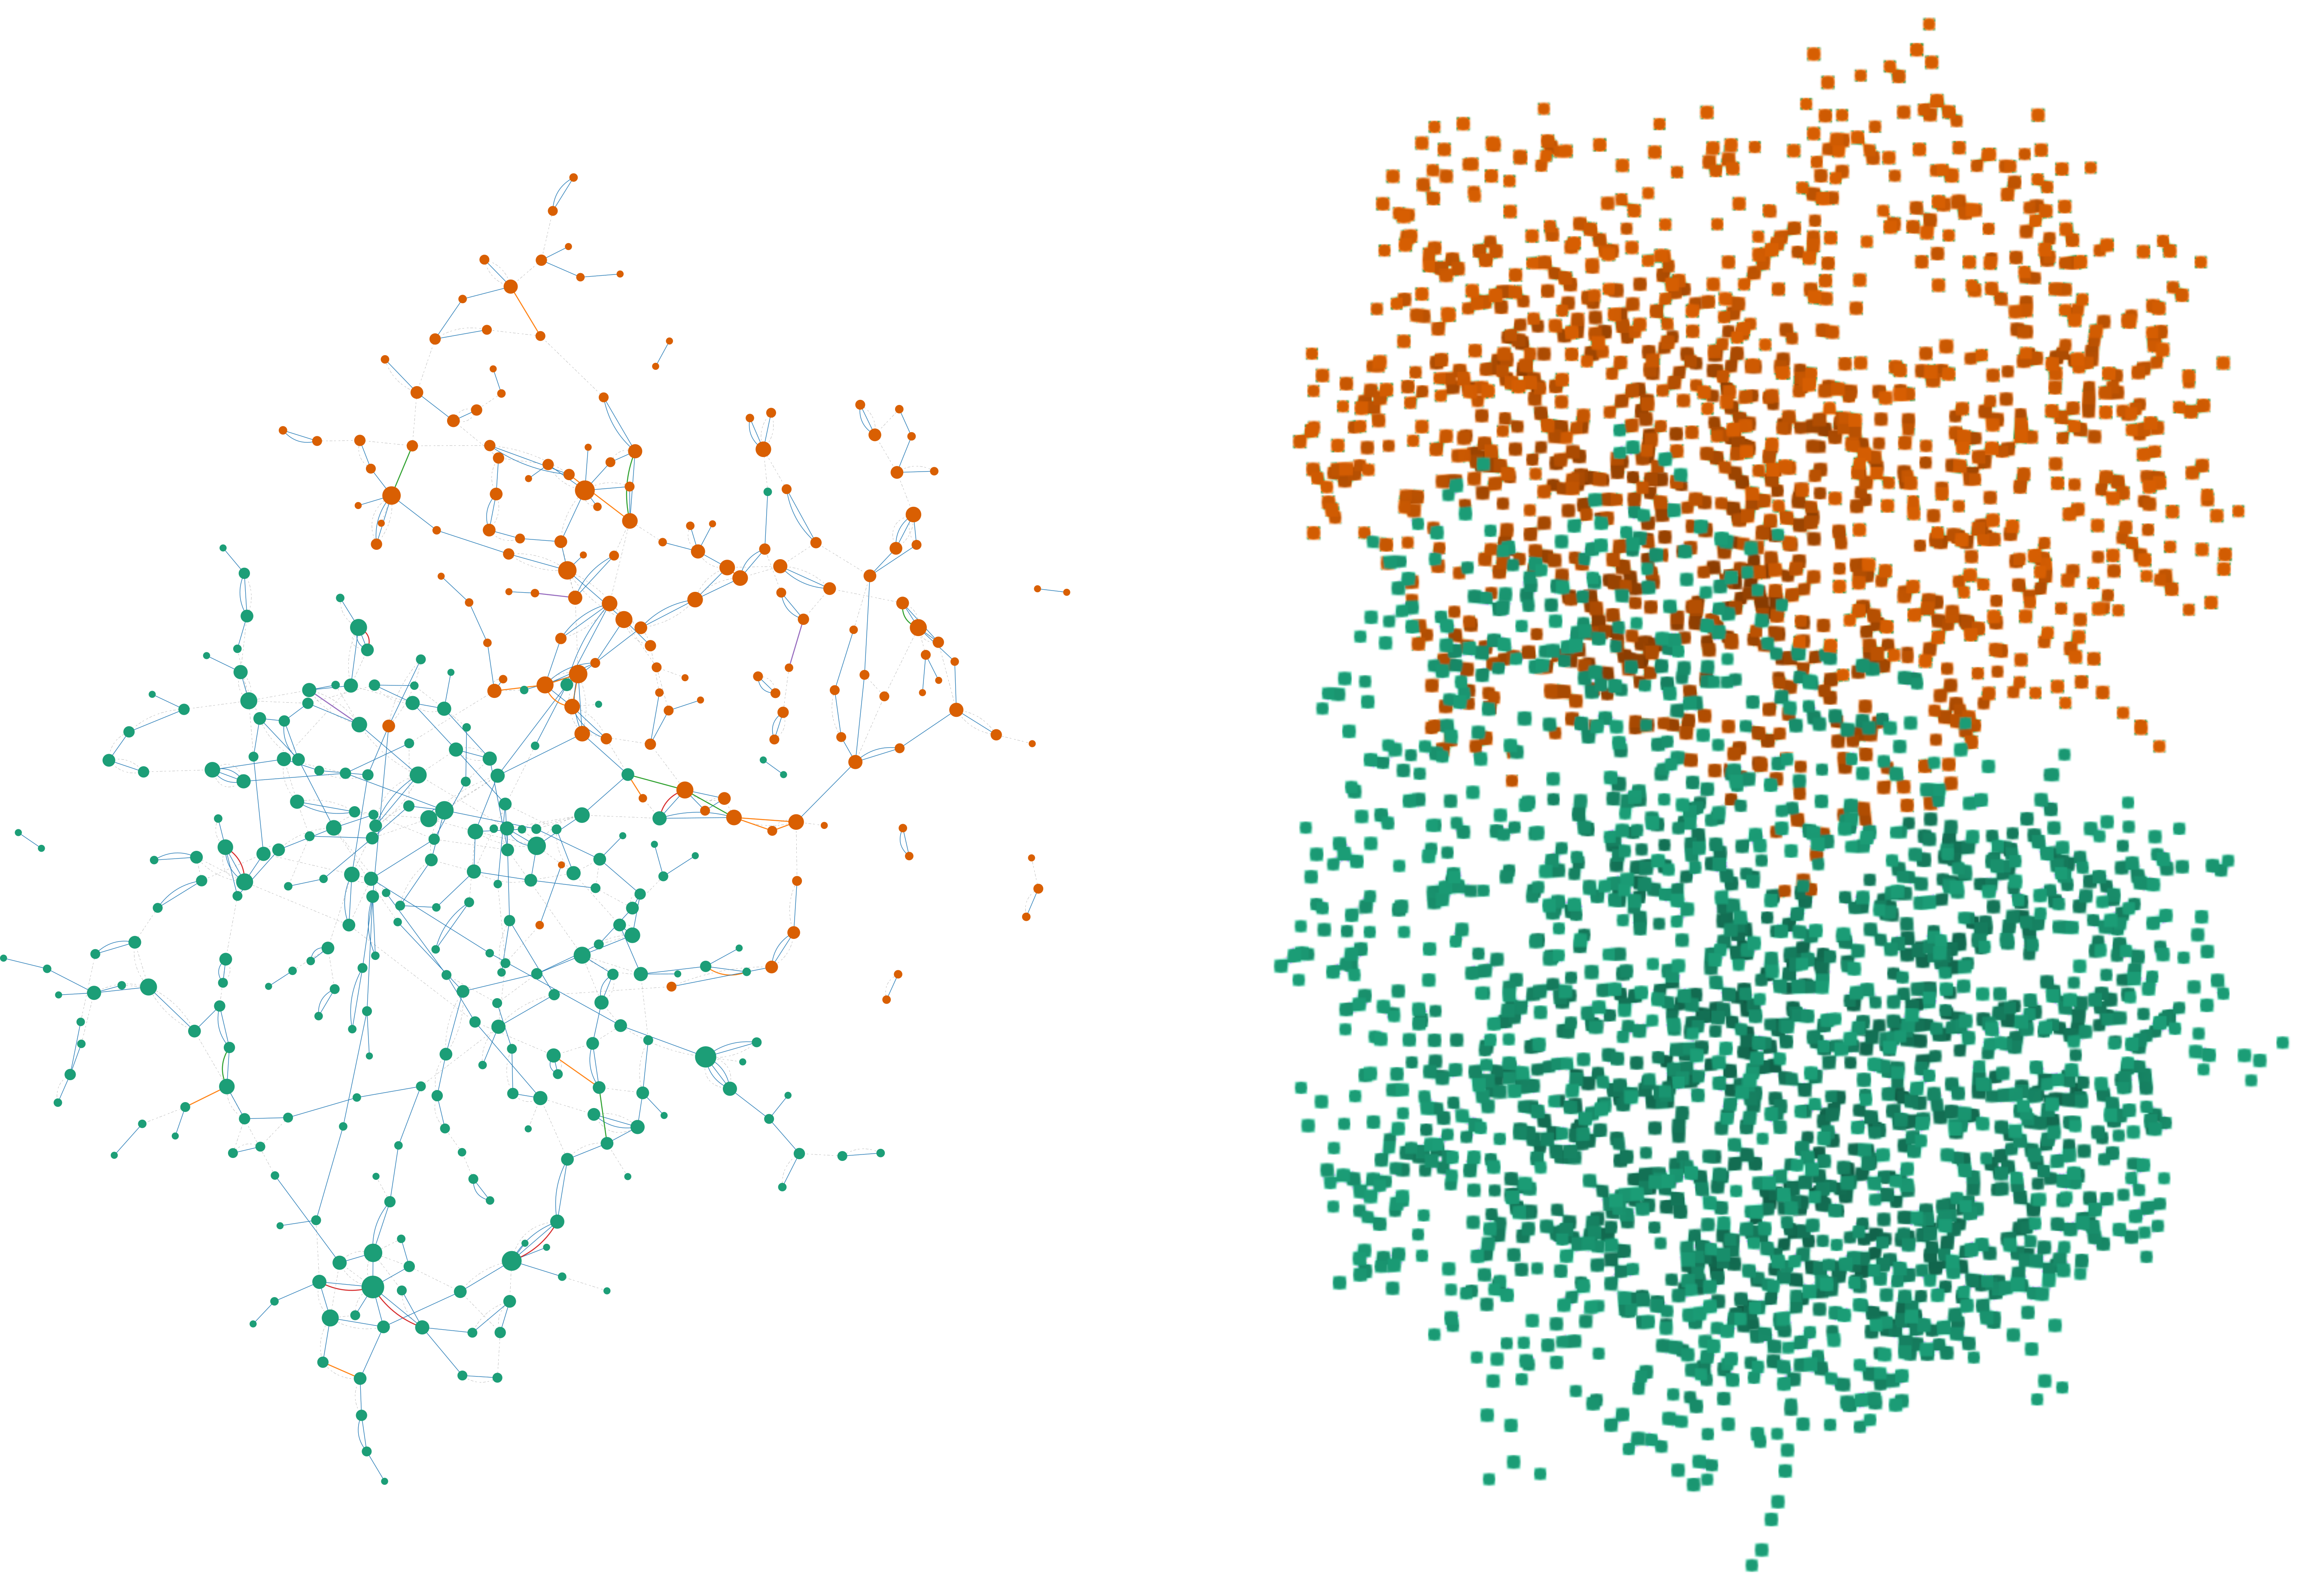
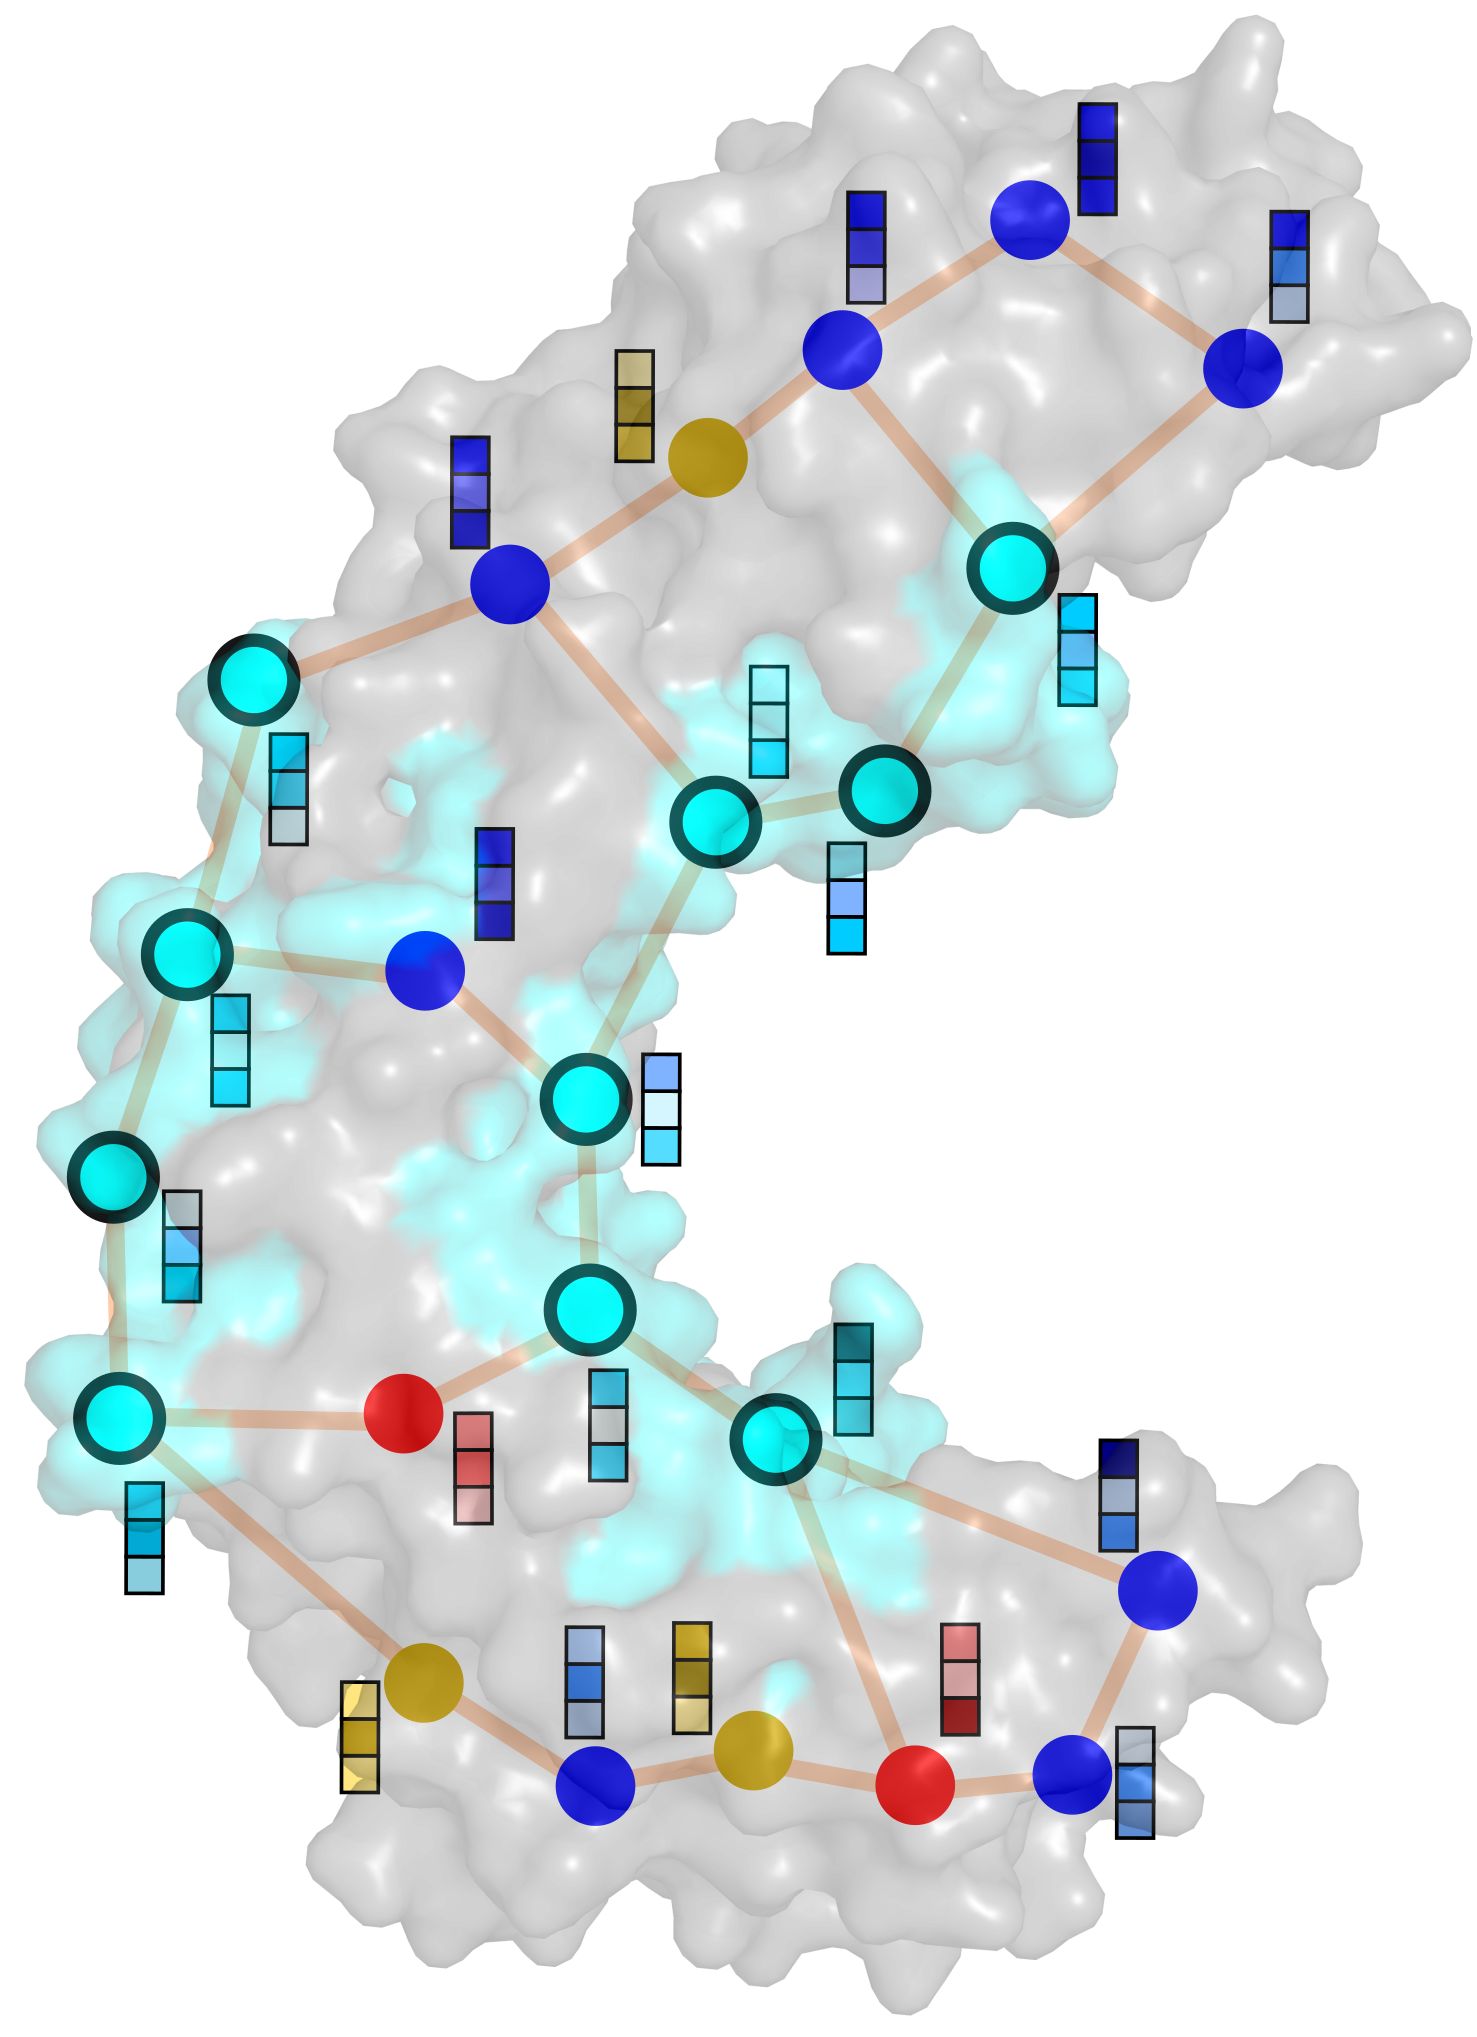
<p>Another common approach is to model the structure as a graph or point cloud, where nodes represent residues or atoms and edges are spatial proximity, covalent or molecular bonds, or other types of interaction.</p>

<p align="center">
  <img src="/images/posts/graph_cloud.png" width="700" /><br />
</p>

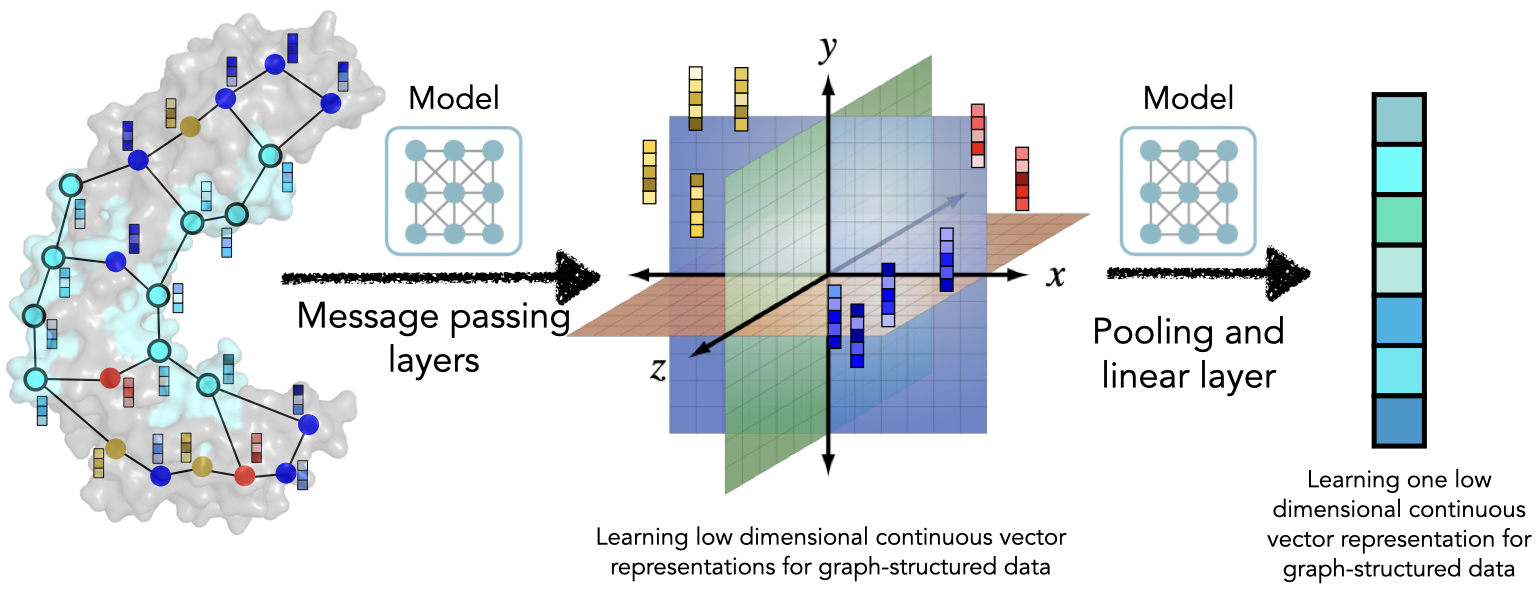
<p>Graph neural networks (GNNs) are particularly well suited to this setting and have become increasingly popular for structural modeling. Using different variants of the <em>message-passing</em> algorithm, GNNs iteratively update node and edge features, as well as spatial coordinates in the case of SE(3)-Transformers equivariant architecture. At each iteration, nodes aggregate information from their neighbors, progressively incorporating information from increasingly distant nodes. After several message-passing steps, each node representation captures both its local neighborhood and the broader topology and features of the graph. These node representations can then be pooled into a single compact vector that summarizes the entire graph.</p>

<p align="center">
  <img src="/images/posts/gnn_learning.png" width="1000" /><br />
</p>

<p>Here is a hands-on session on <a href="https://colab.research.google.com/drive/1bbQE7PlnmDiQpX6wgx2Z75gHS0zMp3tA">graph representation learning <img src="/images/small_graph.svg" width="100" /></a></p>

<p>The big advantage of these geometric approaches is that they explicitly encode physical and spatial information. However, obtaining reliable 3D structures can be expensive and time-consuming, and even predicted structures may be noisy or incomplete.</p>

<h2 id="conclusion">Conclusion</h2>
<p>Protein representation learning is at the intersection of biology, physics, and machine learning, aiming to turn the complexity of proteins into forms that computer models can actually understand and use. One of its biggest strengths is transferability: once a model has learned a meaningful representation, it can be reused across many downstream tasks with little additional supervision, saving both time and data. That said, there is no single “best” representation! There are only ones that fit particular questions and constraints. For instance, if we study highly flexible regions of a protein, a static, structure-based representation might miss important biophysical realities, whereas a sequence-based approach, implicitly capturing aspects of dynamics and function, or an explicitly dynamics-based representation could be more appropriate. We have only begun to scratch the surface; as models become more multimodal and grounded in biophysical principles, representations are shifting from hand-crafted features to deeply learned ones, bringing us closer to truly capturing the rich and nuanced complexity of proteins.</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Representation learning" /><category term="Proteins" /><category term="Structure" /><category term="Sequence" /><summary type="html"><![CDATA[An overview of protein representation learning: how machine learning models encode protein sequence, structure, and dynamics to study stability, function, and interactions.]]></summary></entry><entry><title type="html">Protein Language Models</title><link href="https://yassermb.github.io/posts/2024/07/plm/" rel="alternate" type="text/html" title="Protein Language Models" /><published>2024-07-29T00:00:00+00:00</published><updated>2024-07-29T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2024/07/plm</id><content type="html" xml:base="https://yassermb.github.io/posts/2024/07/plm/"><![CDATA[<h1 id="learning-the-language-of-life">Learning the language of life</h1>

<p>What are Protein Language Models?</p>

<p>Just like human languages, nature has its own unique language—the language of life! This language dictates the cellular mechanisms within all living organisms. By understanding it, we can gain insights into biological processes and answer essential questions, such as: What are the 3D structures of proteins? How do proteins interact? and What are the impacts of mutations on proteins and their interactions?</p>

<p>So how can we understand the language of life? luckily the advances in deep learning algorithms (e.g. transformers and masked language modeling) and the advent of large language models (LLM) have paved the way. Thanks to these algorithms, we now have a class of pre-trained models, known as protein language models (pLM), that help us analyze protein sequences.</p>

<p>Let’s briefly introduce LLMs, which share the same underlying architectures to understand better how pLMs work.</p>

<h2 id="large-language-models">Large Language Models</h2>
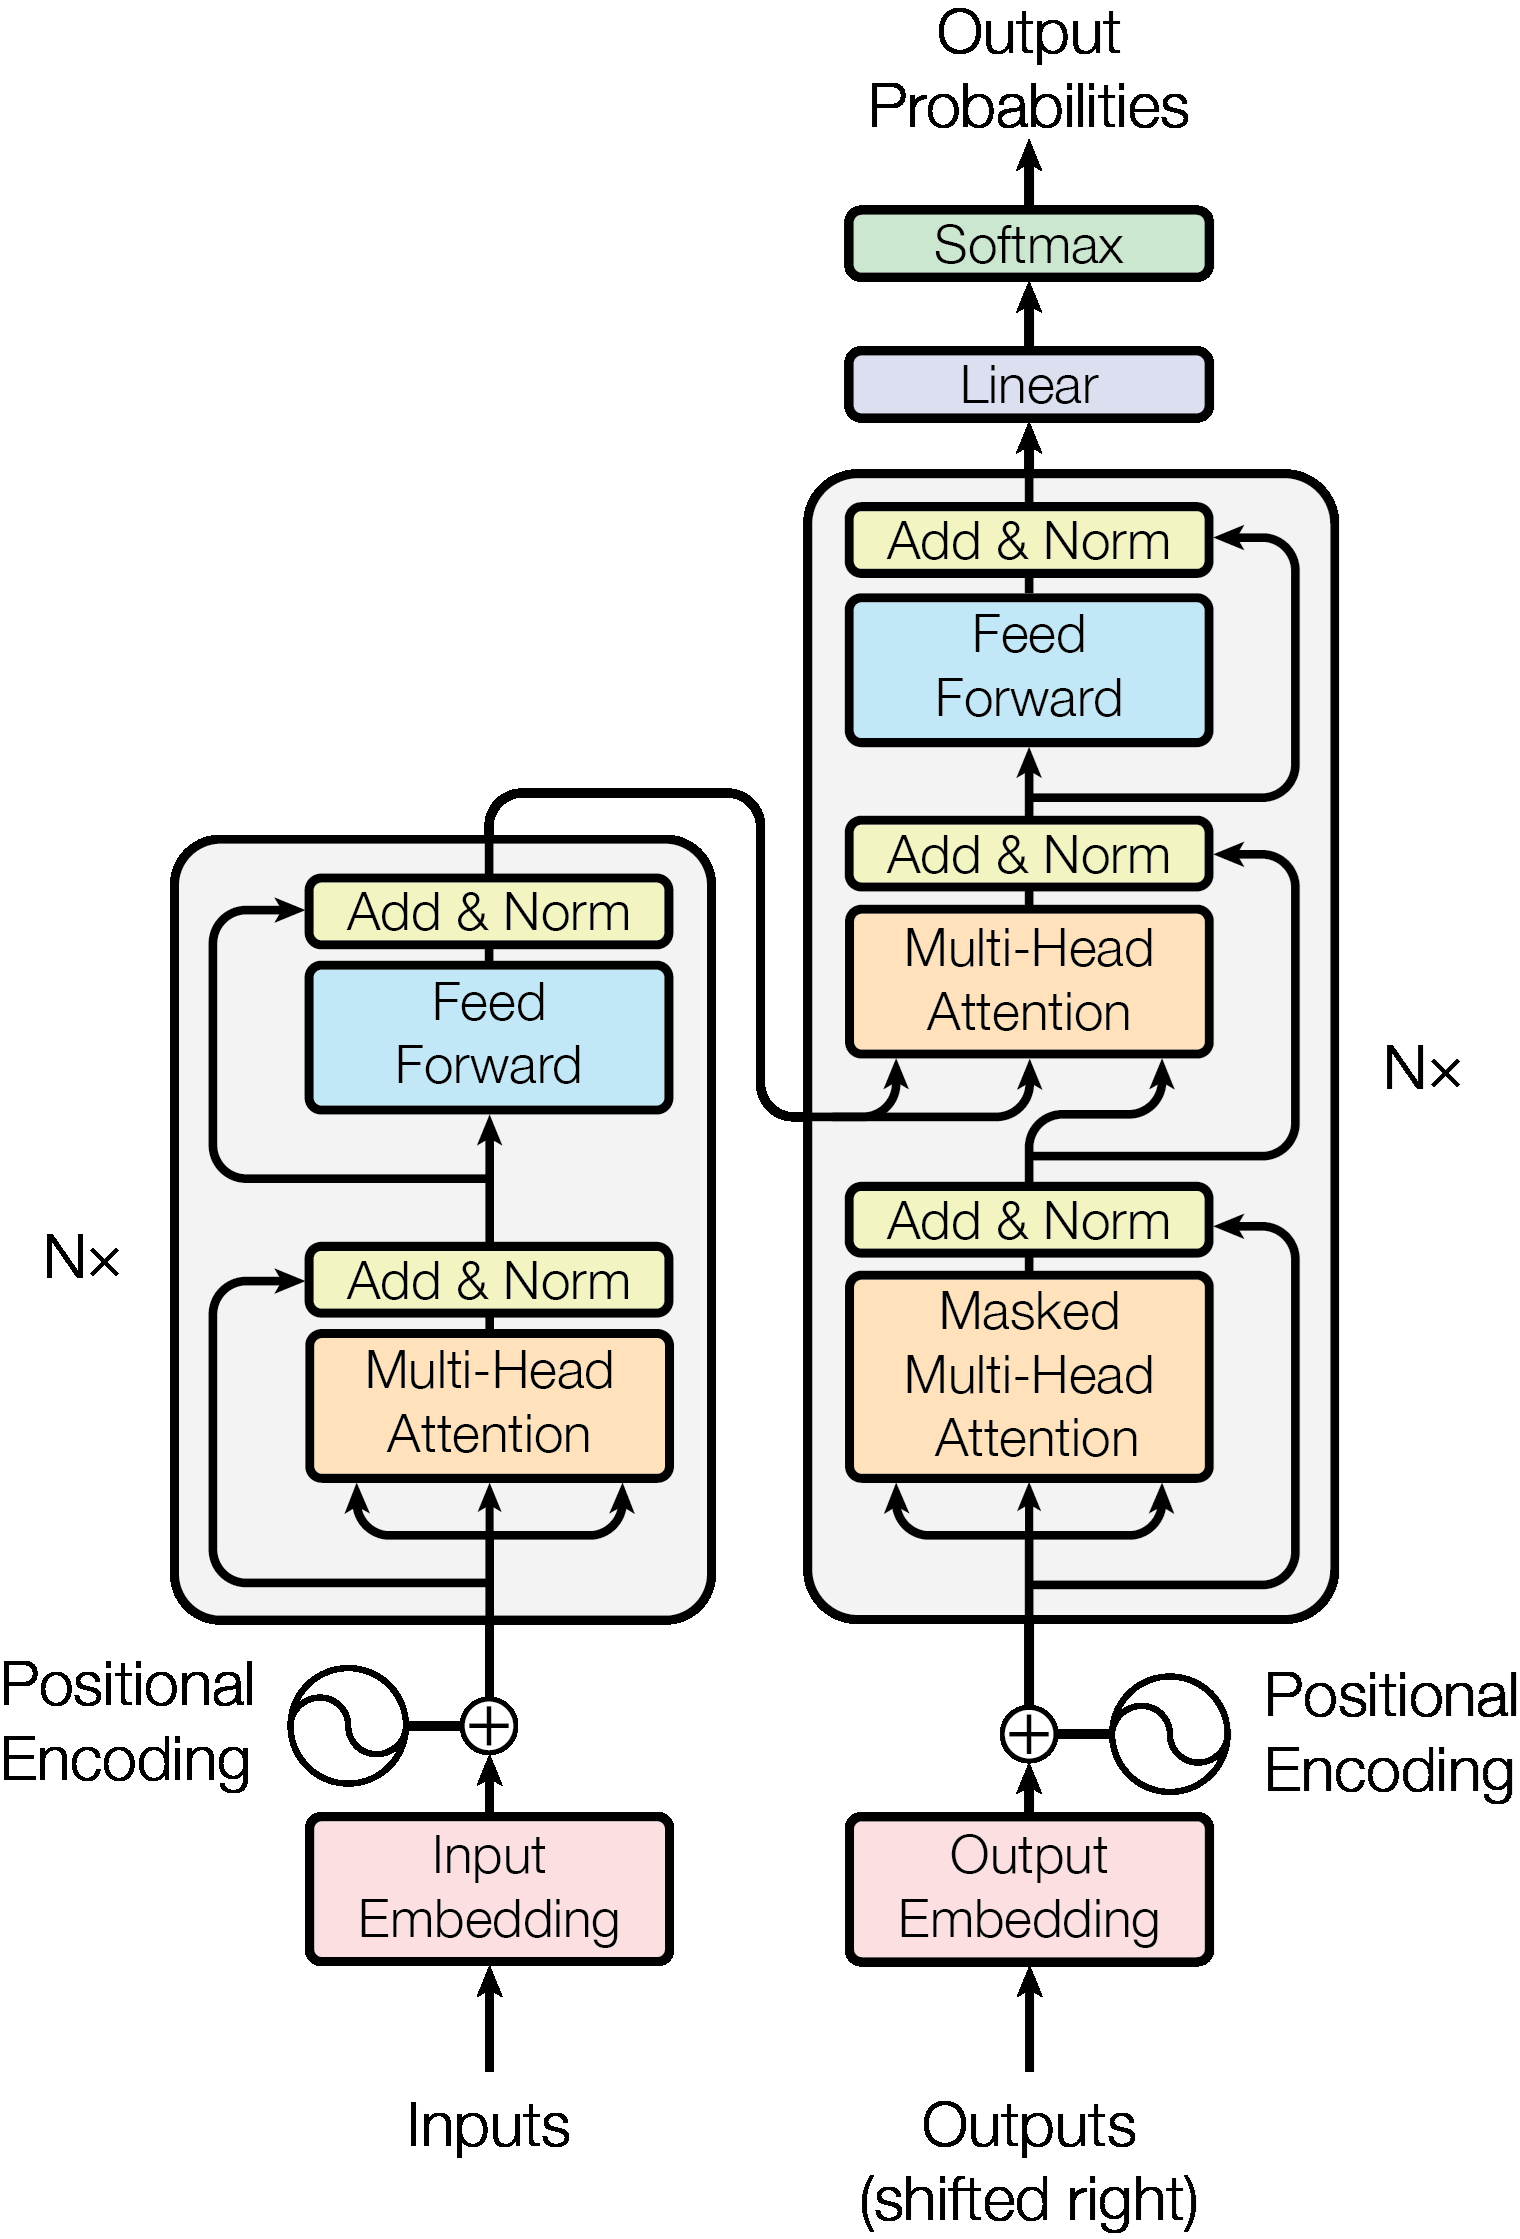
<p>Large Language Models (LLMs) have revolutionized the field of natural language processing (NLP) with their remarkable ability to understand and generate human languages. Long story short, the most recent breakthrough came with the introduction of transformer architecture [1]. This architecture led to the development of well-known models such as the BERT [2] and the T5 [3] models. These pre-trained models use extensive data and computational resources to learn and extract informative representations from language essential for many downstream tasks in NLP.</p>

<p>These architectures, combined with the ever-growing use of GPUs and the scaling up of data, have led to highly efficient models for text generation. This process involves predicting each word (token) based on the probability distribution derived from the context of preceding words.</p>

<p align="center">
  <img src="/images/posts/Attention_model_Architecture.png" width="350" /><br />
  <small style="display: block; text-align: justify;">The Transformer architecture [1]</small>
</p>

<h2 id="protein-language-models">Protein Language Models</h2>
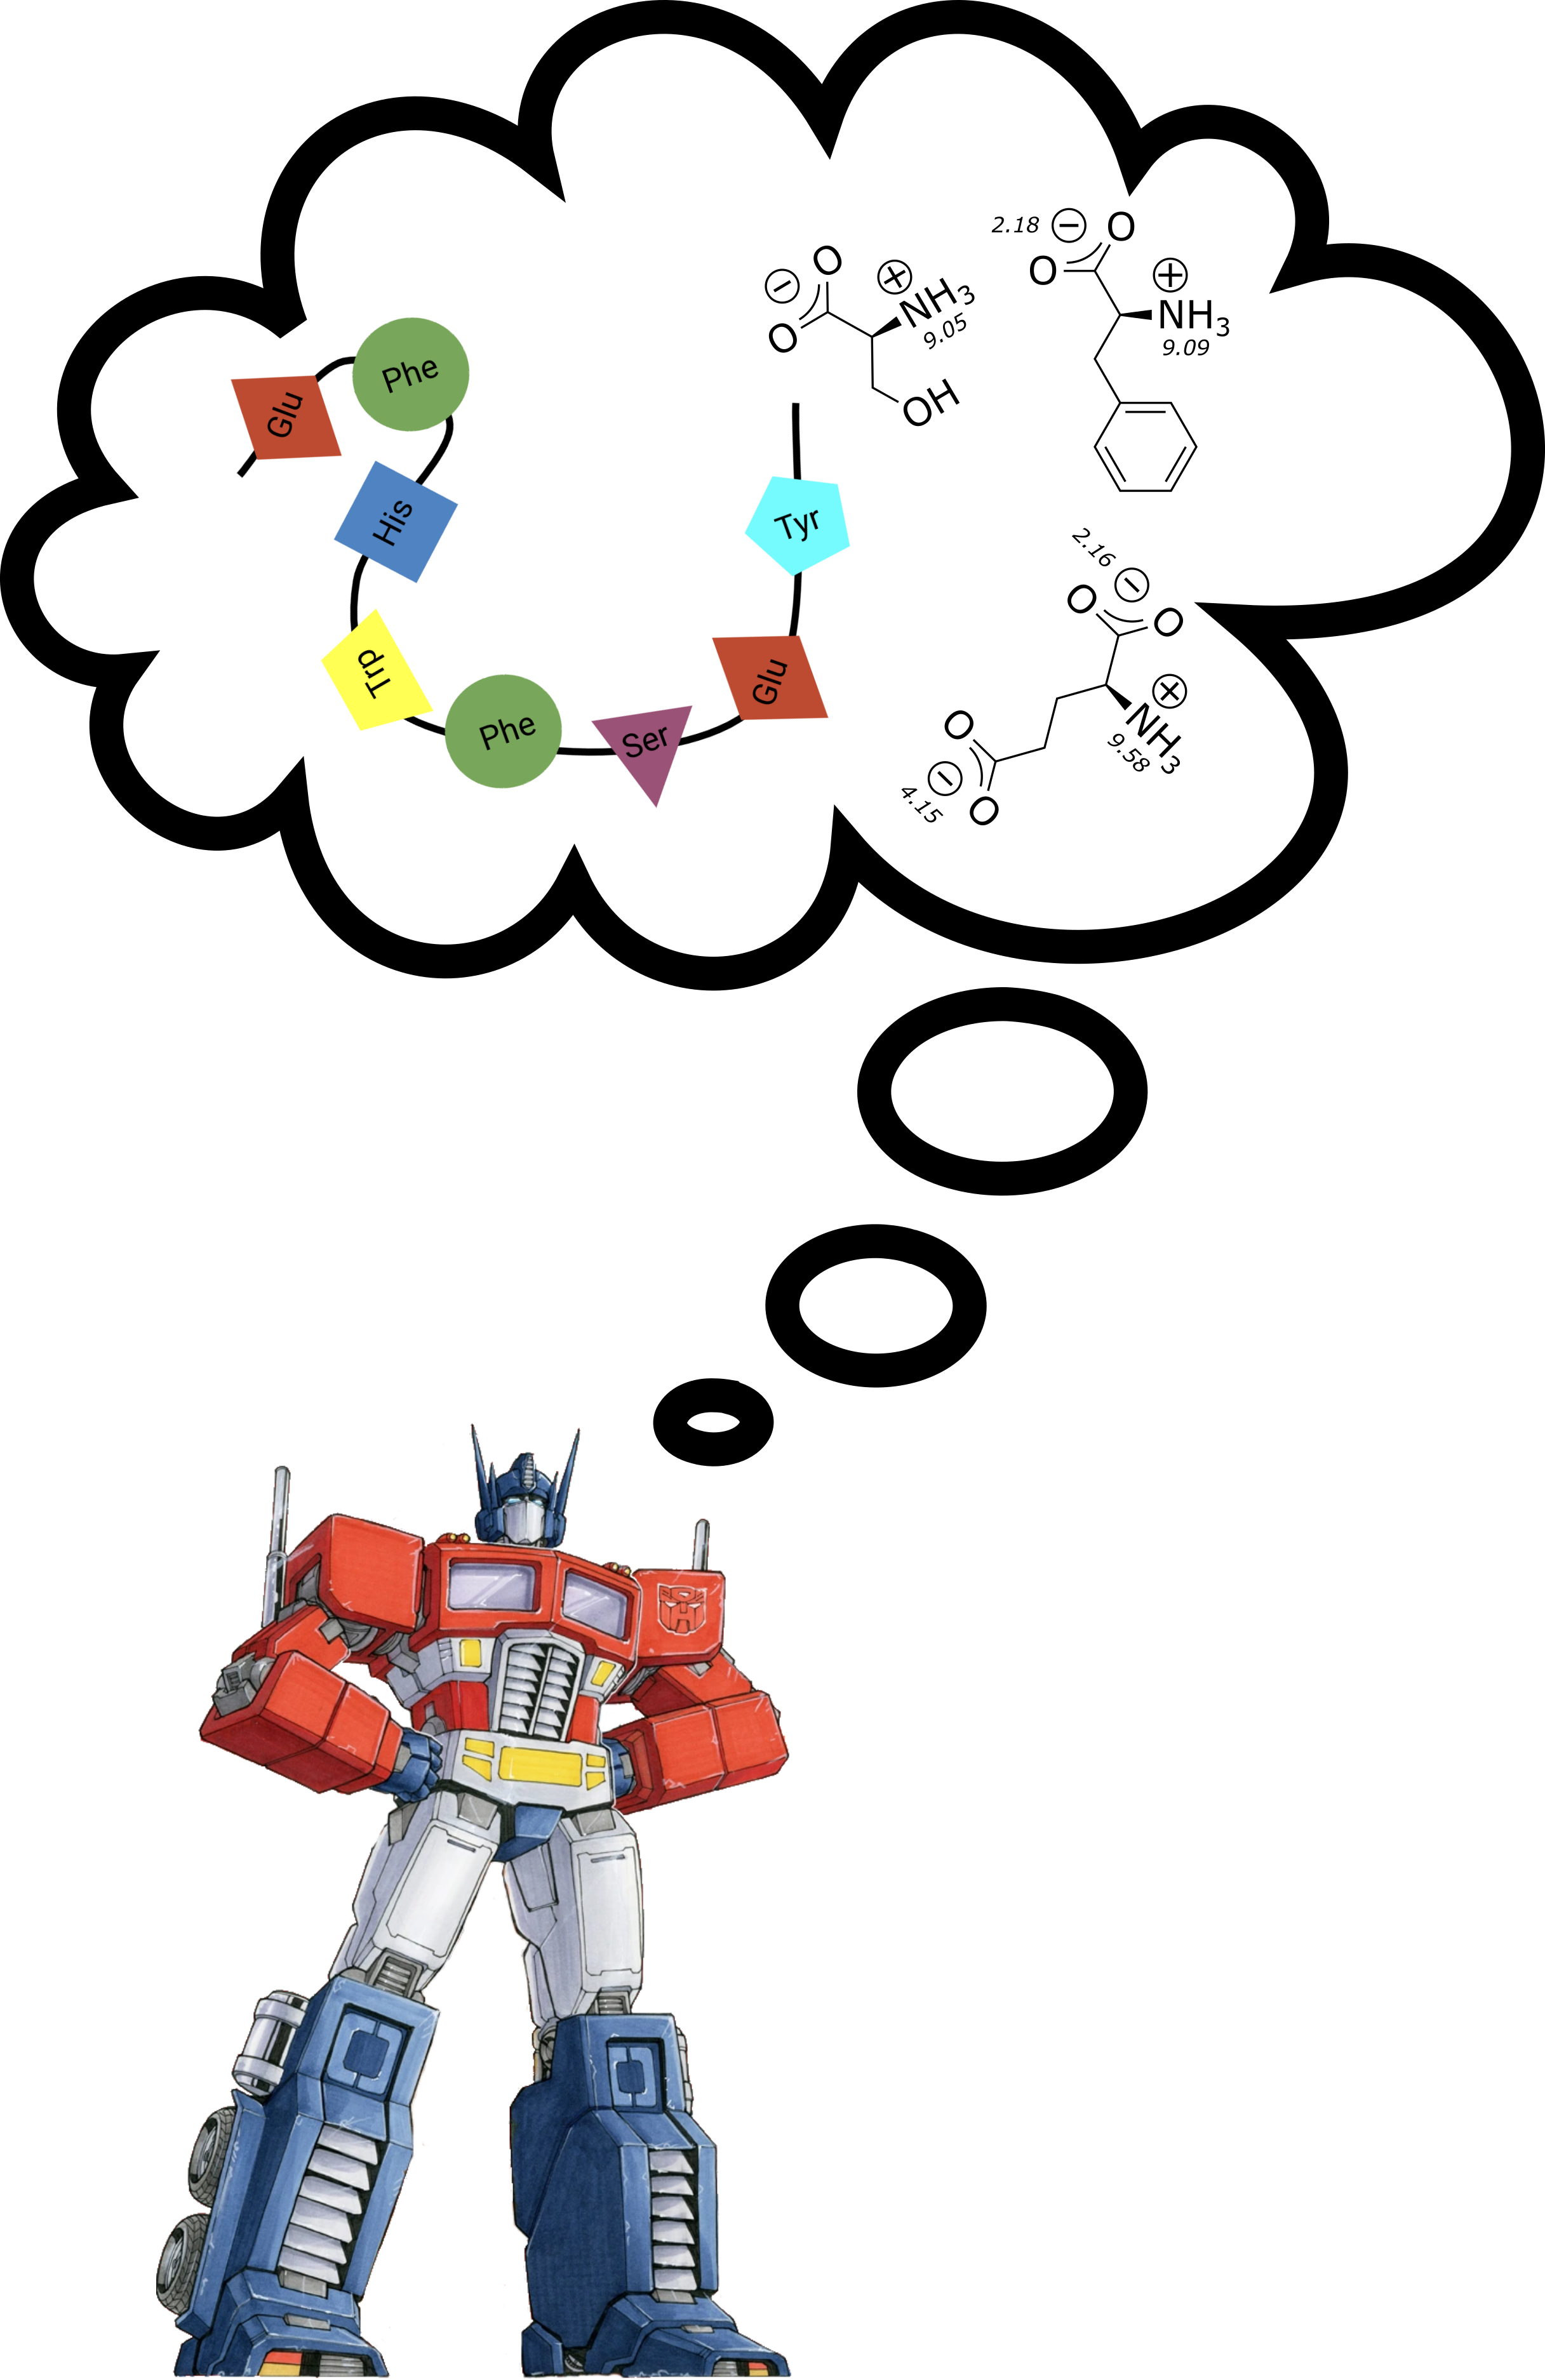
<p>Protein Language Models (pLMs) apply the same principles from NLP to capture the complex dependencies in protein “sentences”. A protein sentence is a sequence of amino acids (i.e. polypeptide) that determine protein properties. pLMs leverage transformer architectures, similar to those used in models like BERT, and help us to predict protein structures and functions. In addition, pLMs have opened up exciting possibilities in protein engineering and synthetic biology. By enabling high-throughput prediction of variant effects, they help us design de novo proteins with desired traits.</p>

<p align="center">
  <img src="/images/posts/Transformers_aaseq.png" width="350" /><br />
</p>

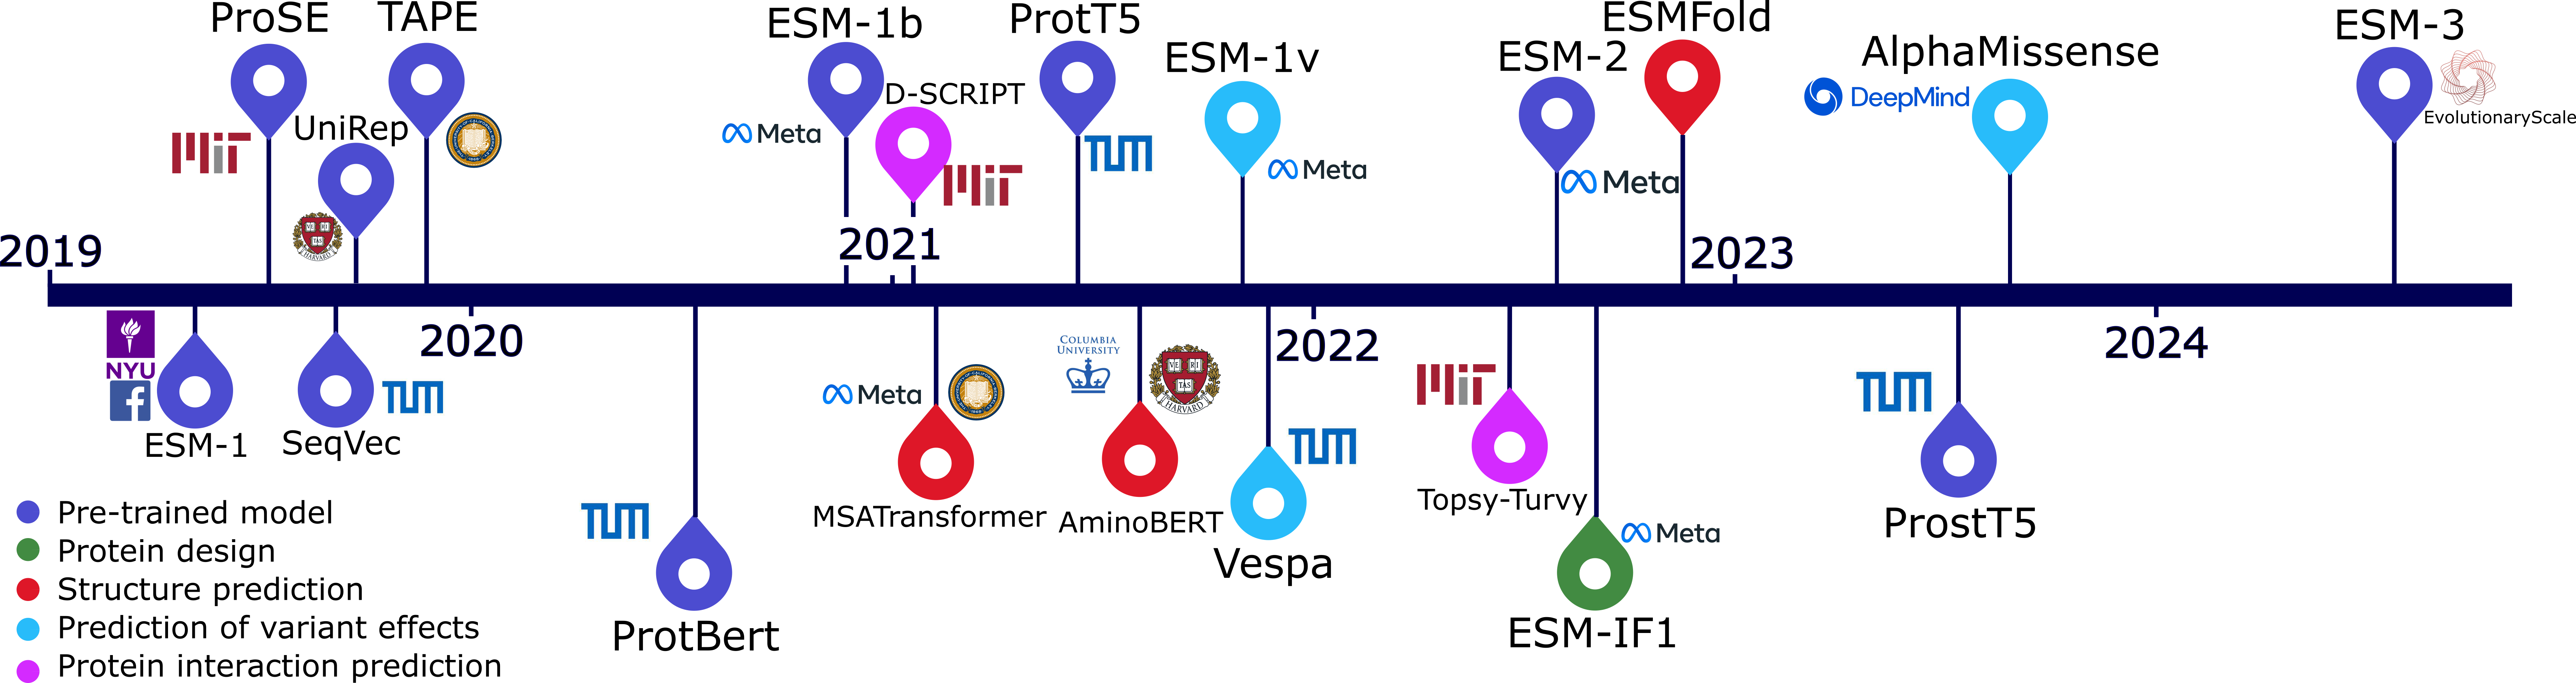
<p>pLMs [4-8] are trained on large datasets of protein sequences, such as those from the UniRef databases. These datasets include millions of protein sequences from various organisms and evolutionary backgrounds. Besides using amino acid sequences, some recent models [8] also include structural information represented as a sequence of structural tokens [9] (a structural “sentence”) to improve their predictive power.</p>

<p>Two breakthroughs in this field that have significantly advanced research in computational biology and drug discovery are the ProtTrans pLMs [5] and the Evolutionary Scale Modeling (ESM) pLMs [6]. These models extract context-aware embeddings for each amino acid necessary to predict various protein properties like function, stability, structure, inverse folding, and variant effects.</p>

<p align="center">
  <img src="/images/posts/PLM_timeline.png" width="1000" /><br />
  <small style="display: block; text-align: justify;">pLMs is a recent class of deep learning models designed to analyze protein sequences by leveraging techniques such as mask language modeling. Here is a timeline showing the evolution of this emerging field. pLMs can be applied in multiple protein-related applications, and some articles explore their diverse uses. To simplify the illustration, I highlighted the primary application of each tool. Similarly, these tools are the result of collaborative efforts across various institutions, and I have noted the key host institutions behind them.</small>
</p>

<h2 id="the-secret-behind-protein-language-models">The secret behind protein language models</h2>
<p>The recipe of pLM requires five ingredients:</p>

<ul>
  <li>Large datasets of protein sequences (e.g. UniProt)</li>
  <li>Self-supervised learning techniques</li>
  <li>Mask language modeling</li>
  <li>Transformer architecture (or sometimes LSTM!)</li>
</ul>

<p>and of course</p>

<ul>
  <li>Computational power (CPU, GPU, and TPU)</li>
</ul>

<p>The input is protein sequences tokenized into individual amino acids, sometimes accompanied by structural tokens, similar to how words are tokenized in NLP. A portion of the amino acids in the sequences is masked, and using self-supervised techniques the model is trained to predict these masked positions.</p>

<p>During training, the model learns from the sequence without requiring labeled examples (thanks to self-supervised learning), enabling it to capture the underlying patterns and relationships within protein sequences. The primary objective is to minimize the cross-entropy loss (i.e. log of perplexity), which measures how well the model predicts the masked amino acids based on the rest of the sequence. This metric measures how closely the predicted probability distribution of amino acids matches the desired (target) distribution.</p>

<html lang="en">
<head>
    <meta charset="UTF-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1.0" />
    <script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>
    <script id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js"></script>
</head>
<body>
    <p>
        \[
        \mathcal{L}(\mathbf{Y}, \mathbf{\hat{Y}}, \mathbf{M}) = - \frac{1}{\sum_{i=1}^n m_i} \sum_{i=1}^n m_i \log P(y_i | \mathbf{S})
        \]
    </p>
    <p>
        \(\mathbf{S} = [s_1, s_2, \ldots, s_n]\)
    </p>
    <p>
        \(\mathbf{Y} = [y_1, y_2, \ldots, y_n]\)
    </p>
    <p>
        \(\mathbf{\hat{Y}} = [\hat{y}_1, \hat{y}_2, \ldots, \hat{y}_n]\)
    </p>
    <p>
        \(\mathbf{M} = [m_1, m_2, \ldots, m_n]\)
    </p>
    <p>
        \(\mathbf{V} = [v_1, v_2, \ldots, v_{20}]\)
    </p>
    <p>
        \(y_i \in V\)
    </p>
</body>
</html>

<p>where S represents the input sequence of amino acids, M is a binary array (0 or 1) that indicates the masked positions within S, V is the vocabulary (20 amino acids), Y denotes the ground truth sequence represented by a probability distribution over vocabulary V for each position in the form of one-hot encoding, and Ŷ is the predicted probability distribution over the vocabulary V for each position.  The core of this equation is the following formula</p>

<html lang="en">
<head>
    <meta charset="UTF-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1.0" />
    <script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>
    <script id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js"></script>
</head>
<body>
<p>
  \(- log P(y_i | \mathbf{S})\)
</p>
</body>
</html>

<p>which is the negative log probability of the correct token yi given the input sequence S. This is the cross-entropy. The formula’s simplicity is due to the one-hot encoding of the ground truth Y. Here is why</p>

<html lang="en">
<head>
    <meta charset="UTF-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1.0" />
    <script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>
    <script id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js"></script>
</head>
<body>
<p>
  \( \hat{y}_i = [P(v_1|S), P(v_2|S),\ldots, P(v_{20}|S)] \)
</p>
</body>
</html>

<p>This is the predicted probability vector for position i over V.</p>

<html lang="en">
<head>
    <meta charset="UTF-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1.0" />
    <script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>
    <script id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js"></script>
</head>
<body>
<p>
\(
o_i = (o_{i1}, \ldots, o_{i20}), \quad
o_{ij} =
\begin{cases}
1, &amp; \text{if } v_j = y_i \\
0, &amp; \text{otherwise}
\end{cases}, \quad
o_i = [0, 0, 0, 1, \ldots, 0]
\)
</p>
</body>
</html>

<p>This is the representation of yi as one-hot encoding over V at position i. Then</p>

<html lang="en">
<head>
    <meta charset="UTF-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1.0" />
    <script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>
    <script id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-mml-chtml.js"></script>
</head>
<body>
<p>
  \( CE_i = - \sum_{j=1}^{20}  o_{ij} \times log P(v_j | S) = - log P(v_k | \mathbf{S}) = - log P(y_i | \mathbf{S}) \)
</p>
</body>
</html>

<h2 id="applications">Applications</h2>

<p>When used for inference, the model functions as an encoder, encoding protein sequences into vector representations (also known as embeddings) that capture their various properties.</p>

<p>pLMs can share their knowledge with other downstream predictive models through a process called transfer learning. This helps boost their performance, particularly for those with a limited amount of labeled data.</p>

<h2 id="conclusion">Conclusion</h2>
<p>pLMs are changing the field of computational biology by providing powerful tools for protein analysis, prediction, and design.</p>

<p>While we are still exploring how deeply pLMs truly grasp or understand the fundamental biophysical properties of proteins, their applications span across multiple domains, making them indispensable in modern biological research. Every year, we see more and more research papers, talks, and posters highlighting how much we rely on pLMs. It’s exciting to see their impact growing!</p>

<p>Stay tuned for our upcoming posts, where we will go deeper into pLMs and uncover the intriguing details behind their impressive performance!</p>

<p>References:</p>

<p>[1] Paper: <a href="https://proceedings.neurips.cc/paper_files/paper/2017/file/3f5ee243547dee91fbd053c1c4a845aa-Paper.pdf">Attention Is All You Need (Transformer architecture)</a></p>

<p>[2] Paper: <a href="https://arxiv.org/abs/1810.04805?amp=1">Bidirectional Encoder Representations from Transformers (BERT)</a></p>

<p>[3] Paper: <a href="https://arxiv.org/abs/1910.10683">Text-to-Text Transfer Transformer (T5)</a></p>

<p>[4] Paper: <a href="https://www.cell.com/cell-systems/fulltext/S2405-4712(21)00203-9?_returnURL=https%3A%2F%2Flinkinghub.elsevier.com%2Fretrieve%2Fpii%2FS2405471221002039%3Fshowall%3Dtrue">Protein Sequence Embeddings (ProSE)</a>, Code: <a href="https://github.com/tbepler/prose?tab=readme-ov-file">Github</a></p>

<p>[5] Paper: <a href="https://ieeexplore.ieee.org/document/9477085">ProtTrans</a>, Code: <a href="https://github.com/agemagician/ProtTrans">Github</a></p>

<p>[6] Paper: <a href="https://www.pnas.org/doi/10.1073/pnas.2016239118">Evolutionary Scale Modelling (ESM)</a>, Code: <a href="https://github.com/facebookresearch/esm">Github</a></p>

<p>[7] Paper: <a href="https://www.science.org/doi/abs/10.1126/science.ade2574">ESMFold</a>, Code: <a href="https://github.com/facebookresearch/esm">Github</a></p>

<p>[8] Paper: <a href="https://academic.oup.com/nargab/article/6/4/lqae150/7901286?login=false">Protein structure-sequence T5 (ProstT5)</a>, Code: <a href="https://github.com/mheinzinger/ProstT5">Github</a></p>

<p>[9] Paper: <a href="https://www.nature.com/articles/s41587-023-01773-0">FoldSeek</a>, Code: <a href="https://github.com/steineggerlab/foldseek">Github</a></p>

<p>Also <a href="https://github.com/steineggerlab/foldseek">here</a> is an excellent blog post on how to use pLMs for protein design and engineering with nice examples.</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Sanguage models" /><category term="Protein language models" /><category term="Sequence" /><summary type="html"><![CDATA[How protein language models like adapt transformer architectures to learn representations of protein sequences for structure and function prediction.]]></summary></entry><entry><title type="html">Equivariance and Invariance</title><link href="https://yassermb.github.io/posts/2024/07/equ/" rel="alternate" type="text/html" title="Equivariance and Invariance" /><published>2024-07-17T00:00:00+00:00</published><updated>2024-07-17T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2024/07/equ</id><content type="html" xml:base="https://yassermb.github.io/posts/2024/07/equ/"><![CDATA[<h1 id="the-building-blocks-of-geometric-deep-learning">The building blocks of geometric deep learning</h1>

<p>Geometric deep learning (GDL) addresses two main challenges in classical deep learning: the absence of a global reference frame and the curse of high dimensionality. It leverages low-dimensional geometric priors and an associated symmetry group (𝔾), such as translations, rotations, and permutations, under which certain properties of an object remain invariant.</p>

<p align="right">
  <img src="/images/posts/transformations.png" width="1000" /><br />
  <small style="display: block; text-align: justify;">The properties of a protein structure (object 𝑜) defined in Euclidean space (domain Ω), such as the binding affinity between two interactors, remain invariant under roto-translation transformations from SE(3) (group 𝔾). We use GDL to design neural networks 𝑓 that conserve these properties.</small>
</p>

<p>Let’s set the stage with a few key definitions:</p>

<p>Domain Ω (e.g. 3D Euclidean space) is an underlying space where we can define an object. We apply function space 𝕆 on domain Ω to define object 𝑜 (e.g. a protein 3D structure).</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( \mathbb{O}(\Omega, \mathbb{C})=\{o:\Omega \rightarrow \mathbb{C}\} \)
</p>

<p>where</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( \mathbb{C} \in \mathbb{R}^d \)
</p>

<p>is the range of values taken by objects defined on Ω.</p>

<p>Group 𝔾 is a set equipped with a binary operation ⊗, known as composition, and satisfies the following properties:</p>

<ul>
  <li>Closure:</li>
</ul>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( \forall g_1, g_2 \in \mathbb{G} \rightarrow g_1 \otimes g_2 \in \mathbb{G} \)
</p>

<ul>
  <li>Associativity:</li>
</ul>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( \forall g_1, g_2, g_3 \in \mathbb{G} \rightarrow (g_1 \otimes g_2) \otimes g_3 =  g_1 \otimes (g_2 \otimes g_3) \)
</p>

<ul>
  <li>Identity:</li>
</ul>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( \forall g \in \mathbb{G}, \exists! e \in \mathbb{G} → (g \otimes e) = (e \otimes g) = g \)
</p>

<ul>
  <li>Inverse:</li>
</ul>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( \forall g \in \mathbb{G}, \exists! g^{-1} \in \mathbb{G} → g \otimes g^{-1} = g^{-1} \otimes g = e \)
</p>

<p>Each transformation g ∈𝔾 has a representation 𝑝⁡(g). For example, if g is a translation in Euclidean space then,</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>\( p(g) \in \mathbb{R}^3 \)
</p>

<p>is a translation matrix.</p>

<p>If domain Ω is symmetrical under group 𝔾 then it ensures that the properties of the object 𝑜 remain unchanged despite transformations defined within 𝔾. The Euclidean space is endowed with roto-translation symmetries and the group that contains the roto-translation transformations is called the special Euclidean group or 𝑆⁢𝐸⁡(𝑛), where n is the number of dimensions. This gives us inductive bias which eventually leads to the definition of invariant and equivariant functions, the building blocks of GDL.</p>

<h2 id="equivariant-block">Equivariant block</h2>

<p>The function 𝑓1 (e.g. a neural network) is equivariant under the transformation g if applying g to the input object 𝑜 results in the same transformation being applied to the output. GDL employs patch-wise symmetry groups to achieve this and ensures that the entire architecture remains locally equivariant by stacking multiple locally equivariant layers.</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( f_1: \mathbb{O}(\Omega) \rightarrow \mathbb{O}(\Omega) \)
<br /><br />
\( f_1(p(g)o) = p(g)f_1(o), g \in \mathbb{G} \)
</p>

<p>where 𝑓1 is a function defined on the object to extract its properties and is equivariant to the group 𝔾.</p>

<h2 id="invariant-block">Invariant block</h2>

<p>We can formulate invariant function 𝑓2 (again a neural network) that benefits from the geometric priors of domain Ω:</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( f_2: \mathbb{O}(\Omega) \rightarrow \mathbb{Y} \)
<br /><br />
\( f_2(p(g)o) = f_2(o), g \in \mathbb{G} \)
</p>

<p>where 𝑓2 is a function defined on the object to extract its properties and is invariant to the group 𝔾.</p>

<p>In most problems, the final layer is designed to make the whole process globally invariant. The integration of equivariant and invariant blocks minimizes the number of trainable parameters by utilizing kernels with shared weights (a simple example is convolutional neural networks) and removes the necessity for data augmentation. </p>

<h2 id="pipeline">Pipeline</h2>

<p>Now let’s see how we can put together a complete GDL pipeline!</p>

<p>If domain Ω’ is a compact (coarse-grained) version of  domain Ω (Ω′ ⊆ Ω), then we can define the building blocks of the GDL approaches:</p>

<p>Linear  𝔾-equivariant layer</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( f_1: \mathbb{O}(\Omega, \mathbb{C}) \rightarrow \mathbb{O}(\Omega', \mathbb{C'}) \)
<br /><br />
\( \forall g \in \mathbb{G}, \forall o \in \mathbb{O}(\Omega, \mathbb{C}) \rightarrow f_1(p(g)o) = p(g)f_1(o) \)
</p>

<p>𝔾-invariant layer (global pooling)</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( f_2: \mathbb{O}(\Omega, \mathbb{C}) \rightarrow \mathbb{Y} \)
<br /><br />
\( \forall g \in \mathbb{G}, \forall o \in \mathbb{O}(\Omega, \mathbb{C}) \rightarrow f_2(p(g)o) = f_2(o) \)
</p>

<p>Local pooling (coarsening)</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( p: \mathbb{O}(\Omega, \mathbb{C}) \rightarrow \mathbb{O}(\Omega', \mathbb{C}) \)
</p>

<p>Nonlinearity</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( \sigma: \mathbb{O}(\Omega, \mathbb{C}) \rightarrow \mathbb{O}(\Omega, \mathbb{C'}) \)
</p>

<p>Now we simply concatenate these blocks to create 𝔾-invariant function:</p>

<script src="https://polyfill.io/v3/polyfill.min.js?features=es6"></script>

<script type="text/javascript" id="MathJax-script" async="" src="https://cdn.jsdelivr.net/npm/mathjax@3/es5/tex-chtml.js"></script>

<p>
\( \mathbb{F}: \mathbb{O}(\Omega, \mathbb{C}) \rightarrow \mathbb{Y} \)
<br /><br />
\( \mathbb{F} = f_2 \odot \sigma_n \odot f_{1,n} \odot p_{n-1} \odot ... \odot p_1 \odot \sigma_1 \odot f_{1,1} \)
</p>

<p>Two standout GDL frameworks that incorporate equivariant and invariant blocks are Graph Neural Networks (GNNs) and Group Equivariant Convolutional Networks (G-CNN). These are widely used in computational and structural biology for many tasks, including quality assessment of protein structure models, protein structure prediction, protein interface prediction, and protein design.</p>

<p>I highly recommend the resources below. Back in 2021, I enjoyed reading [1]! It was so well-explained and easy to follow - I learned a lot from it.</p>

<ol>
  <li>
    <p><a href="https://arxiv.org/abs/2104.13478">Bronstein et al., 2021: “Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges”</a></p>
  </li>
  <li>
    <p><a href="https://geometricdeeplearning.com/">Geometric Deep Learning</a></p>
  </li>
</ol>

<p>Here are also some amazing resources from Amsterdam Machine Learning Lab (AMLab) and the University of Amsterdam:</p>

<ul>
  <li>Hands-on notebooks: <a href="https://uvadlc-notebooks.readthedocs.io/en/latest/tutorial_notebooks/DL2/Geometric_deep_learning/tutorial1_regular_group_convolutions.html">GDL - Regular Group Convolutions</a> and <a href="https://colab.research.google.com/drive/1h7U15-qFC2yy6roRIfLPk5TSlo6sONsm">Group Equivariant Neural Networks</a>.</li>
  <li>Lectures on <a href="https://www.youtube.com/watch?v=z2OEyUgSH2c&amp;list=PL8FnQMH2k7jzPrxqdYufoiYVHim8PyZWd">Group Equivariant Deep Learning</a></li>
</ul>

<p>This blog is also nice:</p>

<p><a href="https://www.youtube.com/watch?v=z2OEyUgSH2c&amp;list=PL8FnQMH2k7jzPrxqdYufoiYVHim8PyZWd">Geometric Deep Learning: Group Equivariant Convolutional Networks</a></p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Equivariant" /><category term="Invariant" /><category term="Group theory" /><summary type="html"><![CDATA[An introduction to equivariance and invariance in geometric deep learning, the symmetry groups and mathematical foundations behind models that respect roto-translation of protein structures.]]></summary></entry><entry><title type="html">Geometric Deep Learning</title><link href="https://yassermb.github.io/posts/2024/07/gdl/" rel="alternate" type="text/html" title="Geometric Deep Learning" /><published>2024-07-08T00:00:00+00:00</published><updated>2024-07-08T00:00:00+00:00</updated><id>https://yassermb.github.io/posts/2024/07/gdl</id><content type="html" xml:base="https://yassermb.github.io/posts/2024/07/gdl/"><![CDATA[<h1 id="what-is-geometric-deep-learning">What is Geometric Deep Learning?</h1>

<p>Often, during events or conferences, when I explain our work I have to mention Geometric Deep Learning (GDL) as a cornerstone of our research. But this usually leads to questions like, “What is Geometric Deep Learning?” or comments like, “This is the first time I’m hearing this term!” Despite being an important and well-established field, I have noticed that it remains relatively obscure, particularly outside specialized areas like structural biology, computer vision, and physics. Understanding this concept is also crucial for grasping emerging technologies, such as de novo protein design. So I thought I’d shine some light and give a simple definition of GDL. I believe this will lay a good foundation for exploring topics like the application of generative AI in therapeutic solutions.</p>

<p>Let’s begin with a simple question:</p>

<p>How can we build a model that learns and analyzes the structure of a protein, a highly complex 3D object in the Cartesian system?</p>

<p>We can use traditional deep learning algorithms but then we run into two major challenges:</p>

<ol>
  <li>
    <p>The lack of a global frame of reference. Traditional deep learning algorithms are sensitive to transformations in input data (e.g., image rotation) and might perceive transformed data as a new, unseen sample. In the context of proteins, features like biological function or binding affinity are irrelevant to global translations and orientations of the protein structure.</p>
  </li>
  <li>
    <p>The complexity of the 3D structures leading to the curse of high dimensionality.</p>
  </li>
</ol>

<p>GDL addresses these challenges by using low-dimensional geometric priors and associated symmetry groups, ensuring invariance to transformations like rotations and permutations while maintaining the properties of protein structures intact.</p>

<p>But GDL isn’t just about 3D objects! It extends deep learning techniques to non-Euclidean domains like graphs and manifolds. For instance, proteins can be represented as graphs, where amino acids are nodes connected by edges. They can also be represented as meshes or point clouds. Out of all the different ways to represent/learn geometric data, graph representation learning is my favorite. It is an exciting category of architectures known as Graph Neural Networks (GNNs). These networks learn intricate, high-dimensional representations of graphs using propagation (message passing) between nodes via edges. GNNs deserve their own post!</p>

<p align="center">
  <img src="/images/posts/GDL.png" width="350" /><br />
  <small style="display: block; text-align: justify;">We can represent a protein structure, or any (bio-)molecule, as a graph. Nodes can be amino acids and edges can be covalent or molecular interactions. Nodes communicate with each other and update their feature vectors through a process known as message passing. This representation allows us to leverage graph learning architectures and learn the properties of the structure.</small>
</p>

<p>Here are some awesome visualizations that highlight the importance of equivariance in GDL. It’s a core feature where the output of an equivariant layer undergoes the same predictable transformation as its input.</p>

<p align="center">
  <img src="/images/posts/vectorfield.gif" width="800" /><br />
  <small>Source: https://github.com/QUVA-Lab/e2cnn</small>
</p>

<p>In the world of protein structures, thanks to the local equivariance property, not only does GDL find structural motifs regardless of their position and orientation, but it also considers the relative orientation and position of these motifs which is necessary for the right information aggregation.</p>

<p align="center">
  <img src="/images/posts/GDL_Protein_Cat.png" width="1000" /><br />
  <small>Source: https://onlinelibrary.wiley.com/doi/abs/10.1002/prot.26235</small>
</p>

<p>Also, check out <a href="https://youtu.be/ENLJACPHSEA">this video</a> from [3].</p>

<p>Many researchers from different groups contributed to this field. Thanks to their mathematically rigorous work, we now have a solid foundation for GDL, with numerous applications across different domains. Here are a few of these references:</p>

<ol>
  <li>
    <p><a href="https://arxiv.org/abs/2104.13478">Bronstein et al., 2021: “Geometric Deep Learning: Grids, Groups, Graphs, Geodesics, and Gauges”</a></p>
  </li>
  <li>
    <p><a href="https://proceedings.neurips.cc/paper/2019/hash/45d6637b718d0f24a237069fe41b0db4-Abstract.html">Weiler &amp; Cesa, 2019: “General e (2)-equivariant steerable CNNs”</a></p>
  </li>
  <li>
    <p><a href="https://proceedings.neurips.cc/paper/2018/hash/488e4104520c6aab692863cc1dba45af-Abstract.html">Weiler et al., 2018: “3D steerable CNNs: Learning rotationally equivariant features in volumetric data”</a></p>
  </li>
  <li>
    <p><a href="https://proceedings.neurips.cc/paper/2020/hash/15231a7ce4ba789d13b722cc5c955834-Abstract.html">Fuchs et al., 2020: “Se (3)-transformers: 3D roto-translation equivariant attention networks”</a></p>
  </li>
  <li>
    <p><a href="https://www.jmlr.org/papers/v23/20-852.html">Chami et al., 2022: “Machine learning on graphs: A model and comprehensive taxonomy”</a></p>
  </li>
</ol>

<p>In future posts, I’ll go deeper into the details and share educational resources where you can learn more about GDL.</p>]]></content><author><name>Yasser Mohseni, PhD</name><email>yasser.mohseni-behbahani@u-paris.fr</email></author><category term="Deep learning" /><category term="Geometric" /><category term="Proteins" /><summary type="html"><![CDATA[An introduction to Geometric Deep Learning: how symmetry-aware neural networks model protein structures as graphs, meshes, and point clouds using invariance and equivariance.]]></summary></entry></feed>